Tutorial
Install IBM Storage Fusion to back up and restore Kubernetes workloads
Manage, recover, and access your mission-critical data and applicationsIBM Storage Fusion is a container-native data platform for Red Hat OpenShift with enterprise-grade data storage and protection services. It offers an agile way to manage, recover and access your mission-critical data and Kubernetes applications on the Red Hat OpenShift Container Platform.
IBM Storage Fusion provides a streamlined way for organizations to discover, secure, protect and manage data from the edge, to the core data center, to the public cloud. It comprises IBM Storage Scale for container-native storage and IBM Storage Protect Plus for backup and restore capability.
There are two different IBM Storage Fusion deployments available:
- IBM Storage Fusion: A software-defined storage management solution with protection, replication, backup, and caching elements that can be run on existing hardware.
- IBM Storage Fusion HCI: "HCI" stands for hyper-converged infrastructure. This purpose-built, hyper-converged architecture is designed to deploy bare metal Red Hat OpenShift container management and deployment software alongside IBM Storage Fusion software.
IBM Storage Fusion also uses OADP and Velero. OADP (OpenShift APIs for Data Protection) is an operator from Red Hat to create backup and restore APIs in the OpenShift cluster.
OADP provides the following APIs:
- Backup
- Restore
- Schedule
- BackupStorageLocation
- VolumeSnapshotLocation
The OADP operator will also install Velero, an open source tool to backup and restore Kubernetes cluster resources, along with OpenShift plugins. Velero uses the Kubernetes API and Velero CSI Plug-In for persistent volume backup.
Backup and restore configurations that use OADP are relatively complex compared to IBM Storage Fusion. These configurations require OpenShift development skills, whereas IBM Storage simplifies the container backup and restore process with its user-friendly web portal.
In this tutorial, we will walk through the steps of setting up the container backup services using the IBM Storage Fusion 2.3 Operator for Red Hat OpenShift Kubernetes Service (ROKS) and OpenShift Data Foundation on IBM Cloud.
Note: This tutorial assumes that you are using the Linux operating system. If you are using a different operating system, you might have to adjust the command line instructions to reflect the commands for that operating system.
Prerequisites
- Obtain your entitlement key (to pull the required container images)
- Create the image pull secret
- Create an IBM Cloud Object Storage instance
- Install OpenShift CLI
Following are the system requirements for installing IBM Storage Fusion and Red Hat OpenShift Data Foundation on ROKS:
| Minimum Nodes/Hosts | CPU | RAM | Remarks |
|---|---|---|---|
| 3 Nodes (amd64: 64-bit Intel or AMD x86 hardware architecture) | 16 | 64GB | Flavor type: bx2.16x64 |
High-level architecture diagram


Steps
Following are detailed steps to install IBM Storage Fusion to backup and restore your containers:
Step 1. Set up a 3-node ROKS cluster
- Log in to IBM Cloud.
- In the left menu, click OpenShift > Clusters.
- Click Create Cluster.

- On the Create tab, in the "Select your setup" section, select Custom cluster and in the Infrastructure section, select VPC. Select your virtual private cloud from the drop-down menu. In the Cloud Object Storage list, select Object Storage instance.

- From the OpenShift version drop-down list, select OpenShift version 4.10.36.
- In OpenShift Container Platform (OCP) license, select Apply my Cloud Pack entitlement (if you have a Cloud Pack OCP entitlement license).
- In the Location drop-down list, select your location and configure your subnets. Note: You must have chosen a VPC before completing this step. See step 4, above.
- From the Worker pool drop-down list, select your pool.

- Click Change flavor and select the bx2.16x64 (16 vCPU 64GB RAM) instance.
- In the Operating system drop-down list, select RHEL 8.

- In the Cluster details section, add a meaningful name and tags for your cluster.
- When you have added all your cluster information, click Create. Your cluster is created based on your supplied information.

Step 2. Install OpenShift Data Foundation on a ROKS cluster
- In your IBM Cloud dashboard, go to the OpenShift clusters screen.
- Open the ROKS cluster that you created previously.
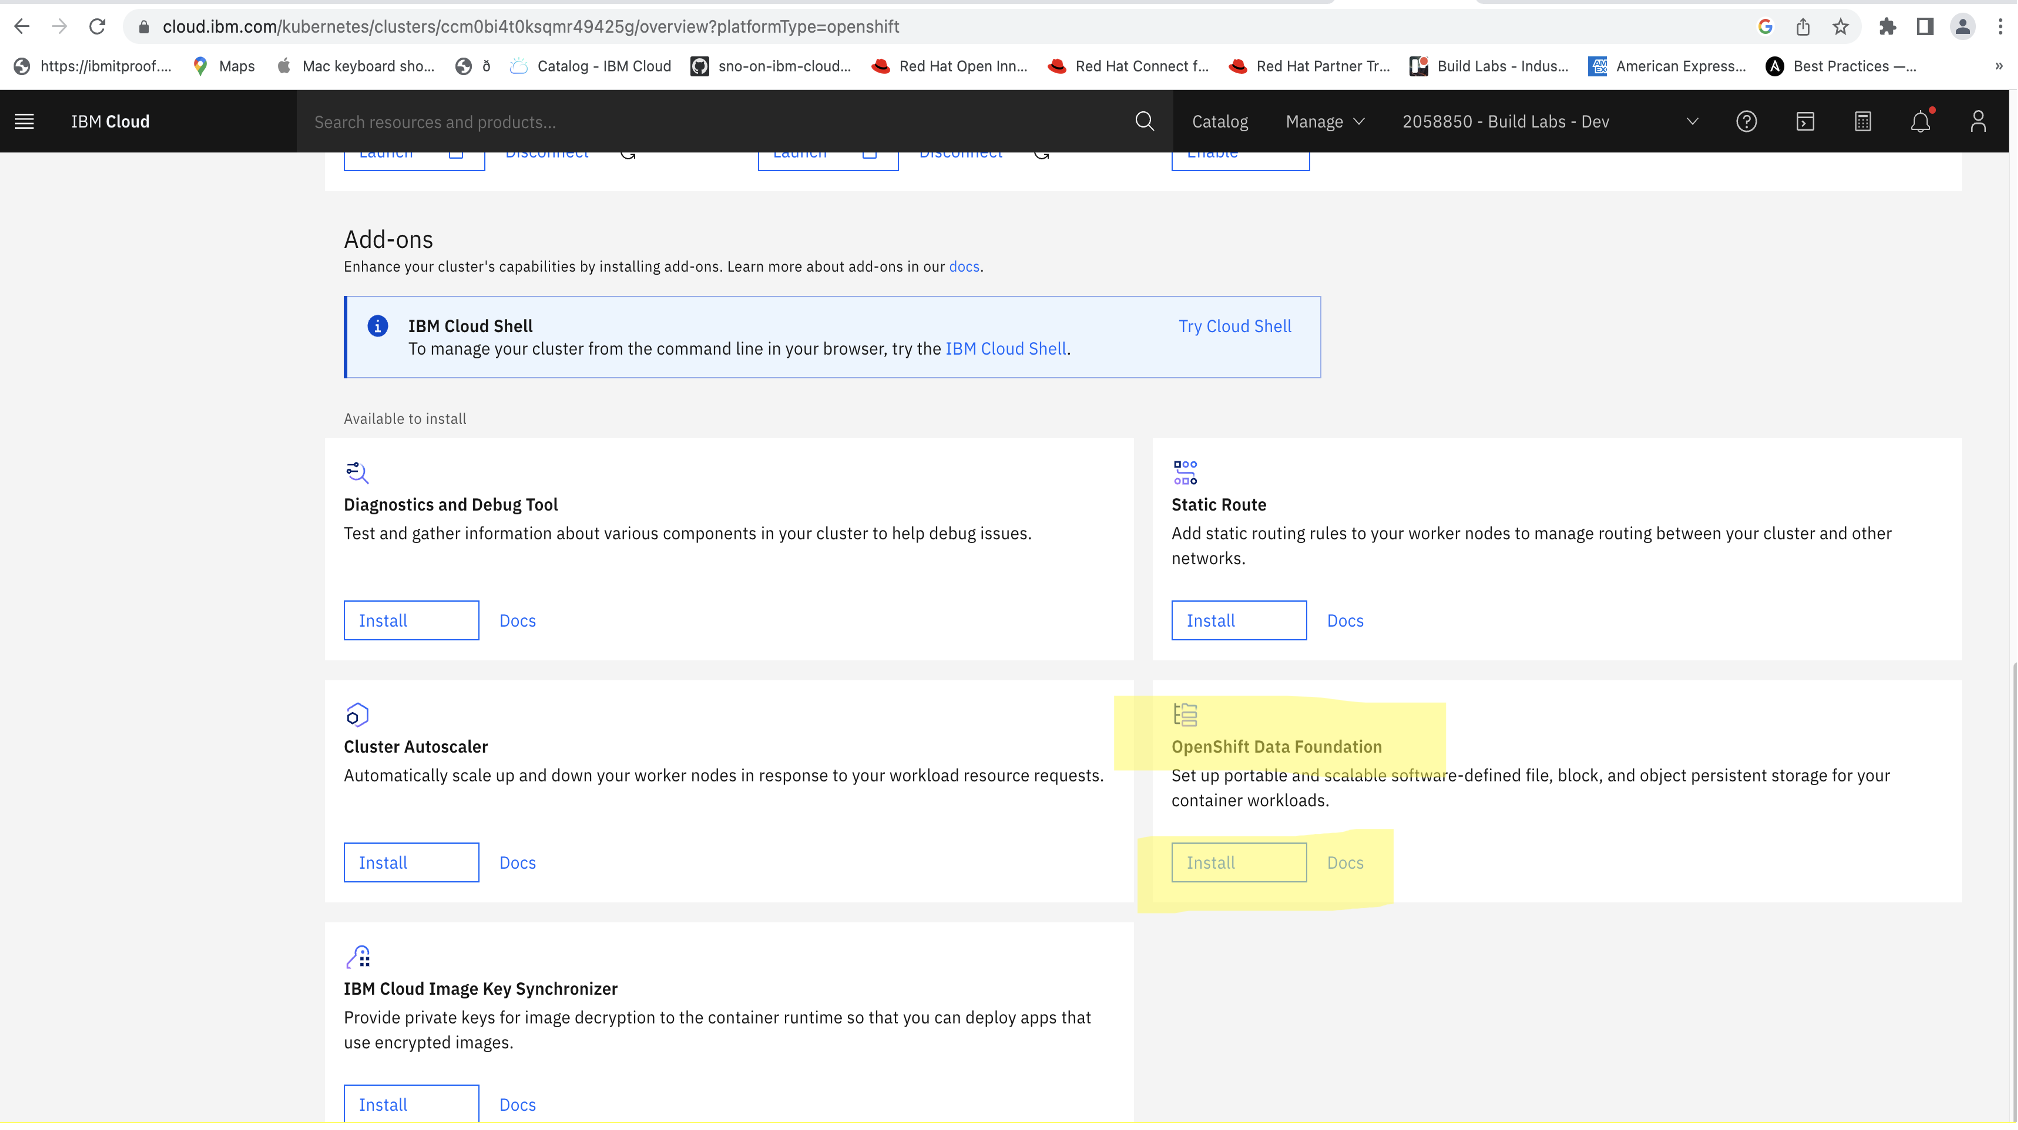
- In the OpenShift Data Foundation panel, click Install. The OpenShift Data Foundation is created.
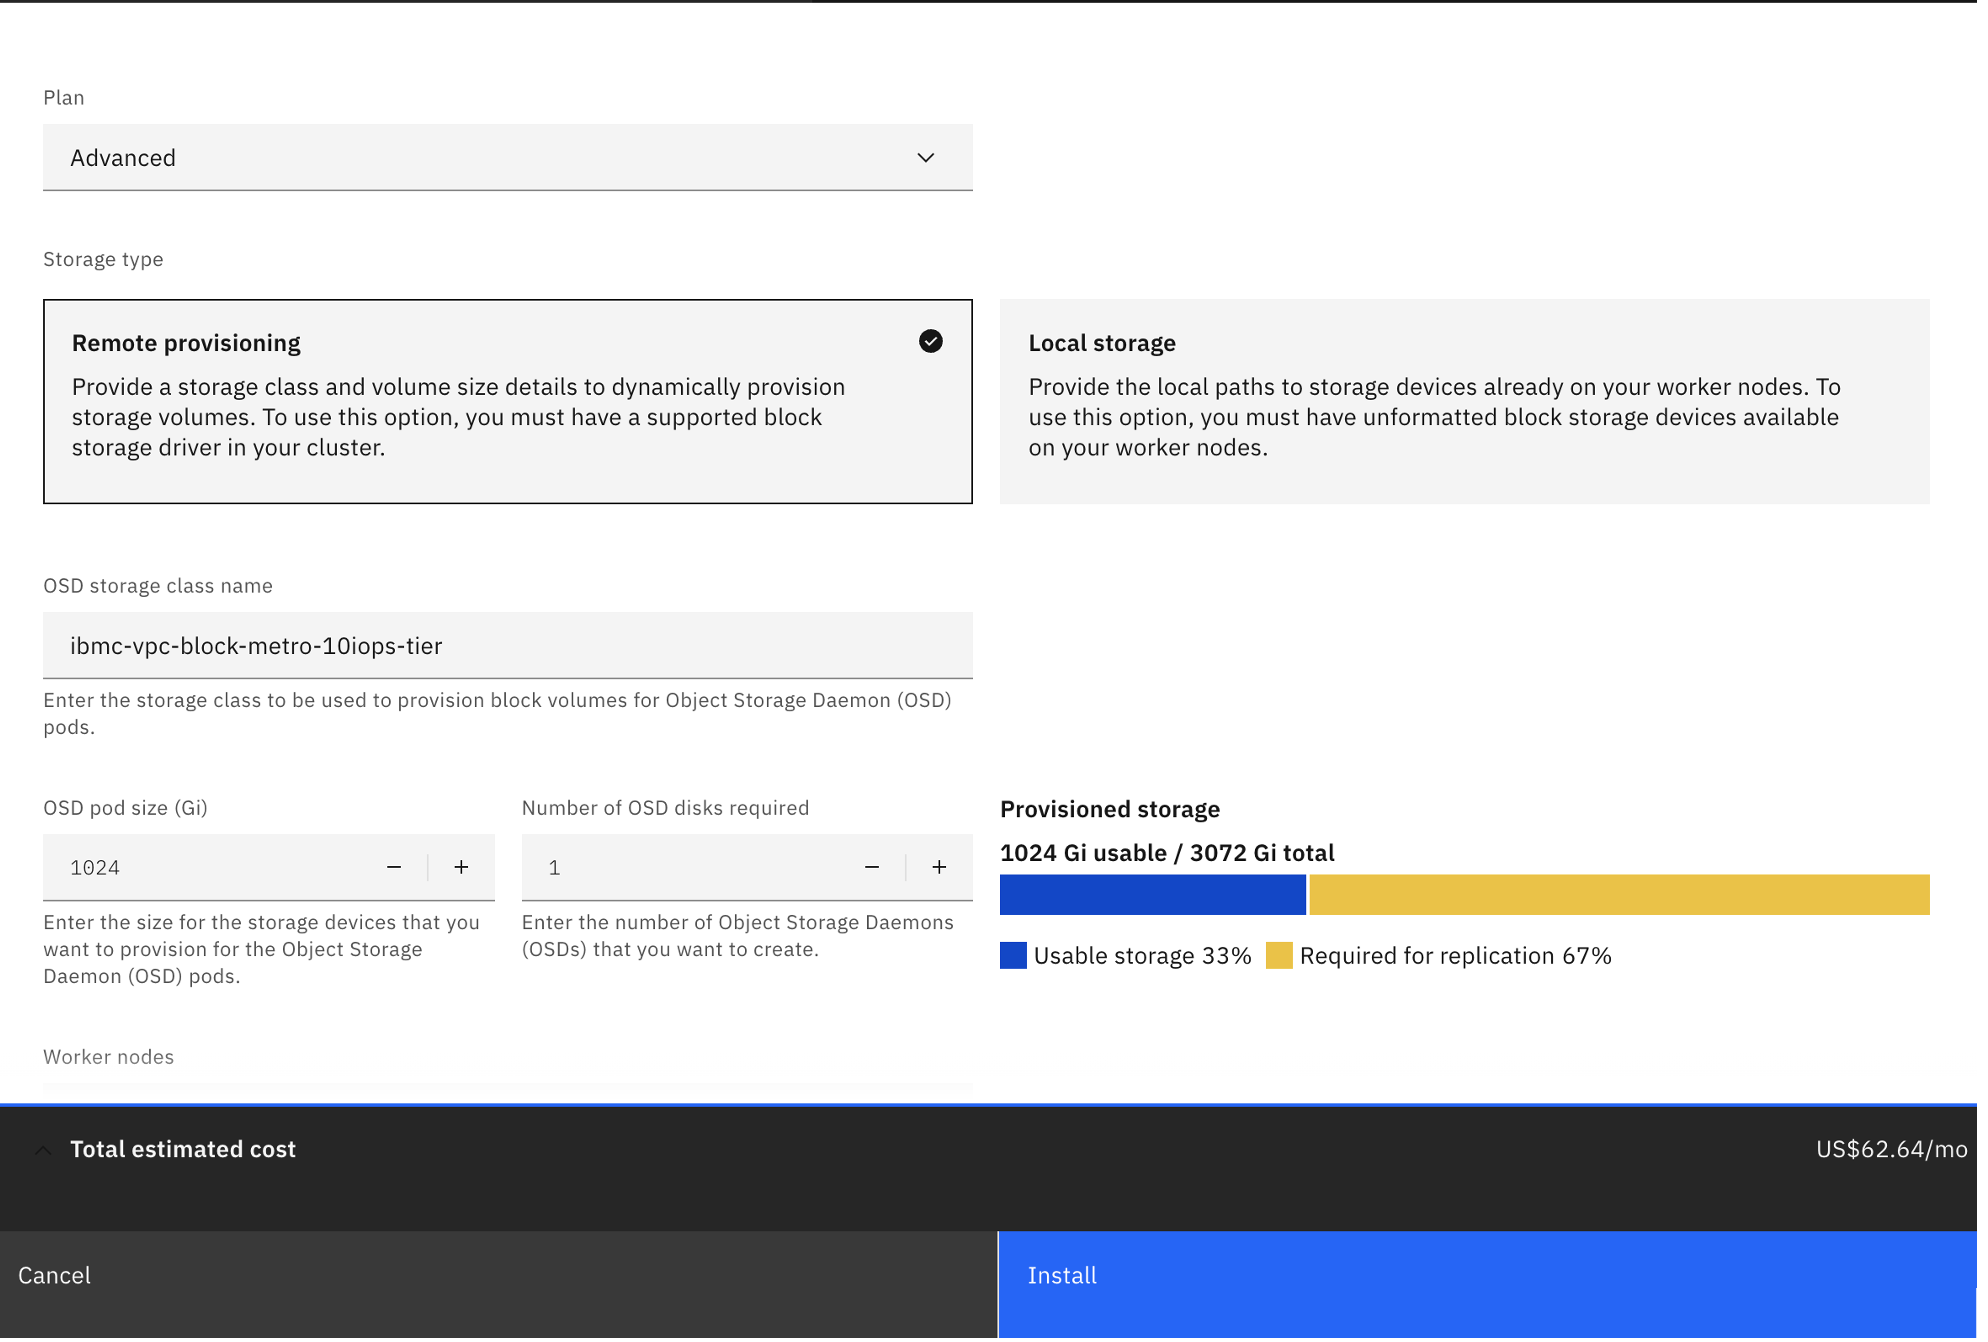
- In the OSD pod size (Gi) field, enter the total disk storage size requirement. For example, if you need 1TB of usable disk storage, enter 1024Gb. Click Install. This step provisions the additional disks to your OCP cluster nodes in IBM Cloud and converts them to an ODF Storage pool, which can be consumed by the POD/Container by Persistent Volume claim.
To verify that the OpenShift Data Foundation has installed successfully, log in to the OpenShift Console. In the left menu, click Storage > Data Foundation. You will see the ODF with a green status checkmark.

Confirm that the following OCS storge classes have been created:
- ocs-storagecluster-cephfs
- ocs-storagecluster-ceph-rbd
- ocs-storagecluster-ceph-rgw
- openshift-storage.noobaa.io
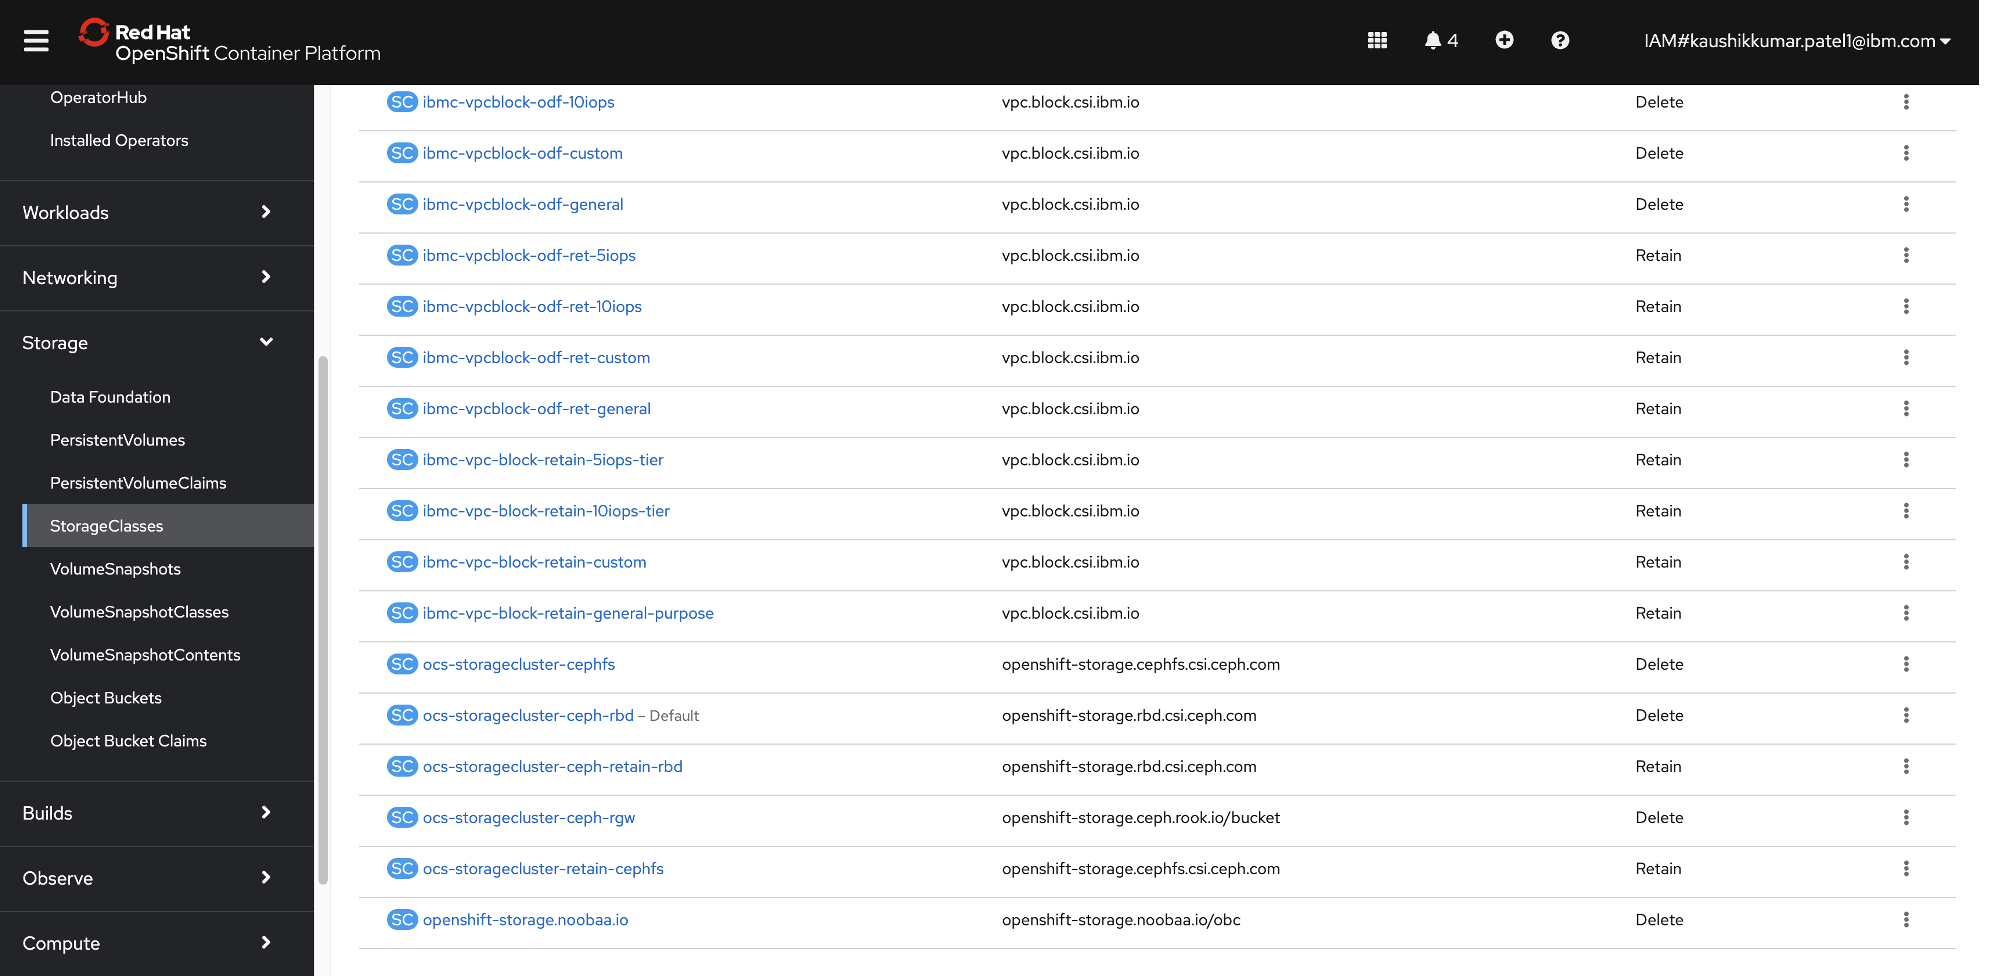
Step 3. Set the ODF StorageClass to default
The ODF StorageClass must be set to default for deploying the container application with a dynamic persistent volume on ODF storage:
- In the left menu of the IBM Cloud console, click Storage > StorageClasses.
- Click the ibm-vpc-block-10iops-tier StorageClass, which should be listed as the default. The Details page opens.

- In the Annotations section, click the pencil icon to edit. For the storageclass.kubernetes.io/is-default-class key, change the value to false. Click Save.

- On the StorageClasses page, click ocs-storagecluster-ceph-rbd in the StorageClass list.

- In the Annotations section, click the pencil icon to edit, and in the Edit annotations pop-up window, click Add more. Enter the key name storageclass.kubernetes.io/is-default-class, with a value of true. Click Save.

Step 4. Enable the IBM Operator catalog on OCP (if necessary)
- Connect to the OCP cluster remotely from any of local servers using your OpenShift cluster login. You can copy your login command by clicking the drop-down menu in the top right of the screen:
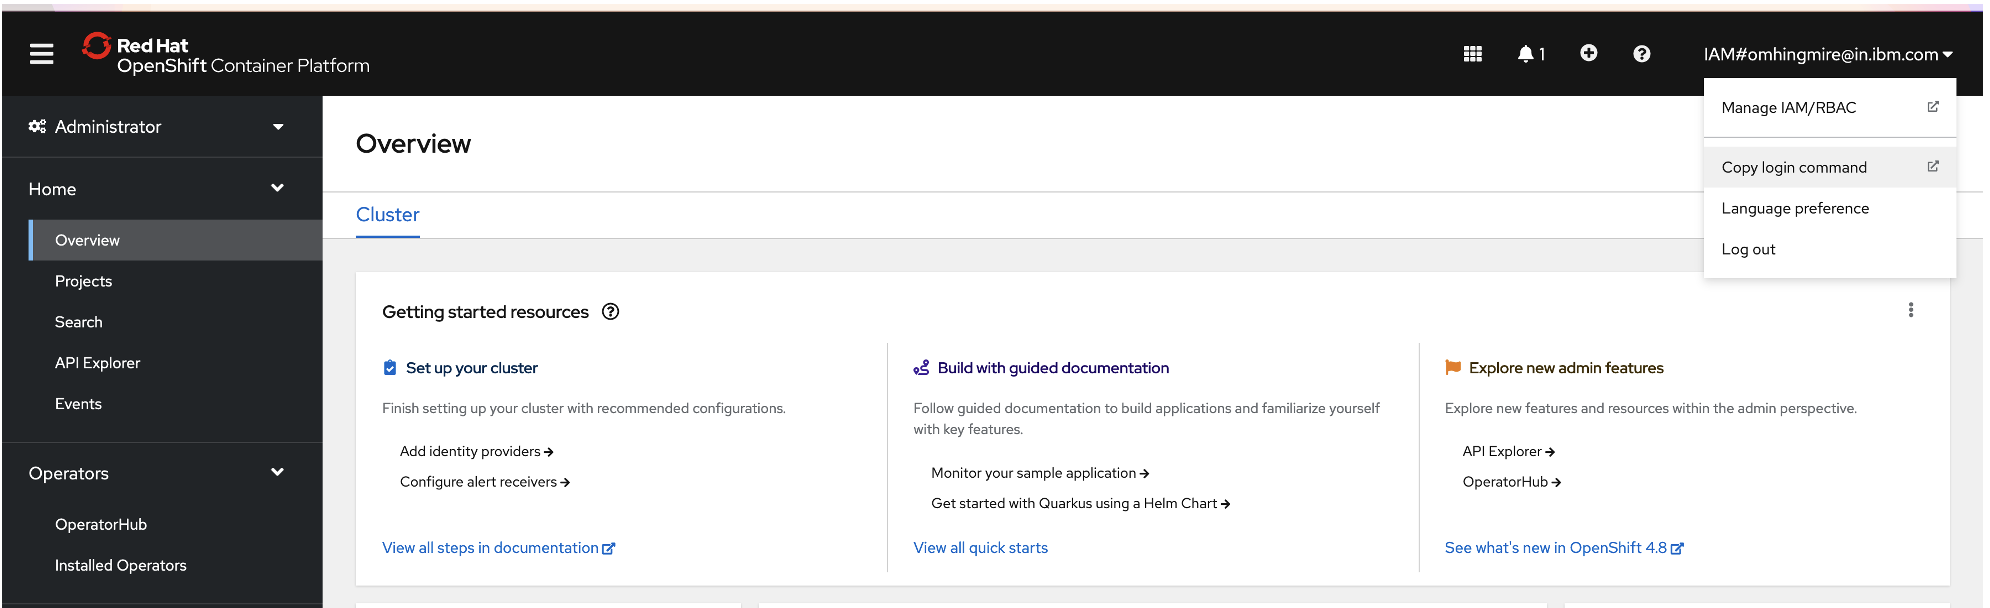
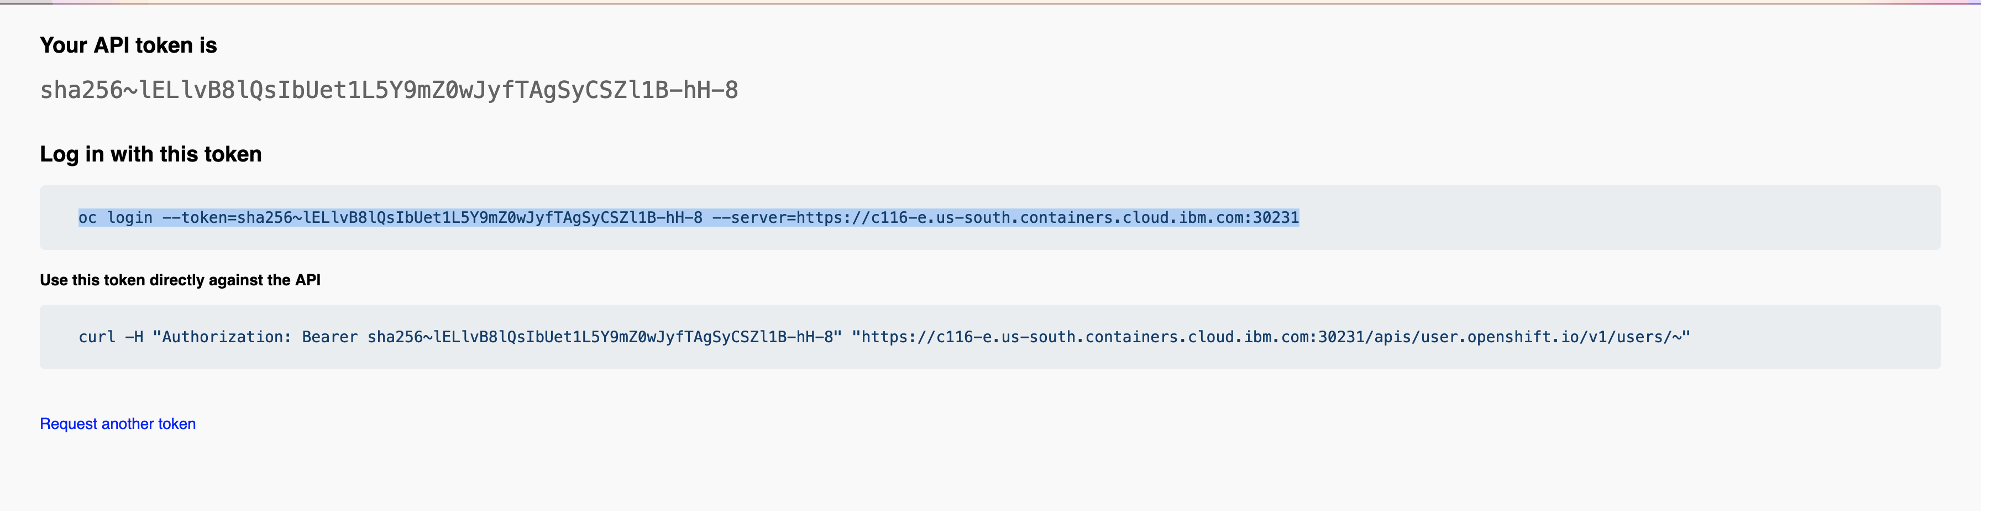 Note: To run the OpenShift cluster command locally, you must have the OpenShift cluster client installed on a local server.
- Create the catalog_source.yaml file as described in Red Hat Catalog Enablement for the IBM Operator Catalog.
- Run the
oc applycommand. Enable the catalog by applying the following YAML file to the OpenShift cluster:
apiVersion: operators.coreos.com/v1alpha1
kind: CatalogSource
metadata:
name: ibm-operator-catalog
namespace: openshift-marketplace
annotations:
olm.catalogImageTemplate: "icr.io/cpopen/ibm-operator-catalog:v{kube_major_version}.{kube_minor_version}"
spec:
displayName: IBM Operator Catalog
publisher: IBM
sourceType: grpc
image: icr.io/cpopen/ibm-operator-catalog:latest
updateStrategy:
    registryPoll:
    interval: 45m
Create the
catalog_source.yamlfile and run theoc applycommand.oc apply -f catalog_source.yaml -n openshift-marketplaceWhen you successfully create the file, you will see a message similar to the following:
   $ oc get CatalogSources ibm-operator-catalog -n openshift-marketplace
   NAME                   DISPLAY                TYPE   PUBLISHER   AGE
   ibm-operator-catalog   IBM Operator Catalog   grpc   IBM         28s
Step 5. Obtain a production entitlement key for IBM Storage Fusion production images
Go to your My IBM Entitlement keys page to get your keys for your IBM Storage Fusion images. (Note: You will need to log in with your IBM ID. If you do not have an entitlement key, follow the instructions in Obtaining a production entitlement key.)
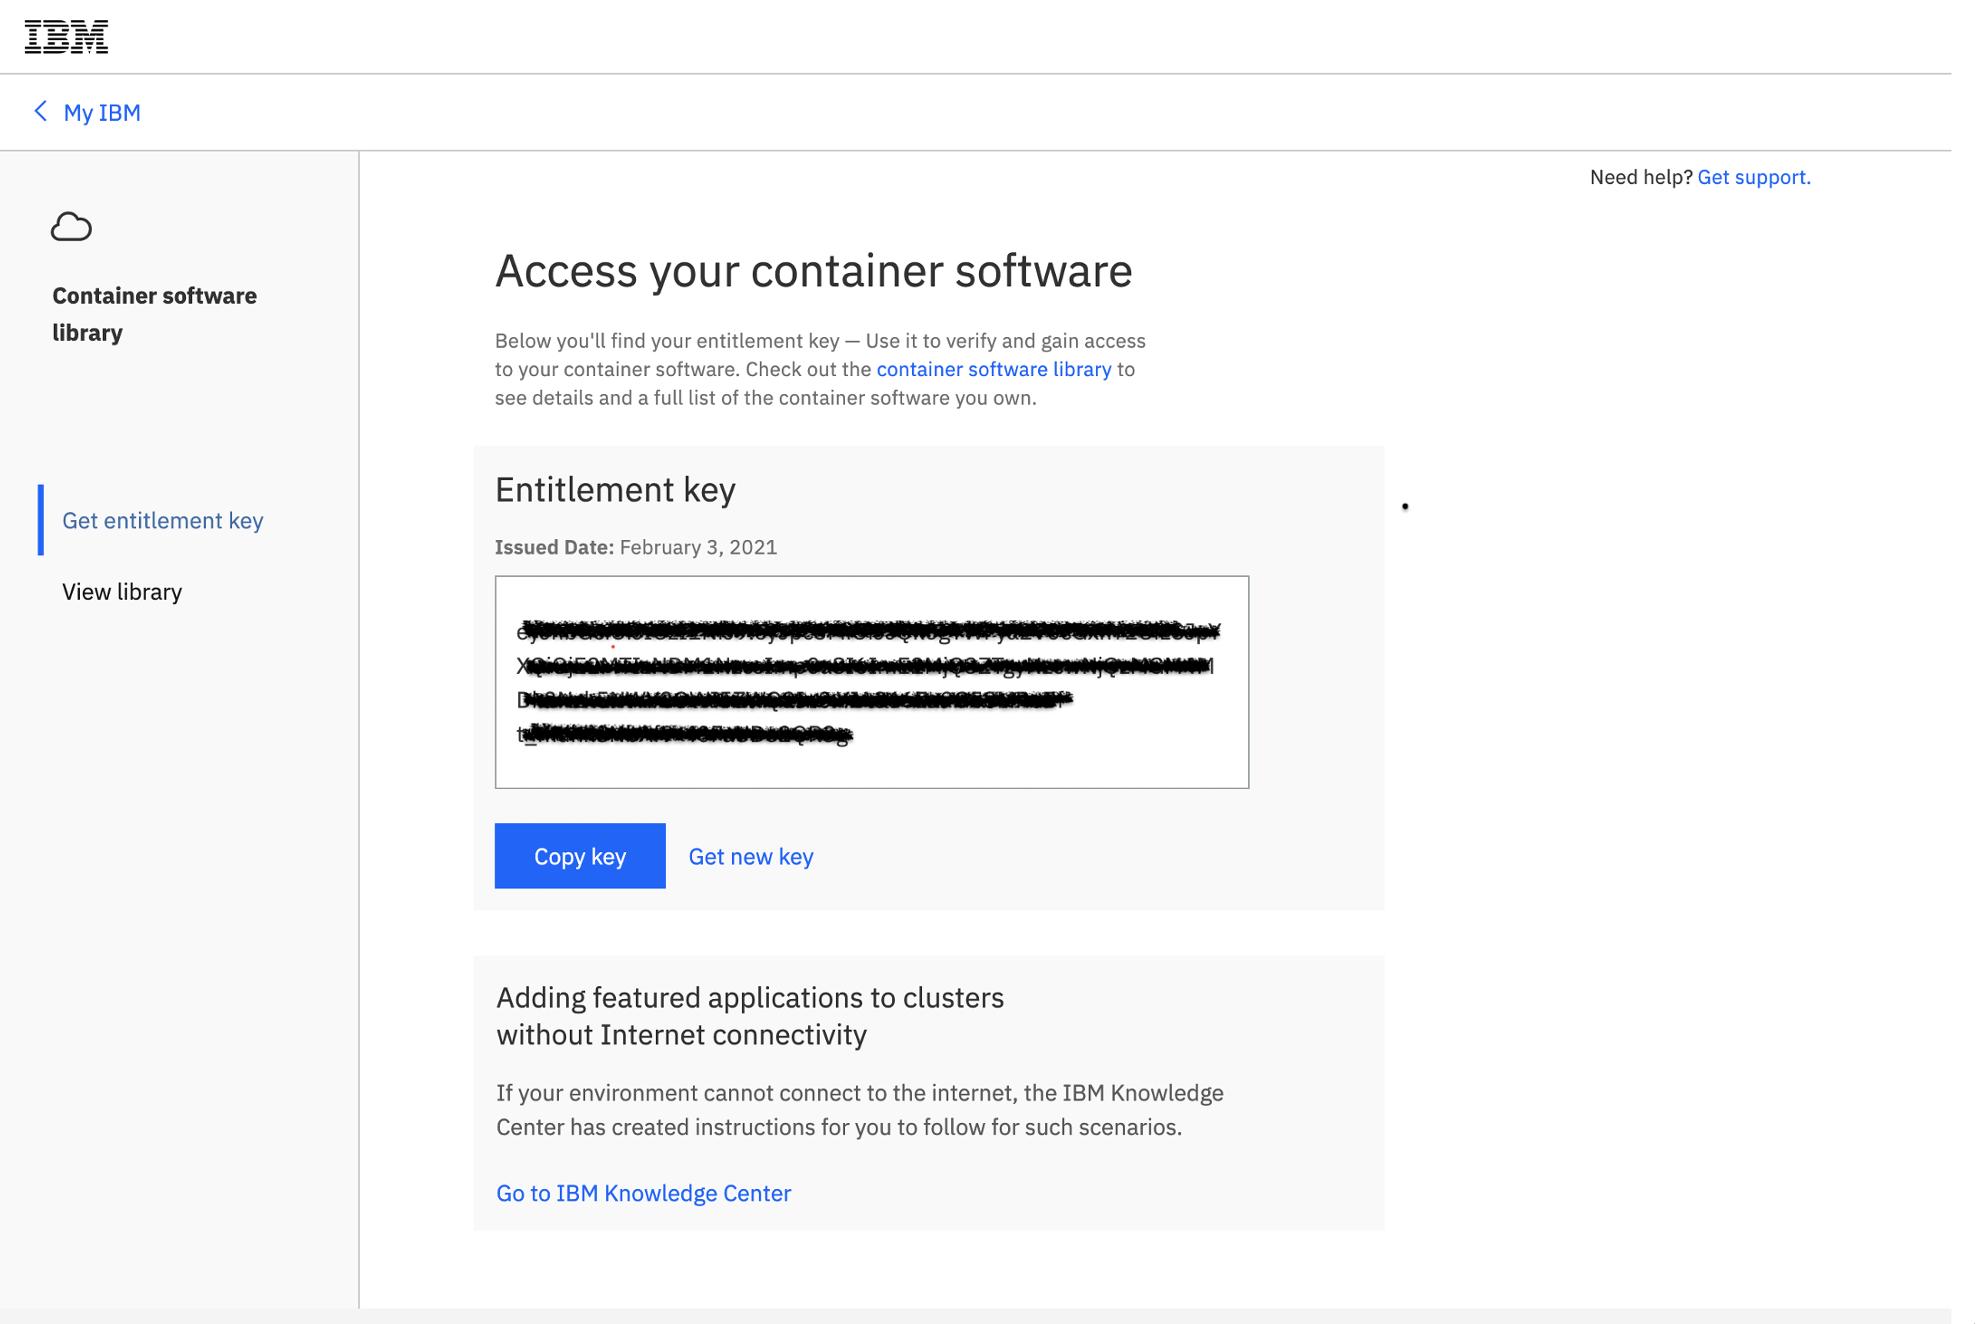
Copy the key and save it to a place where you can retrieve it later. The OCP pull secret will be updated with this key, along with username
cp. The pull secret will be used by the IBM Storage Fusion operator to retrieve relevant images from the CloudPak registrycp.icr.io.
Step 6. Update the OCP global pull-secret with the production entitlement key
- Run the following commands from the server where you are remotely connected to the OCP cluster. Note: You must have the jq library installed on the server.
// Return base64 format for the username/password (entitlement key):

echo -n "cp:REPLACE_WITH_GENERATED_ENTITLEMENT_KEY" | base64 -w0

// Create the auth.json file, which will contain the base64 encoded string of the entitlement key:

{
  "auth": "REPLACE_WITH_BASE64_ENCODED_ENTITLEMENT_KEY_FROM_PREVIOUS_COMMAND",
  "username":"cp",
  "password":"REPLACE_WITH_GENERATED_ENTITLEMENT_KEY"
}

// Create the temp_config.json file:

oc get secret/pull-secret -n openshift-config -ojson | \
jq -r '.data[".dockerconfigjson"]' | \
base64 -d - | \
jq '.[]."cp.icr.io" += input' - auth.json > temp_config.json

// Append and set the secret with new a new config file:

oc set data secret/pull-secret -n openshift-config --from-file=.dockerconfigjson=temp_config.json

// Verify the secret using oc get secret:

oc get secret/pull-secret -n openshift-config -ojson | \
jq -r '.data[".dockerconfigjson"]' | \
base64 -d -
Step 7. Resize the OCP node
You have updated the pull secret on the OCP cluster with new entitlement keys. However, those changes are not automatically reflected on all nodes. To apply those changes to all nodes, you must resize the worker pool.
- In the IBM Cloud console, go to the OpenShift clusters page and click your cluster to open the details page.
In the left menu, click Worker pools. Click the overflow menu (that is, the icon with three vertical dots) and select Resize. The Resize worker pool window opens.

Increase the worker pool size by 1 and wait to ensure that all the nodes are in a ready state.
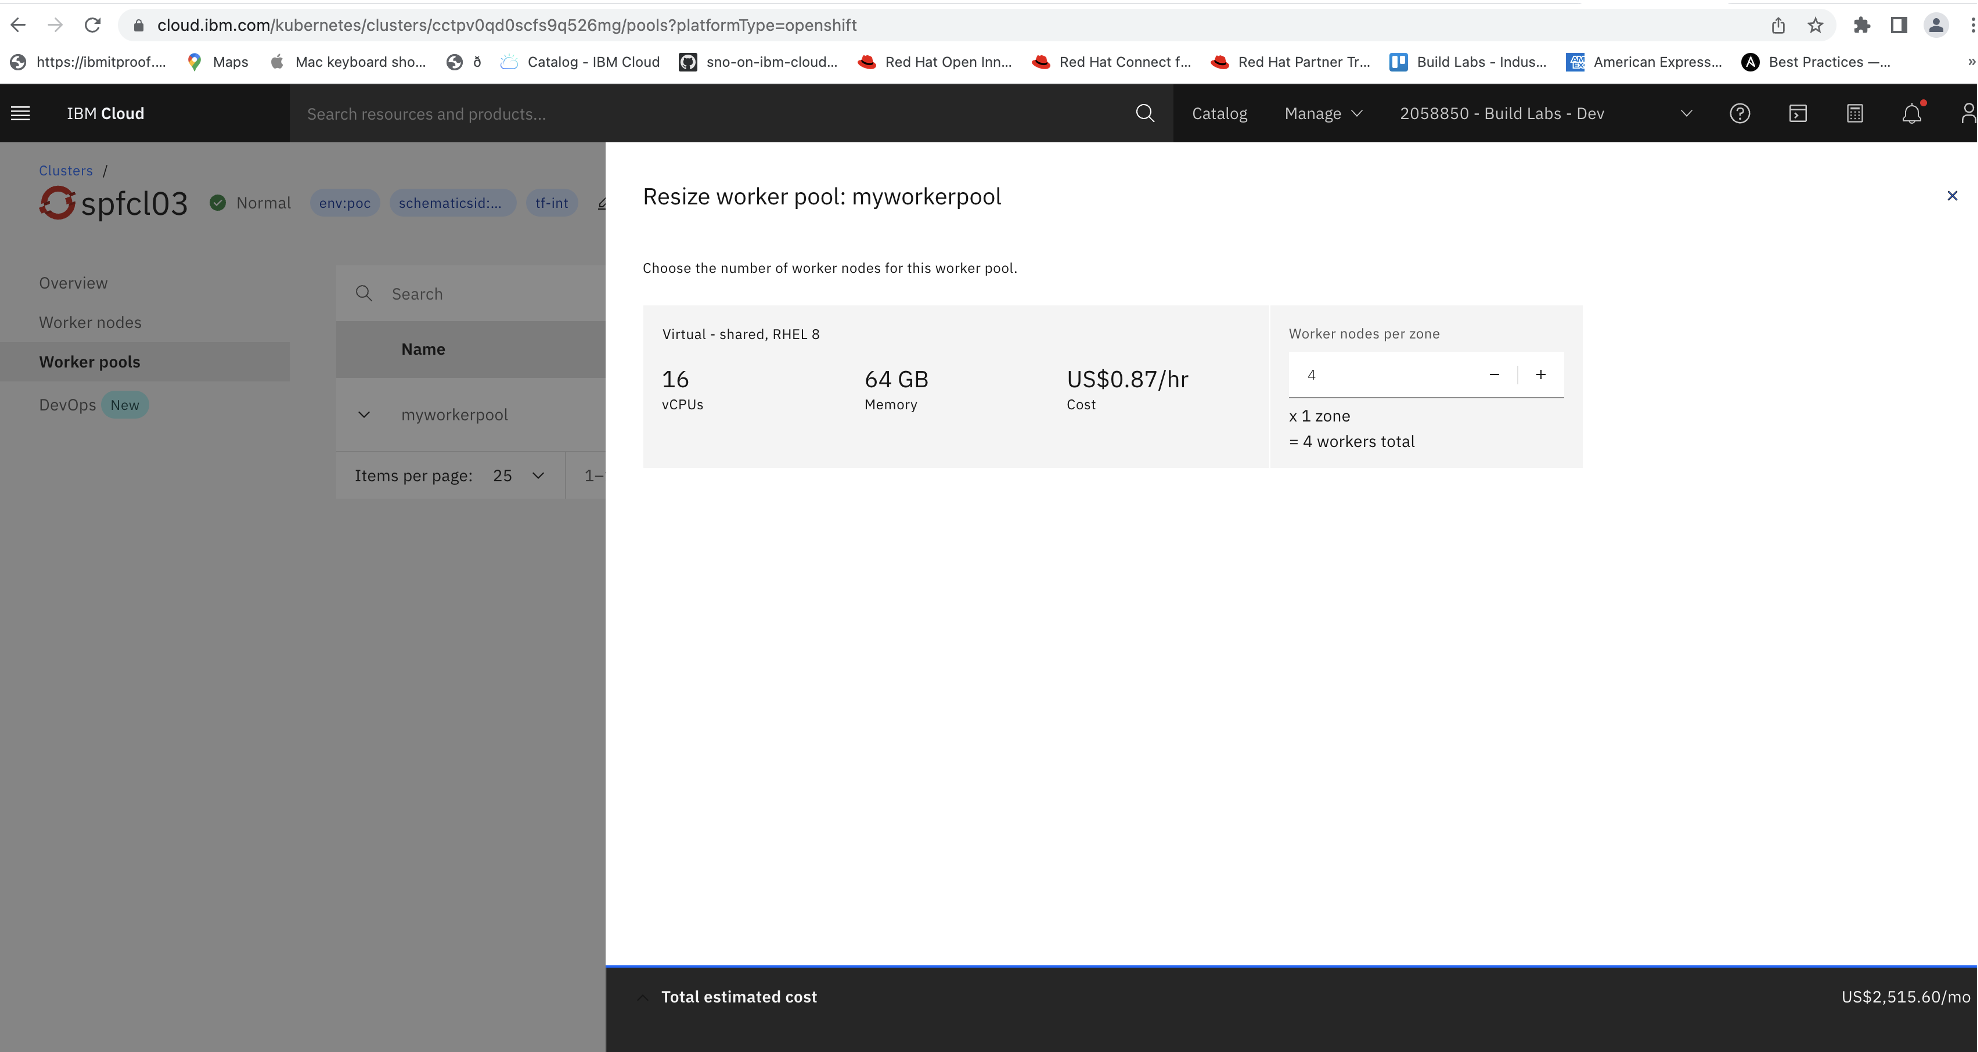


Repeat the process, this time decreasing the worker pool size by 1. Ensure that all the nodes are in the ready state.

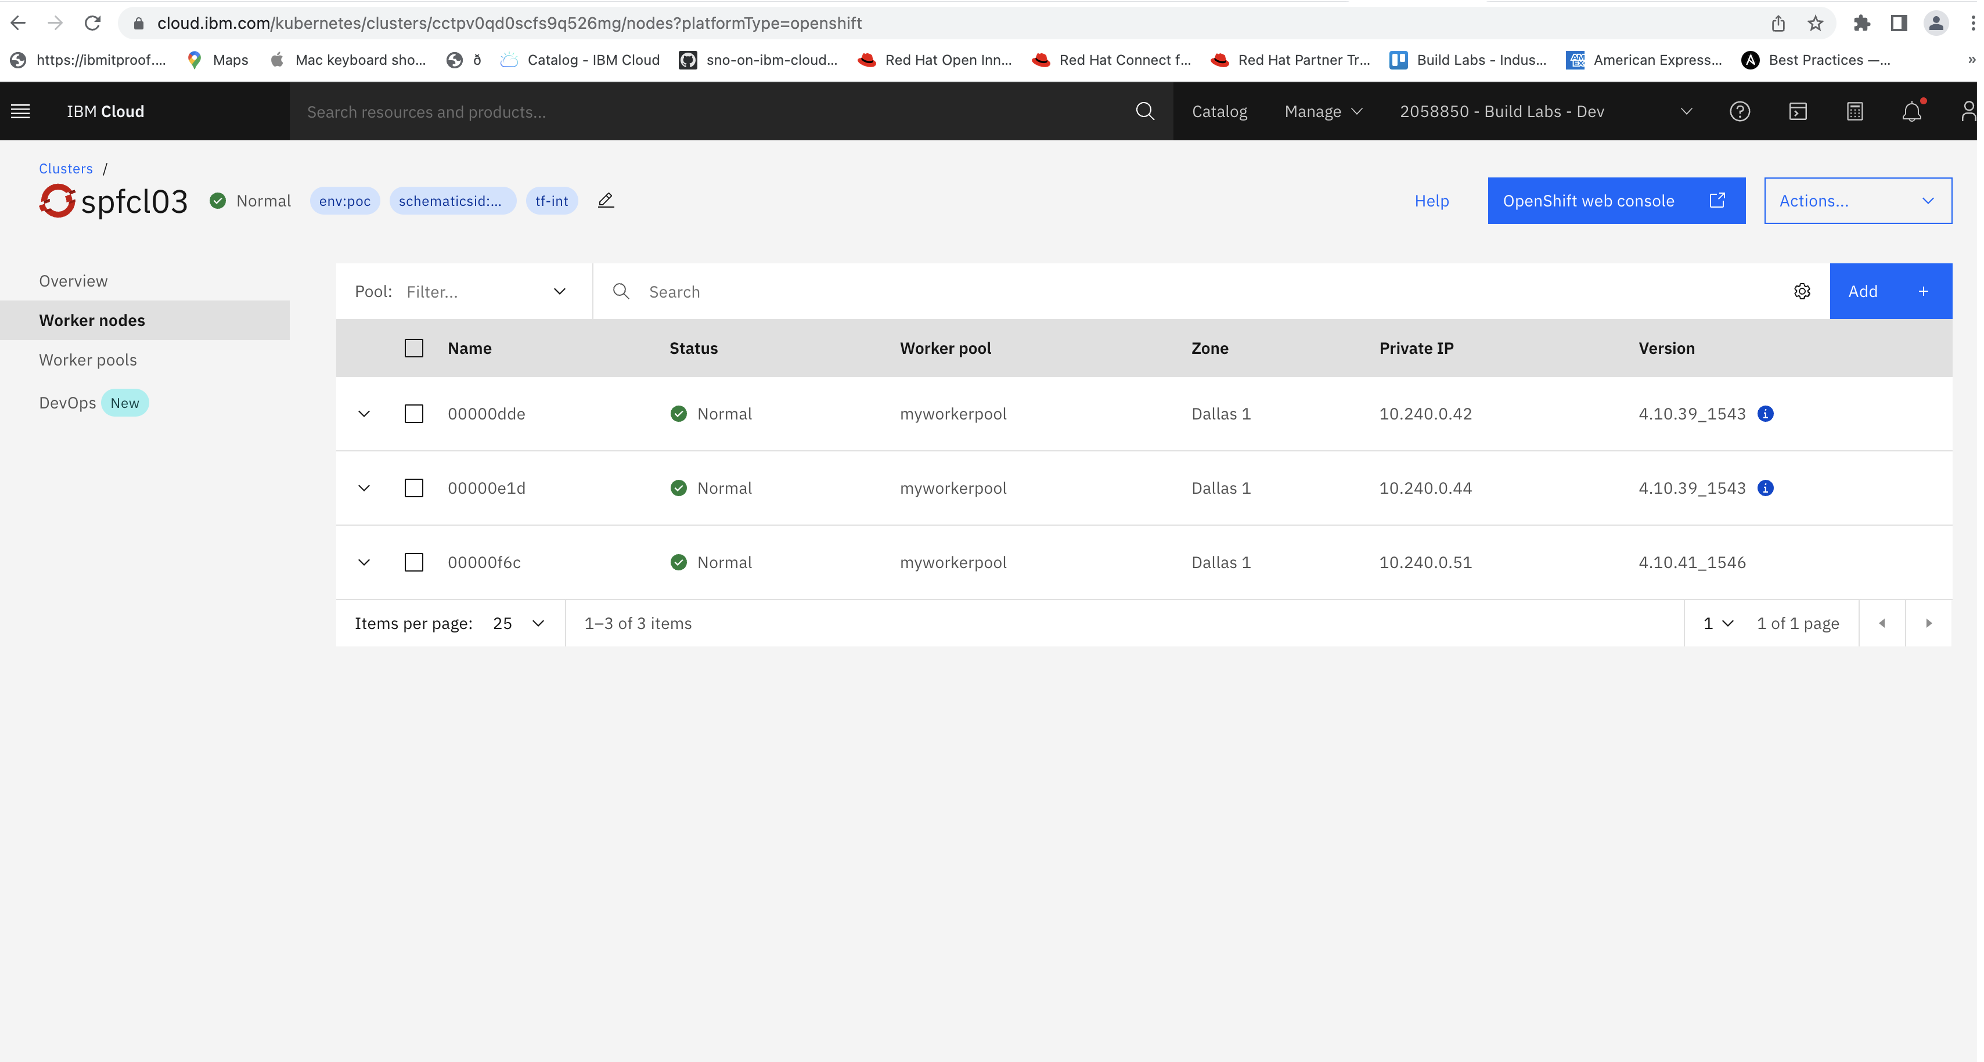
Repeat step 3 (increase the storage pool size by 1) and step 4 (decrease the storage pool by 1) from the IBM Cloud console until all previously provisioned nodes are replaced by new ones.
- Verify that the pull secret has been updated on all nodes by running the following command:
Note: Steps 5 and 6 are required because IBM Cloud on OpenShift requires resizing and reloading of nodes.$ for node in `oc get no |awk -F " " '/Ready/ {print $1}'`; do oc debug node/$node -- chroot /host cat /var/lib/kubelet/config.json;done
Step 8. Install the IBM Storage Fusion 2.3.0 Operator from OperatorHub
- On the OpenShift Container Platform page, in the left menu, click Operators > OperatorHub.
- Click All items and search for IBM Storage Fusion.
Click on the IBM Operator catalog tile for IBM Storage Fusion and in the pop-up window, click Install


- In the left menu, click Installed Operators. In the list of operators, confirm that the IBM Storage Fusion Operator has been installed successfully.

- In the left menu, click Workloads > Pods. Confirm that all pods are running.

Step 9. Create a StorageFusion custom resource
Create an instance of the StorageFusion custom resource (CR):
- Click Installed Operators and then click the IBM Storage Fusion operator.
- Create an instance of the operator by clicking Create Storage Fusion and enter following details:
- Name: Enter a name for the StorageFusion CR; for example,
storagefusion. - Labels: Optionally, add labels for the CR.
- License: Accept the license.
- Data protection: Click to enable Data Protection.
- Storage Class: Some default storage classes are included with OCP on IBM Cloud; select the ocs-storagecluster-ceph-rbd storage class.
- Name: Enter a name for the StorageFusion CR; for example,
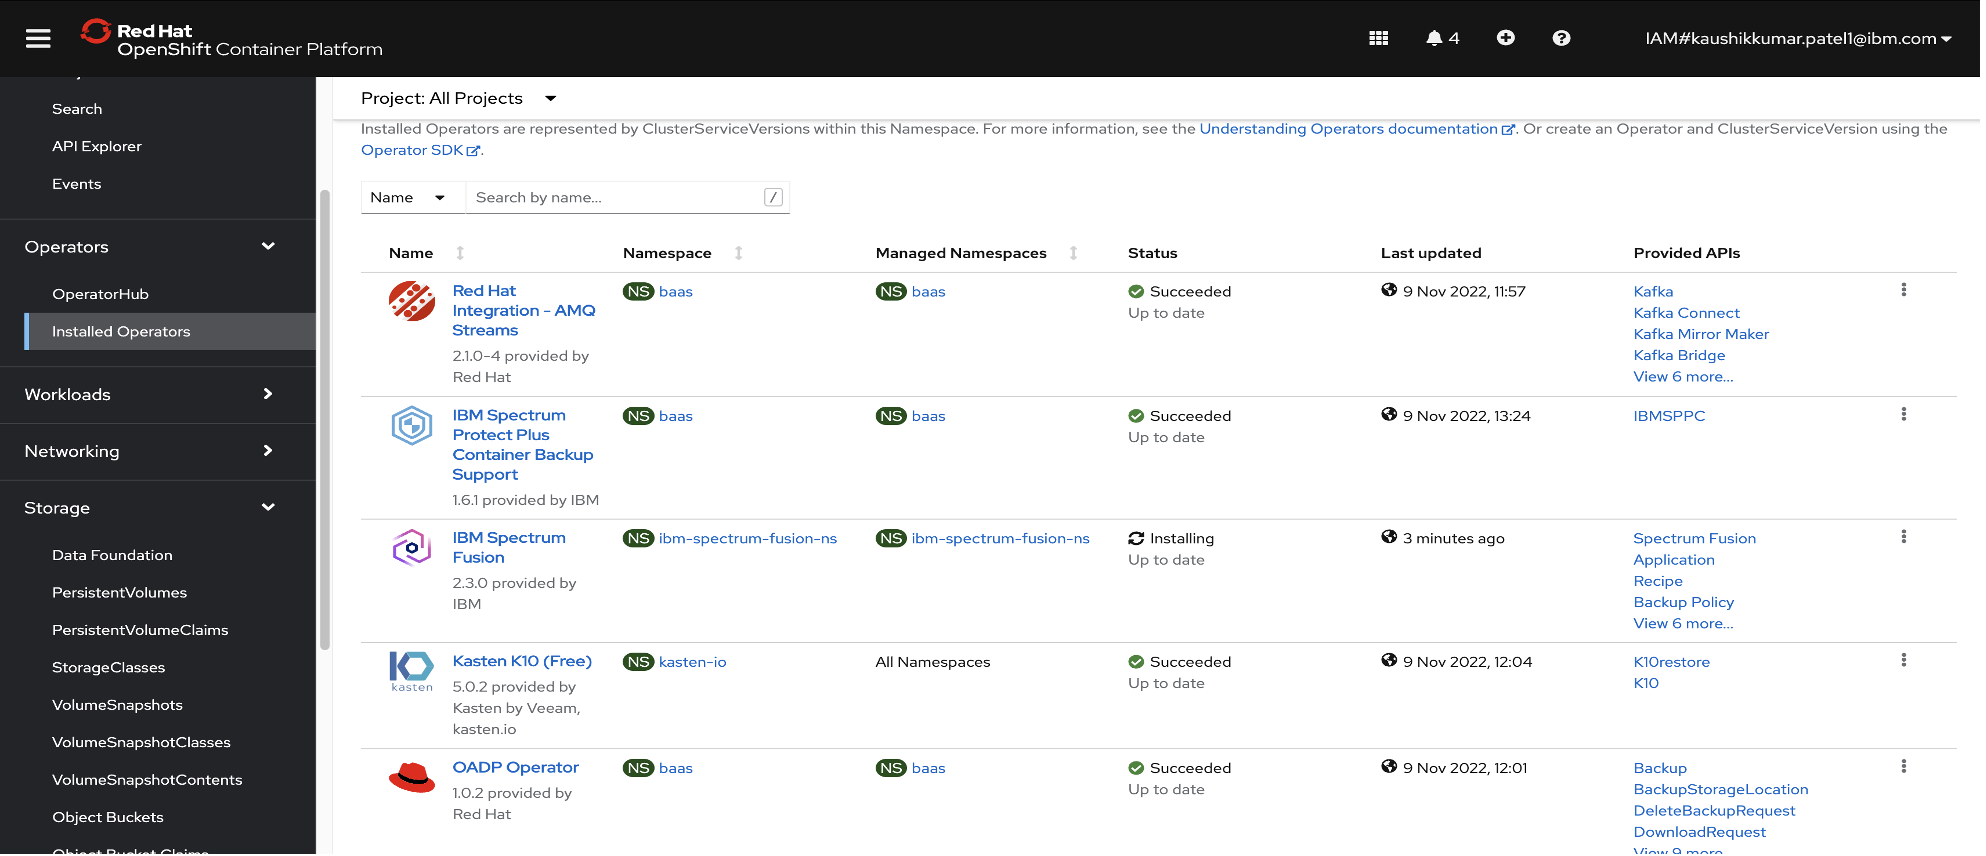
- Confirm that the following four operators have been installed:
- IBM Storage Protect Plus Operator
- IBM Storage Protect Plus Container Backup Support
- OADP Operator
- Red Hat Integration – AMQ Streams
Step 10. Update the IBM Storage Fusion UI console configuration
Note: IBM Storage Fusion 2.3 currently has a bug pertaining to Red Hat OpenShift Kubernetes Service. After you install, the OAuthClient isf-oauth does not get created with redirectURIs. This bug is planned to be corrected in version 2.4.


As a workaround in version 2.3, complete the following steps:
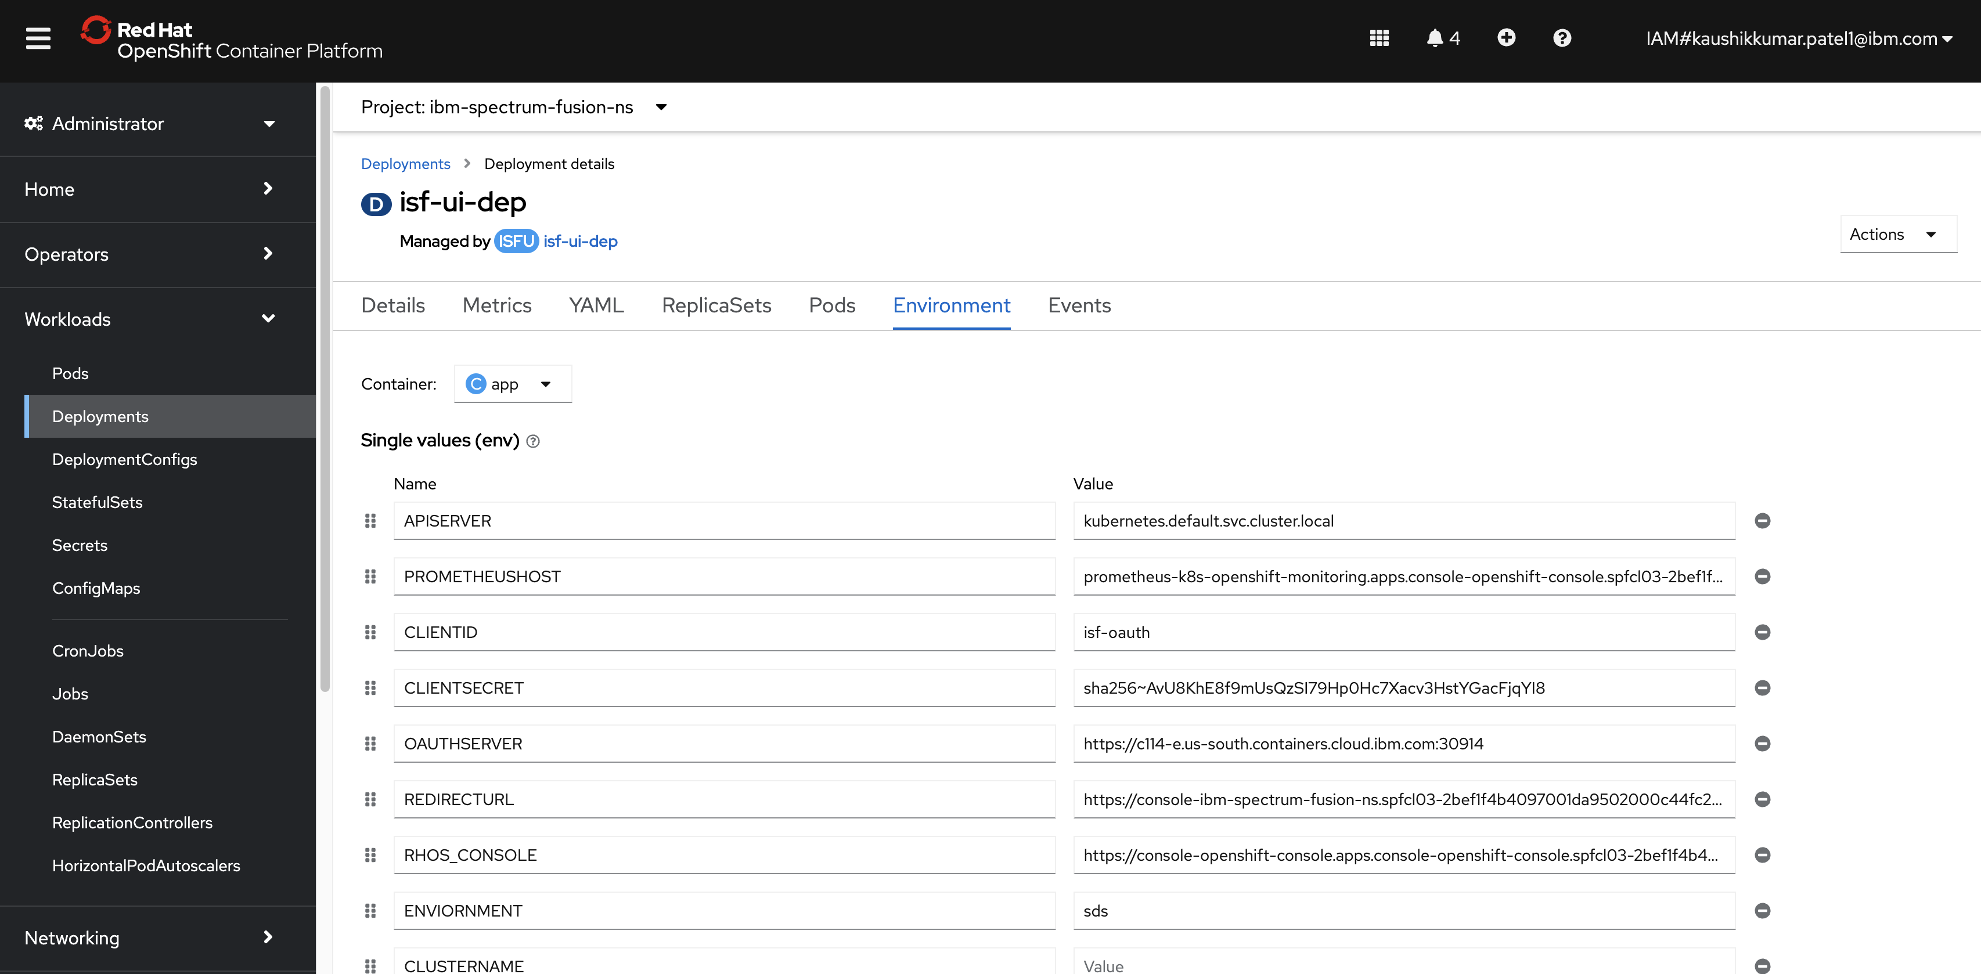
- In the left menu, click Deployments. Switch to the ibm-Storage-fusion-ns project and search for ibm-ui-dep.
- Click ibm-ui-dep and then click the Environment tab.
- Copy the value from REDIRECTURL.
- Go to Home > API Explorer and search for OauthClient.

- Click OAuthClient and then click the Instances tab.
- Click isf-oauth, click the YAML tab and update redirectURIs with the value that you copied in step 3. Click Save.

Click the Application icon in the console title bar and then click IBM Storage Fusion.

Note: When IBM Storage Fusion launches, an
Application is not availableerror message displays if you are using version 2.3. This is a bug that is planned for correction in version 2.4.
To avoid the error, in the browser URL, remove
.appsand press Enter. For example:- Broken URL:
https://console-ibm-Storage-fusion-ns.apps.spfcl03-2bef1f4b4097001da9502000c44fc2b2-0000.us-south.containers.appdomain.cloud Correct URL:
https://console-ibm-Storage-fusion-ns.spfcl03-2bef1f4b4097001da9502000c44fc2b2-0000.us-south.containers.appdomain.cloud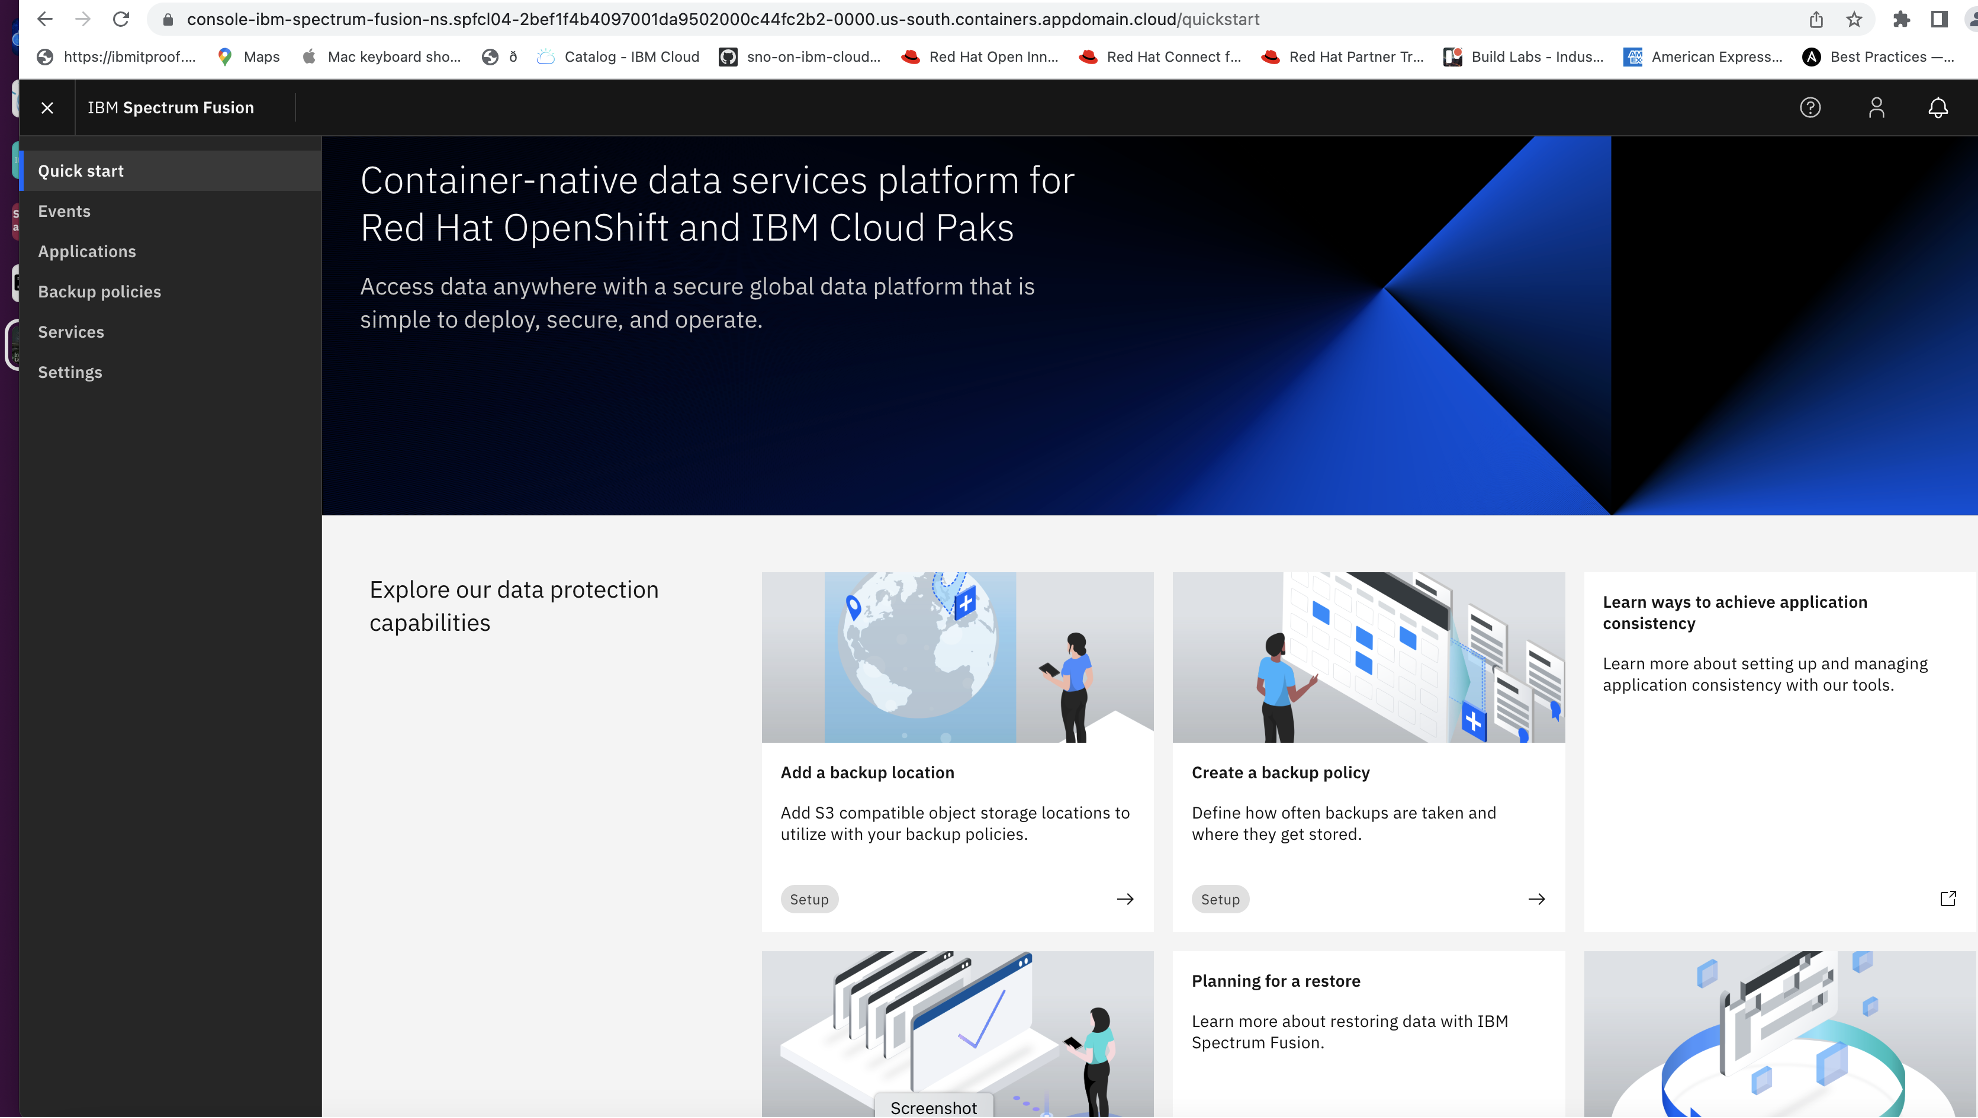

- Broken URL:
Backing up your container application
To back up your container application, you will first deploy a sample application and then add a storage location, create a backup policy, assign the policy, and then run the backup.
Step 1. Deploy a sample application on OpenShift and verifying a persistent volume in OpenShift Data Foundation storage
- Go to the OpenShift console. In the left menu, click Administrator > Projects. At the upper right of the page, click Create Project.
- In the Create Project pop-up window's Name field, type
demoappsand click Create.
- In the left menu, click the role drop-down menu and select Developer.
- Change the project to demoapps. In the left menu, click +Add. The developer catalog opens.

- Search for the catalog for the Node.js + PostgreSQL templates. Click the tile and then click Instantiate Template.

- Verify that the namespace value is demoapps and then click Create.

- Ensure that all application pods are in Running state.

- In the OpenShift console, in the left menu, switch back to the Administrator view and ensure that the status for
nodejs-postgresql-persistent-[xxxx]andpostgesql-[xxxx]is Running. If the pods are running, it means PerstistentVolume storage has been successfully created using the ODF StorageClass default.
- To verify that the persistent volume has been created, in the left menu, click Storage > PersistentVolumeClaims. Ensure that postgresql has a status of Bound and its StorgeClass is “ocs-storagecluster-ceph-retain-rbd, which is the default StorageClass that you set up in a previous step.
Step 2. Add a backup storage location
To save a backup copy to IBM Cloud Object Storage, you must add IBM Cloud Object Storage as a backup location in IBM Storage Fusion.
- To create a bucket in IBM Cloud Object Storage, ensure you are logged in to to IBM Cloud and then search for Cloud Object Storage.
- In the left menu, click Instances and click the instance that you created previously. The instance window opens.
- Click the Buckets tab and then click Create bucket +.

- Click Customize your bucket. Enter a unique bucket name, your preferred resiliency type, location, and storage class. When you have completed your selections, click Create bucket.

Set permissions on a bucket
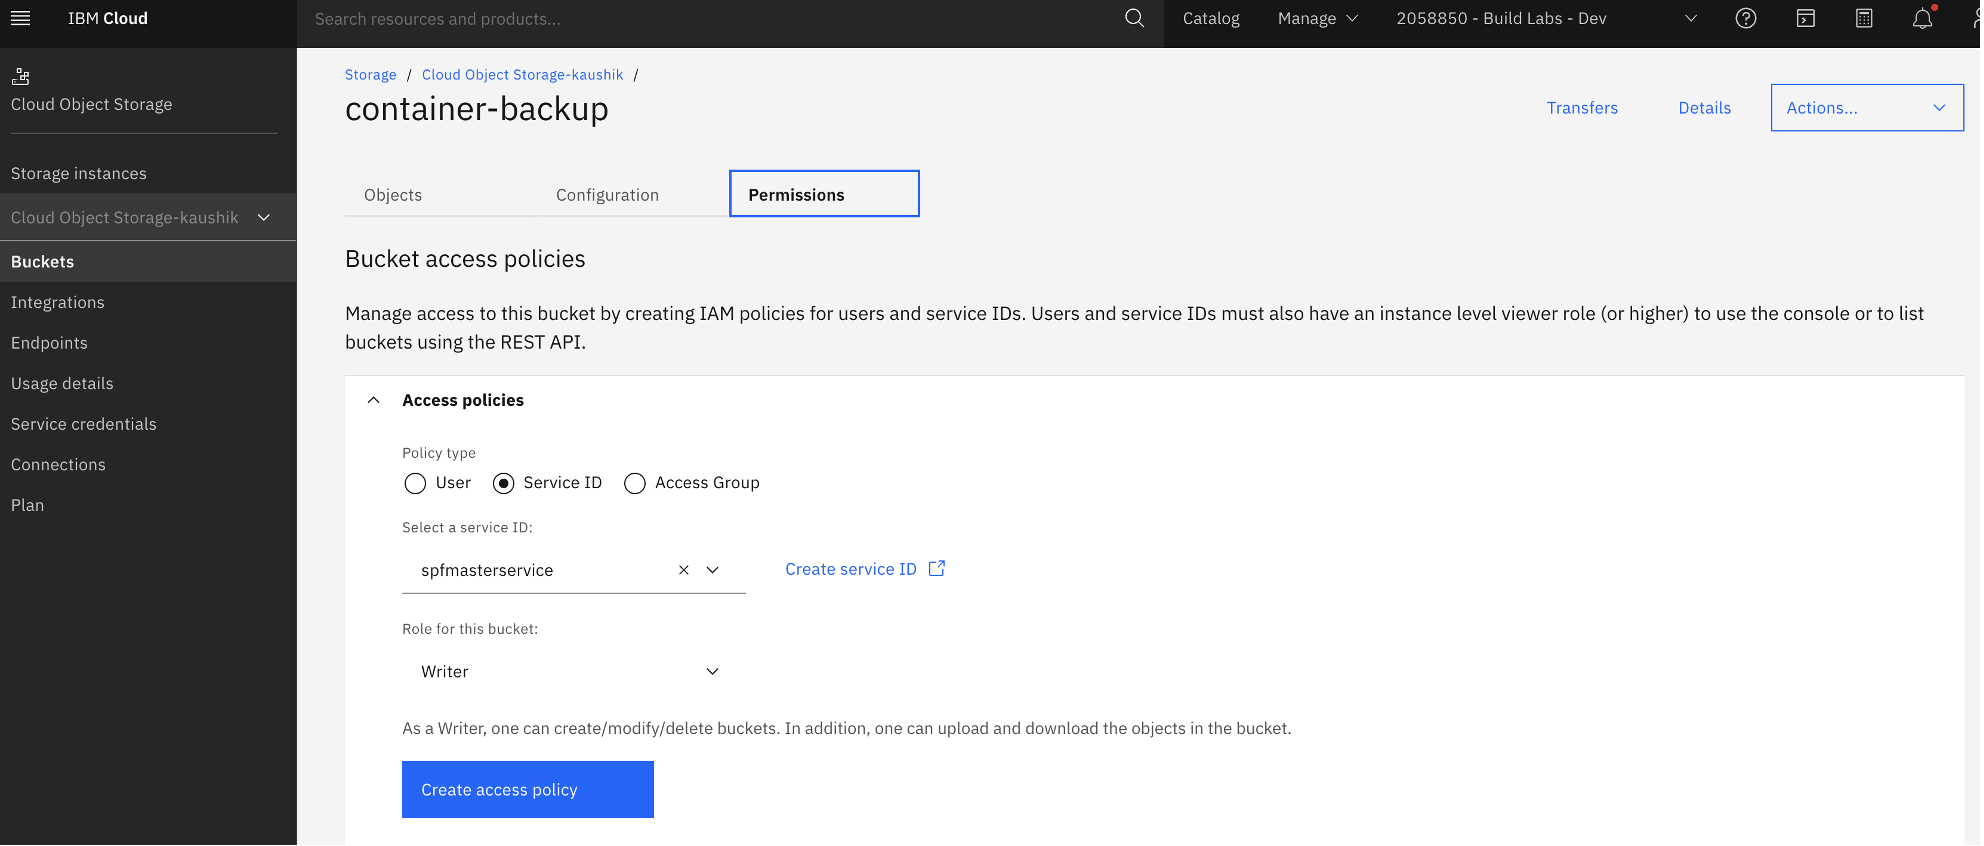
- In the left menu, click Buckets. In the Buckets window, click the Permissions tab.
- In the "Access policies" panel, select Service ID and for the role, select Writer. Click Create access policy.
Get the Cloud Object Storage bucket endpoint name
To store the application backup, we'll use a cloud object bucket. The fully qualified bucket name is the endpoint we need to register in IBM Storage Fusion as the backup location. Complete the following steps to copy the object storage endpoint:
- In the Buckets window, click the Configuration tab and then click Endpoints.

- Scroll to the Direct endpoint and click the copy icon.

- Paste and save the endpoint name to a text file so you can easily retrieve it.
Copy the service credentials access key and secret key
To authenticate with IBM Cloud Object Storage, you need your Service Credentials' access key and secrets key.
- In the IBM Cloud console, go to IBM Cloud Object Storage.
- Click Service Credentials > Expand Service Credential.
- Copy the access key from access_key_id field and the secret key from secret_access_key field.
- Paste the keys to a location where you can retrieve them easily later.
Add a backup location
- In the IBM Storage Fusion console, in the left menu, click Backup Policies.
- Click the Locations tab and then click Add Location +.

- Enter a name for the location; for example,
ibmcos. For type of storage backup location, select IBM Cloud (IBM Object Storage). - In the Endpoint field, enter the name of the endpoint that you copied earlier. Enter the bucket name and then paste the access key and secret key that you copied earlier.
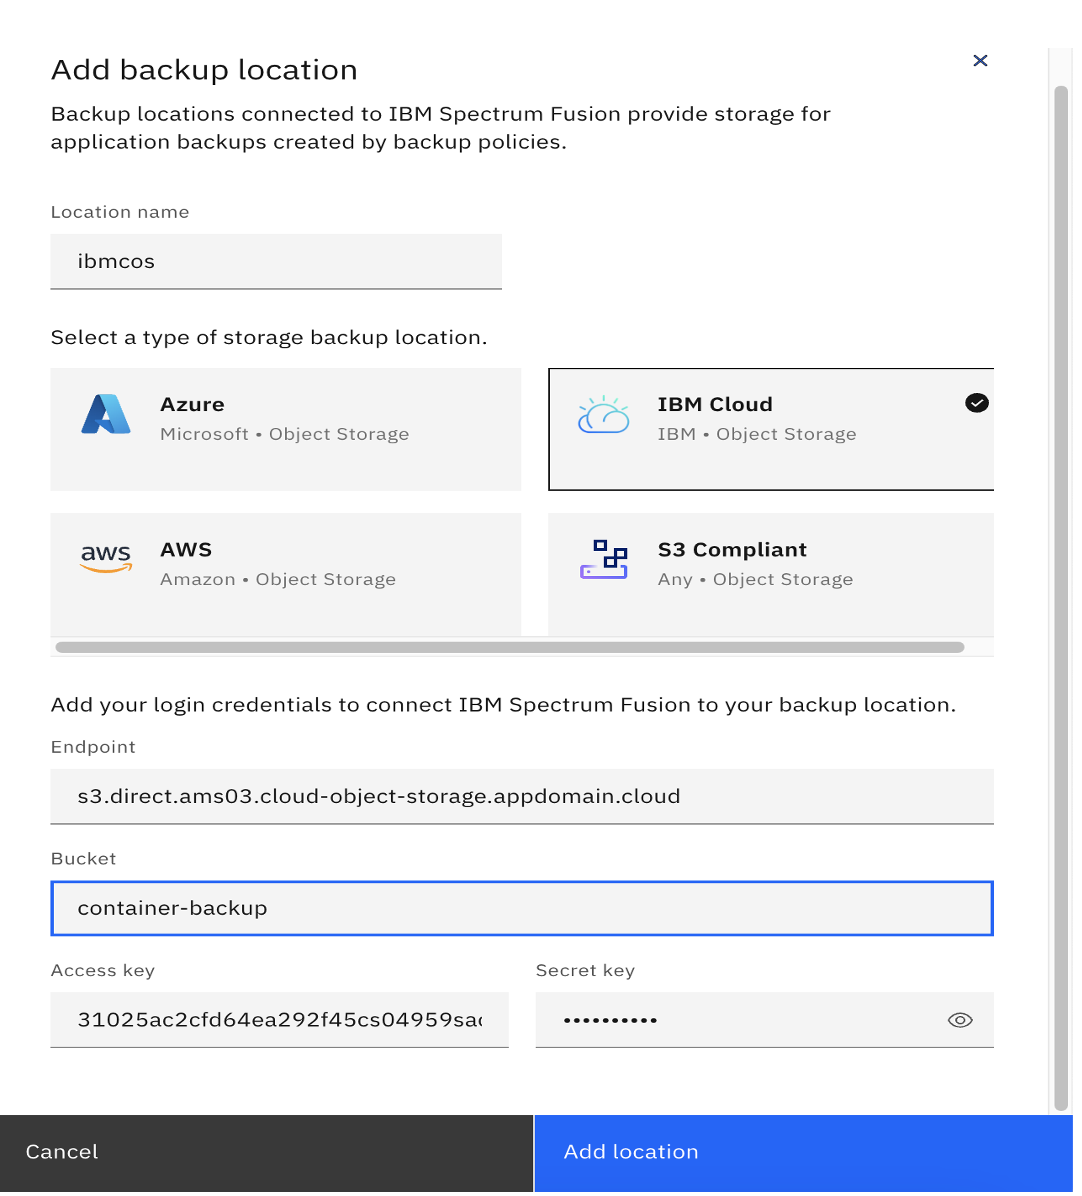
- Verify the storage location has been added and and the status is Connected.

Step 3. Create a backup policy
Backup policies define parameters that are applied to backup jobs. These parameters specify the storage location, frequency of backup jobs, the retention period for backed-up data, and other directives for backup operations.
- In the IBM Storage Fusion console left menu, click Backup Policies. The "Backup policies" window opens.
- Click the Policies tab and then click Add policy.

- Enter a name for your backup policy and set the frequency for your backup jobs. In the Backup Locations panel, click the Object storage tile.
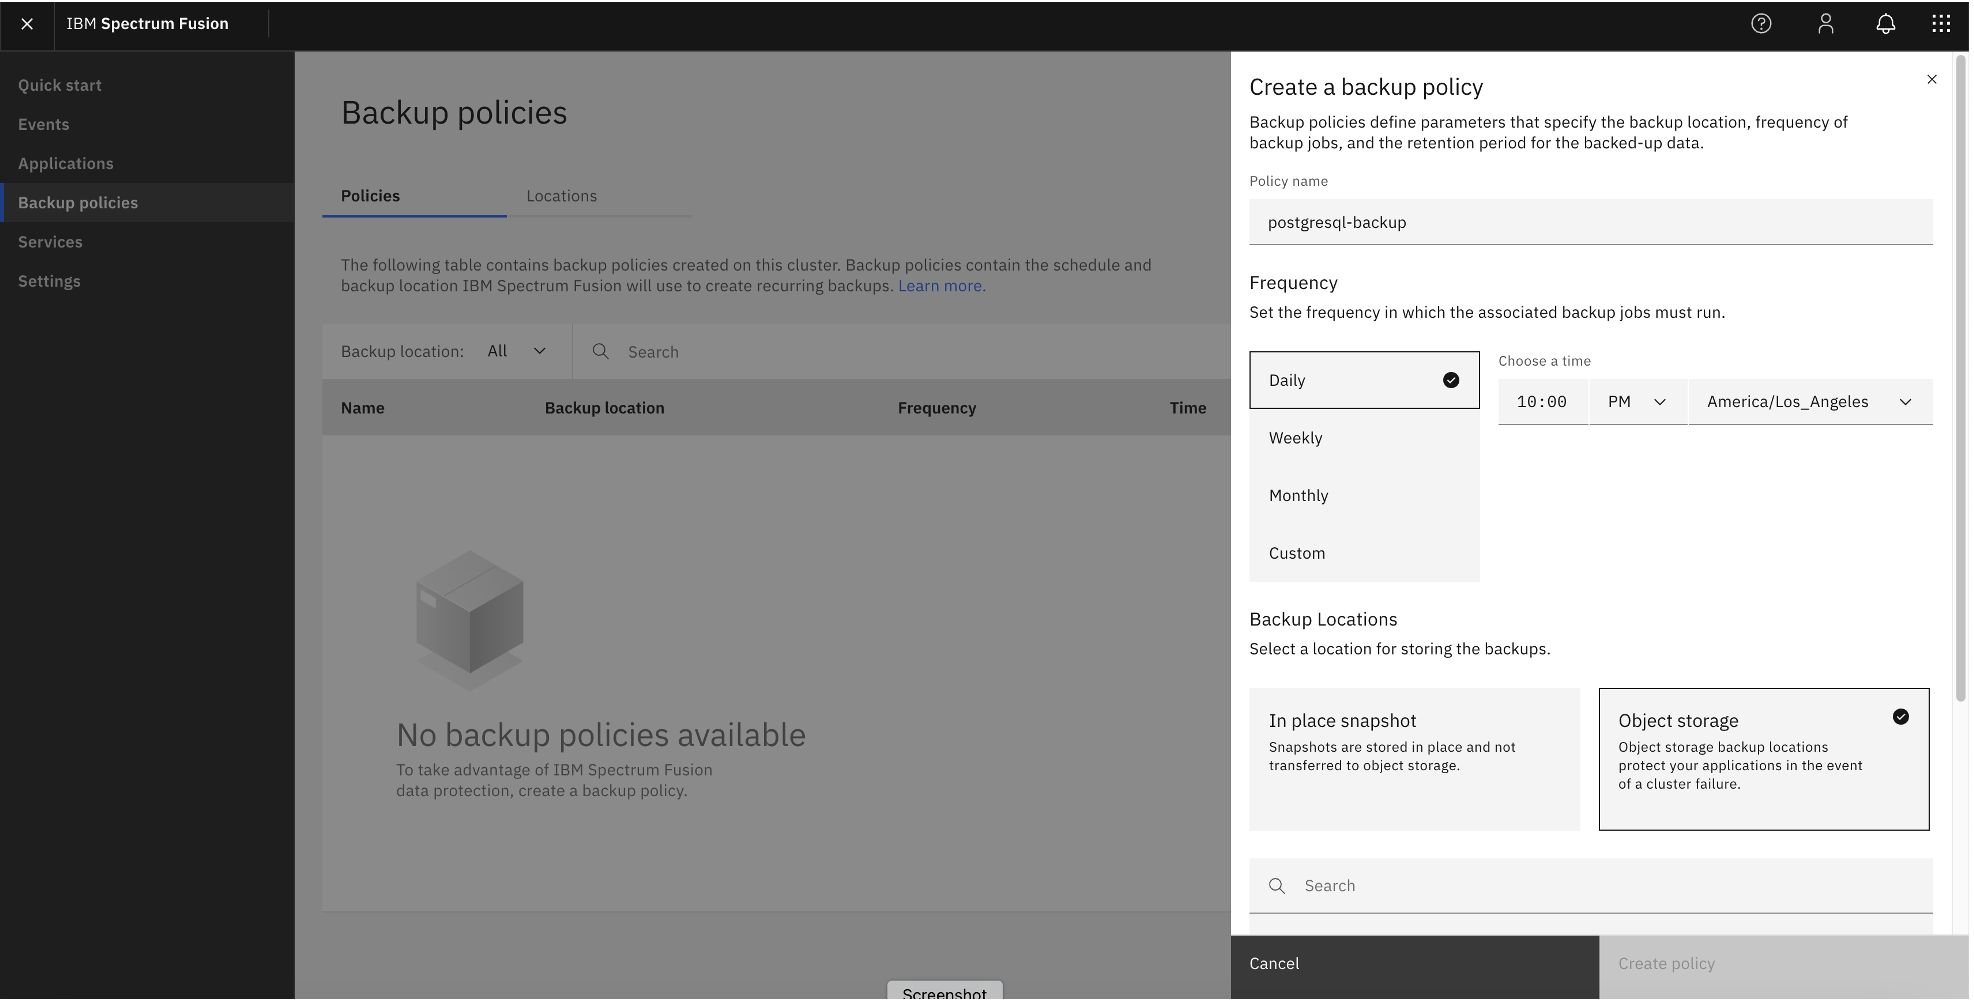
- Use the search field to find your backup location and then enter the retention period that will determine how long the backup copies will exist.
- When you have completed all the fields, click Create policy.

- Confirm that the backup policy has been created.

Step 4. Assign the backup policy to container applications
Your container applications run under the namespace (or project) in OpenShift. You can’t assign the backup policy to individual resources within the namespace, so you must assign the backup policy to the namespace (or project) instead.
To assign a backup policy to a namespace, complete the following steps:
In the left menu, click Applications. In the Applications page's Backup policy column, click Assign policy for the namespace where the application is running.

Note: By clicking Assign policy, you trigger the one-time backup of the container application. Subsequent backups will occur based on the schedule defined in the backup policy.
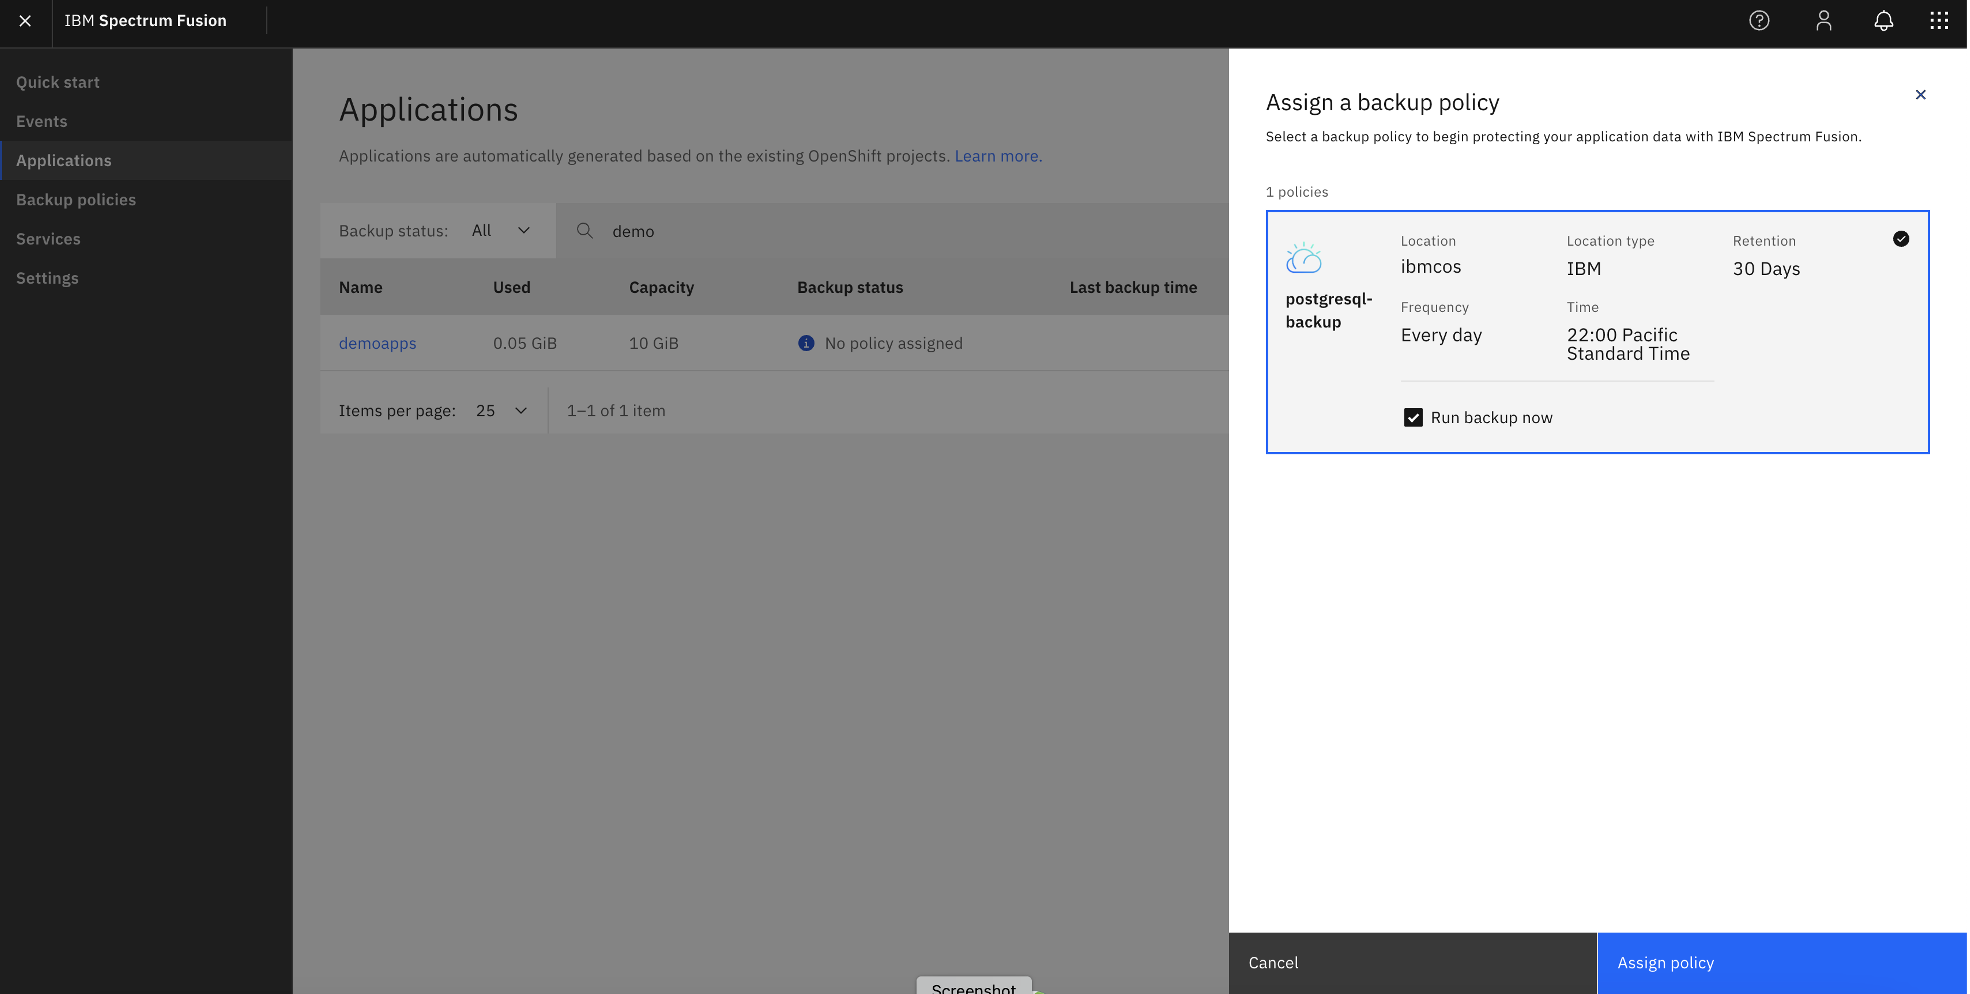
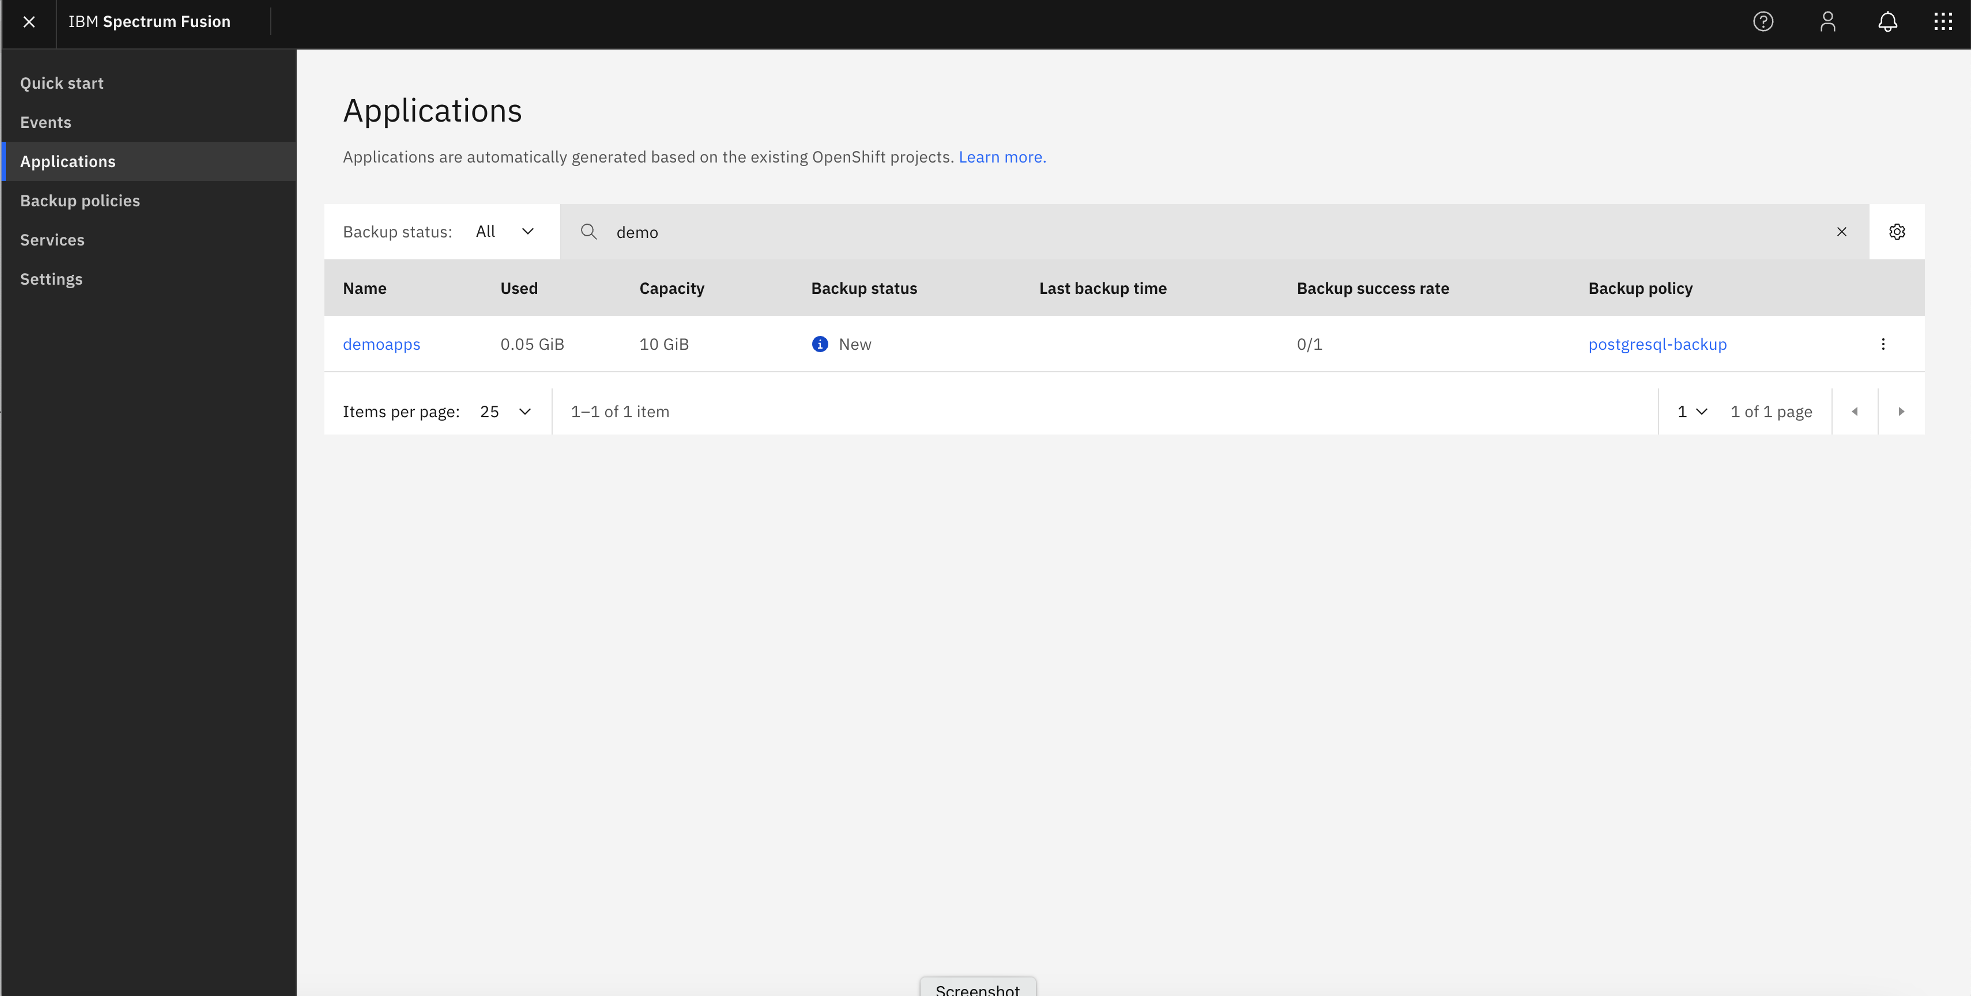
Click the application namespace and then click the Backups tab. Monitor the backup job until it completes.

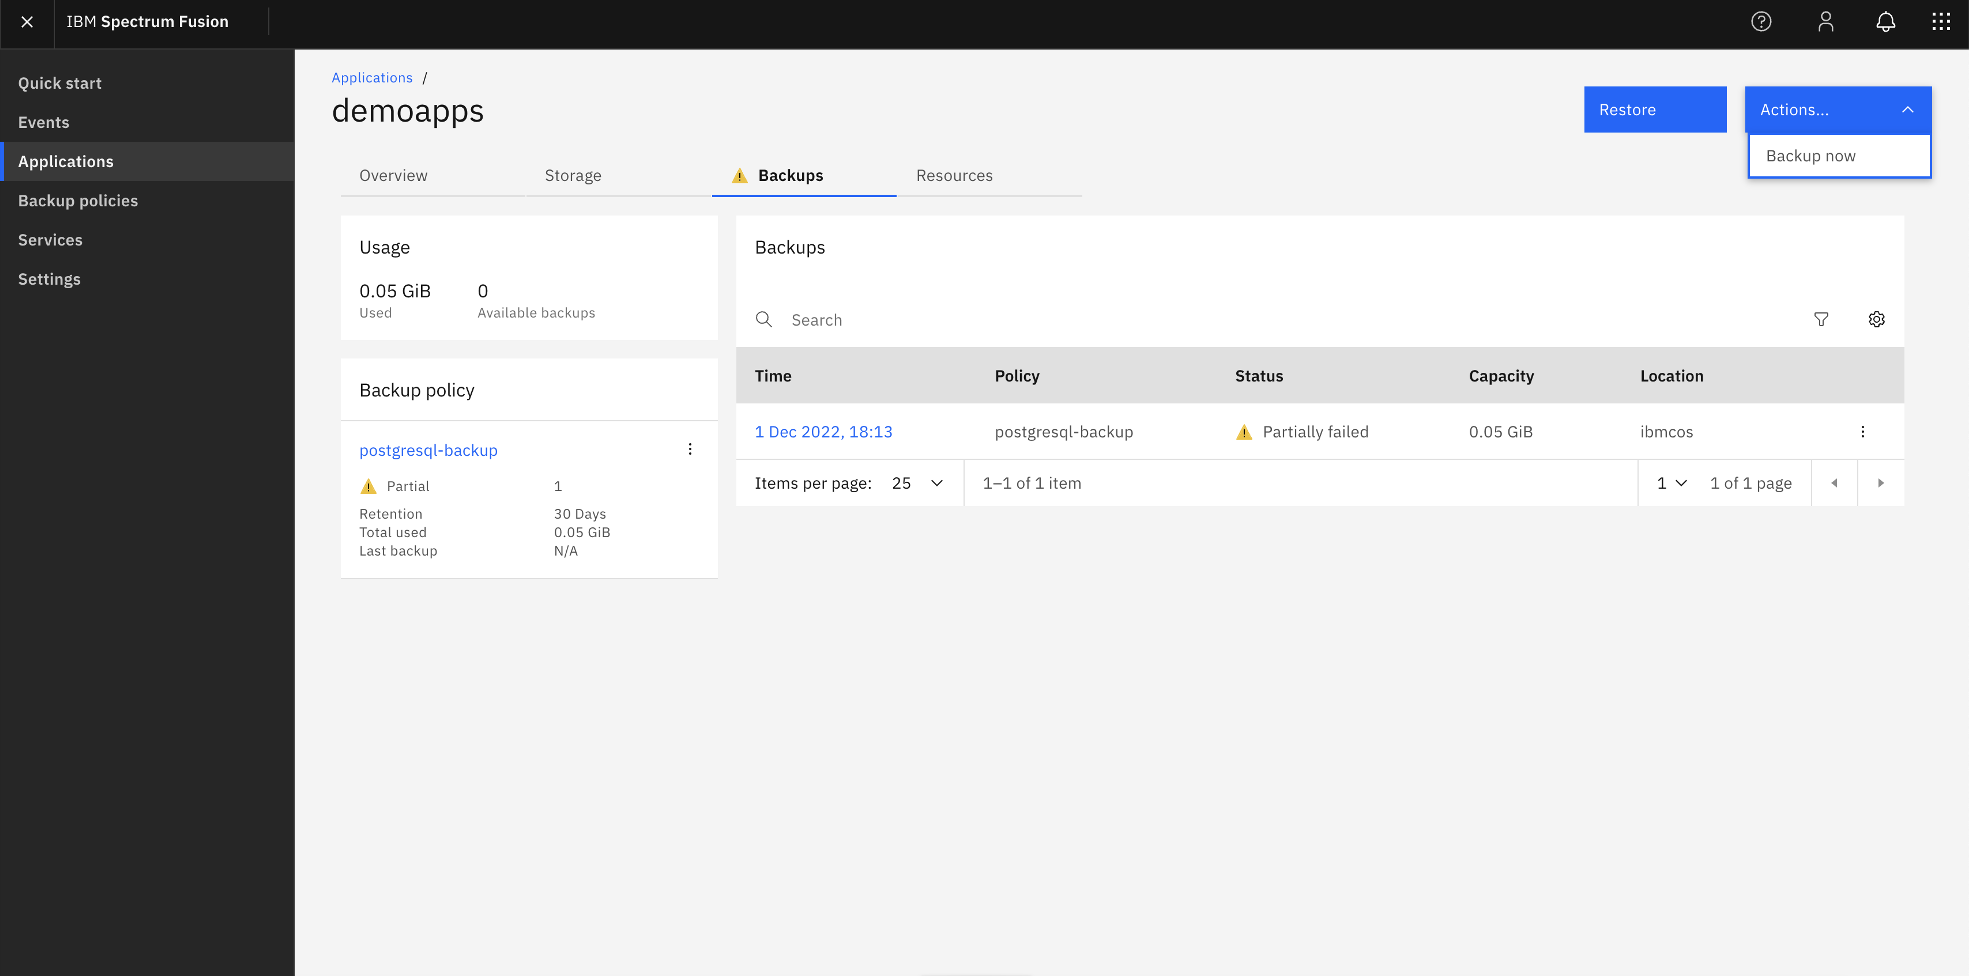
Step 5. Run an on-demand backup
- In the left menu, click Applications.
- In the upper right of the screen, click Actions and select Backup now
Step 6. Create an application-consistent backup
IBM Storage Fusion backs up application data consistently across all the persistent volumes (PVs). It ensures that the recovered data is error-free, reliable, and usable.
For this application-consistency approach, application input and output must be paused using hooks before a snapshot is taken. This kind of backup achieves the highest level of consistency but comes at the cost of application downtime, which can be disruptive. The length of the pause will depend on the application. For instructions about specifying these application hooks, see Backing up application-consistent data in the IBM Spectrum Protect Plus documentation.
Set up backup hooks
When you perform a backup, you can run one or more commands in a container in a pod when that pod is being backed up. The commands can be configured to run before any custom action processing (“pre-” hooks), or after all custom actions have been completed and any additional items specified by custom action have been backed up (“post-” hooks). Note that hooks are not executed within a shell on the containers.
To learn more about backup hooks see Backup hooks in the Velero documentation.
Note: You can apply pre- and post-backup hook annotations directly to the declarative deployment. Following is an example of how you might update an object in place:
oc annotate pod -n demoapps -l name=postgresql
pre.hook.backup.velero.io/command='["/bin/bash", "-c", 'psql -c ""select pg_start_backup('app_cons');""']'
    \ pre.hook.backup.velero.io/container=postgresql
post.hook.backup.velero.io/command='["/bin/bash", "-c", 'psql -c ""select pg_stop_backup( );"""]'\
post.hook.backup.velero.io/container=postgresql
Restore a backup
Backups made using object storage can be restored to the same project or a new or different project. An in-place snapshot can only be restored to the same project.
If you are restoring a project that has been deleted from Red Hat OpenShift, an in-place snapshot will not include Persistent Volume Claims (PVC).
Restore a backup from object storage
- In the left menu, click Applications. Find and open the application that you want to restore and click Restore.

- In the Restore type section, select whether to restore to a different project or restore to the same project.
- Optional: If you are restoring to a new or different project, in the OpenShift Project section, select New Project and enter a name for the project.
- In the Successful backups section, select a successful backup and click Restore.

- Optional: If you are restoring to the same project and want to restore the application’s missing resources and PVC, select a successful backup from the list, select the PVCs to restore and then click Restore.

Summary and next steps
In this tutorial, you have learned how you can use IBM Storage Fusion to backup and restore your mission-critical data and applications. You set up a 3-node Red Hat OpenShift Kubernetes Service cluster and completed an installation of OpenShift Data Foundation software-defined storage for ROKS. You then installed and configured IBM Storage Fusion Operator in an OpenShift cluster. You have also learned how to backup and restore a container application specifically to IBM Cloud Object Storage.
Find out more about IBM Storage Fusion and storage options: