Tutorial
Build a local RAG system with NVIDIA DGX Spark and OpenRAG
Build an enterprise-ready retrieval-augmented generation (RAG) workflow on a compact AI system, combining local document retrieval, vector search, and generative AI for fast, private, and scalable knowledge applicationsIn this tutorial, you turn an NVIDIA DGX Spark into a powerful local RAG system using OpenRAG, an open-source agentic RAG framework. You build a private system that ingests your documents, retrieves the right context, and lets you chat with your knowledge locally on a compact, powerful machine, using only a few prompts.
Before you start, consider why the DGX Spark is such a remarkable piece of hardware. At a high level, NVIDIA DGX Spark delivers 1 petaFLOP of AI performance in a box about the size of a Mac mini. A FLOP is a simple mathematical computation (addition, subtraction, multiplication, or division) that a computer can execute in 1 second. A petaFLOP is 1 quadrillion FLOPs. For perspective, the first petaFLOP-capable computer, IBM Roadrunner, filled 296 racks in 2008, occupied 6,000 square feet, used 2.35 megawatts of power, and cost about $100 million. A system that required massive resources not long ago can now sit on your desk for about $4,000.
Although this tutorial uses DGX Spark to run a fully local, highly capable setup, OpenRAG can run on any laptop and does not require a dedicated GPU. It supports a wide range of models, but this tutorial uses Ollama to host NVIDIA Nemotron 3 Super as the large language model (LLM) and EmbeddingGemma for embeddings. OpenRAG can decide when to search, call the right tools, retrieve additional context, and refine its response until it has enough information to provide a grounded answer.
OpenRAG packages together:
- Langflow – for agent and data‑flow orchestration.
- OpenSearch – for indexing and queries (the R in RAG).
- Docling – for state‑of‑the‑art document and content extraction.
- OpenRAG Application Layer – to pull all the application parts together.
- Terminal user interface (TUI) – for setup and monitoring.
Step 1: Get an AI coding agent
Use an AI coding agent that can control your terminal.
Warp is one option. You can also use Claude Code, Cursor, or IBM Bob.
- Sign up for the free trial.
- Install Warp either:
- Directly on the Spark
- On your local machine and then shell into the Spark
Installing Warp on your local machine and connecting to the Spark is usually more convenient.
In Warp, choose your model. For this tutorial, use GPT-5.4 with reasoning effort set to high. The "auto" setting and other models also work.
Step 2: Install Ollama (the model server)
Use Ollama because it is fast and easy to use.
In Warp on the Spark, issue the following prompt.
Prompt:
Install ollama and start it as a system service.
Step 3: Load models into Ollama
Now load and test the models.
Prompt:
Load the latest version of nemotron‑3‑super into ollama and test it. Prefer NVFP4 quantization if it is available.
Prompt:
Install the latest embeddinggemma in ollama and test it.
Prompt:
Install the uv package manager so Python tools can be executed in isolated environments.
Prompt:
Use uv to create a new project and virtual environment using Python 3.13. Call the project
Change my_project to whatever name you like.
A quick warning:
Review the agent's actions when it runs these prompts.
For example, when prompted for embeddinggemma, the agent initially pulled Gemma instead. Correct the model if this occurs.
Step 4: Start OpenRAG
Start OpenRAG.
Prompt:
Start openrag in my_project. Start OpenRAG using the terminal user interface (TUI) within the project environment using the --tui flag.
The OpenRAG TUI opens.
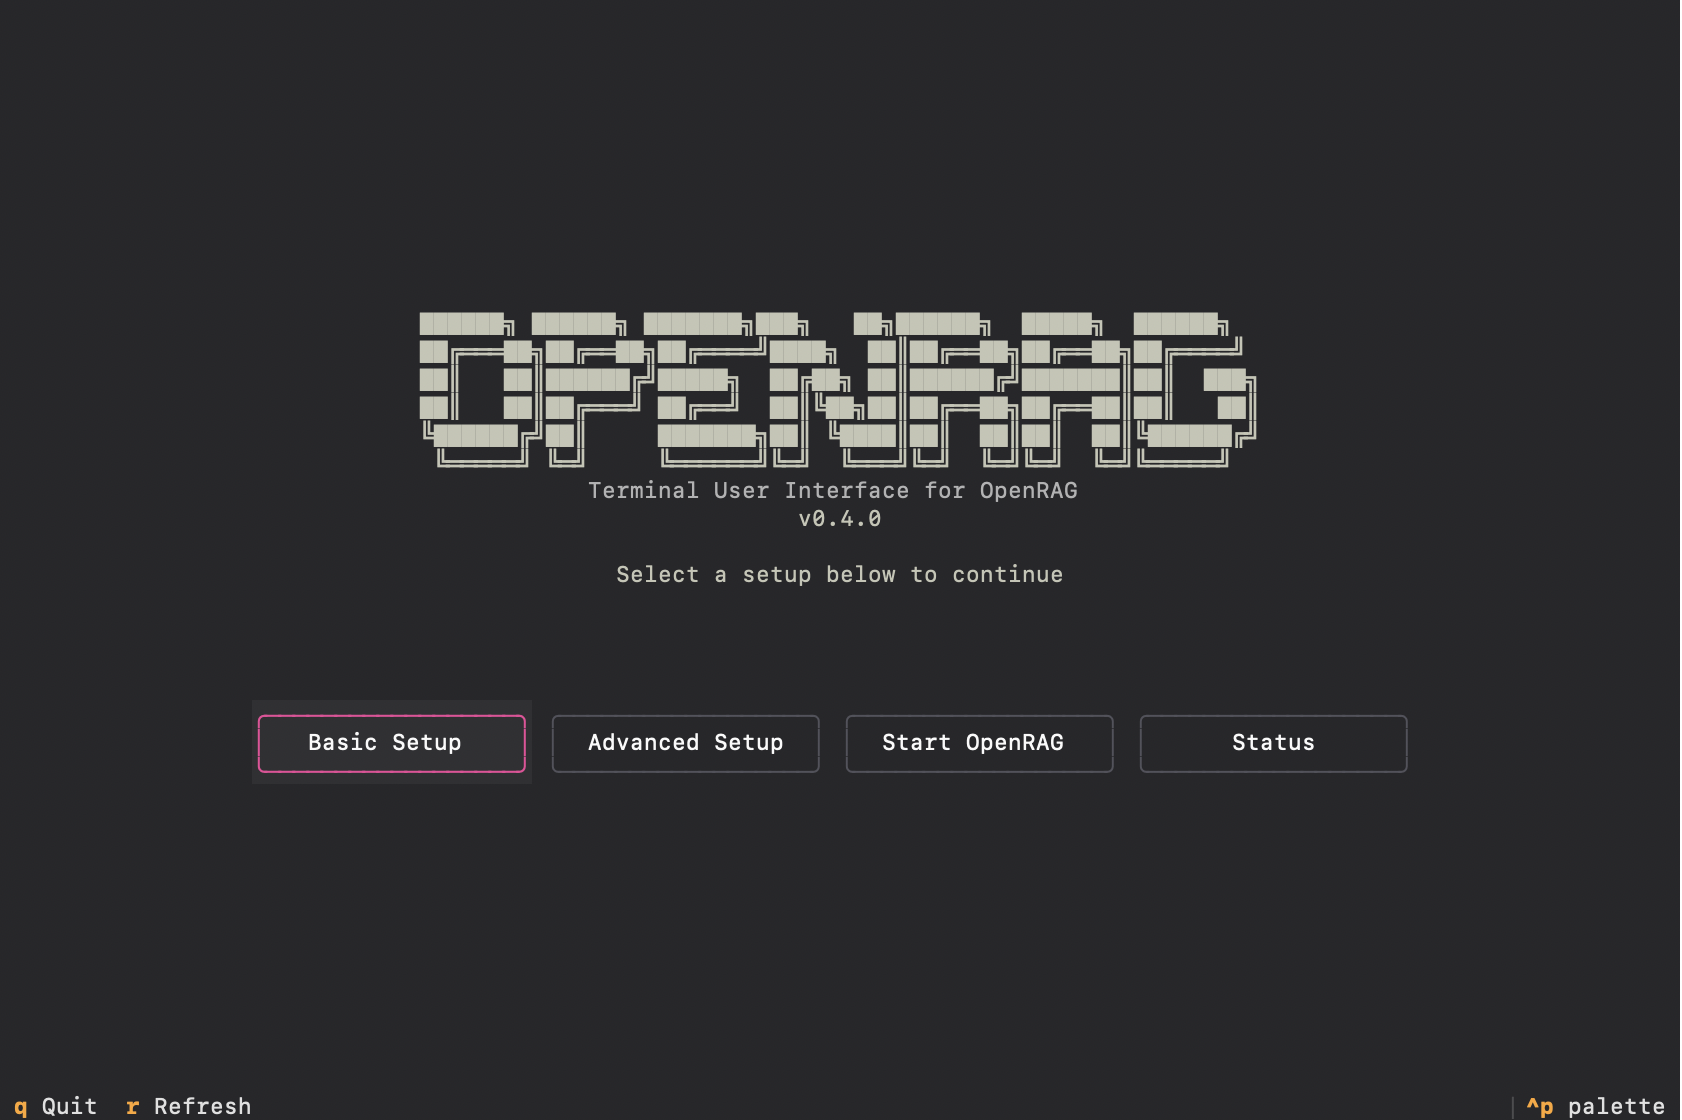
Step 5: Set up OpenRAG
From the TUI:
- Follow the Basic Setup path.
- Choose a password that meets the complexity requirements. Write it down.
- Save and start the services.
OpenRAG downloads and starts all required containers. This process can take some time on slower connections.
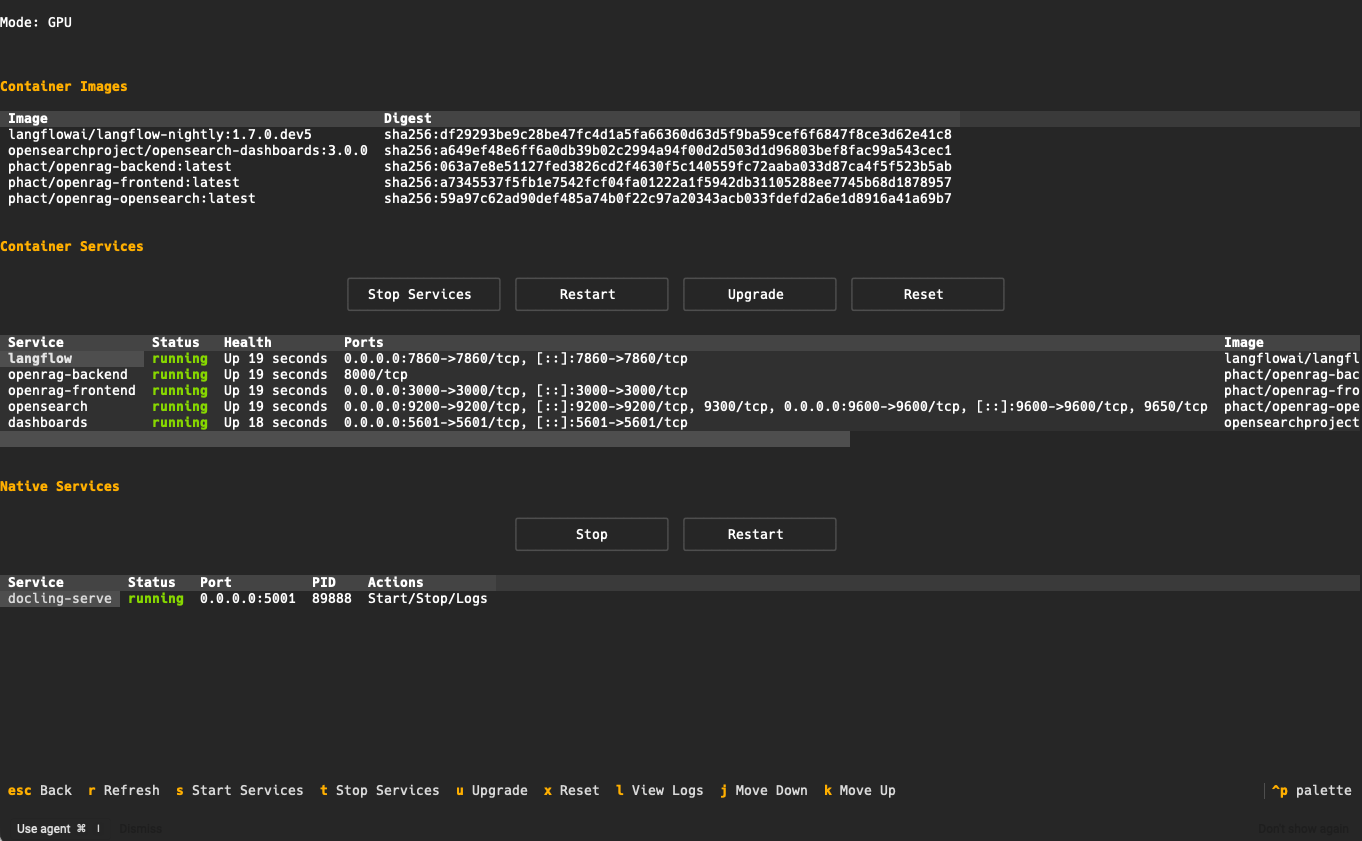
Once everything is running, click the Status button.
You should see Mode: GPU in the top corner. This status indicates that GPU acceleration is enabled.
Step 6: Access the web UI
In the status screen, note the openrag-frontend entry. It will show an IP address and port (usually 0.0.0.0:3000).
If you are on the Spark desktop, open
http://localhost:3000.If you connect over SSH from another machine, use
http://<spark-ip>:3000.
This opens the OpenRAG web UI.
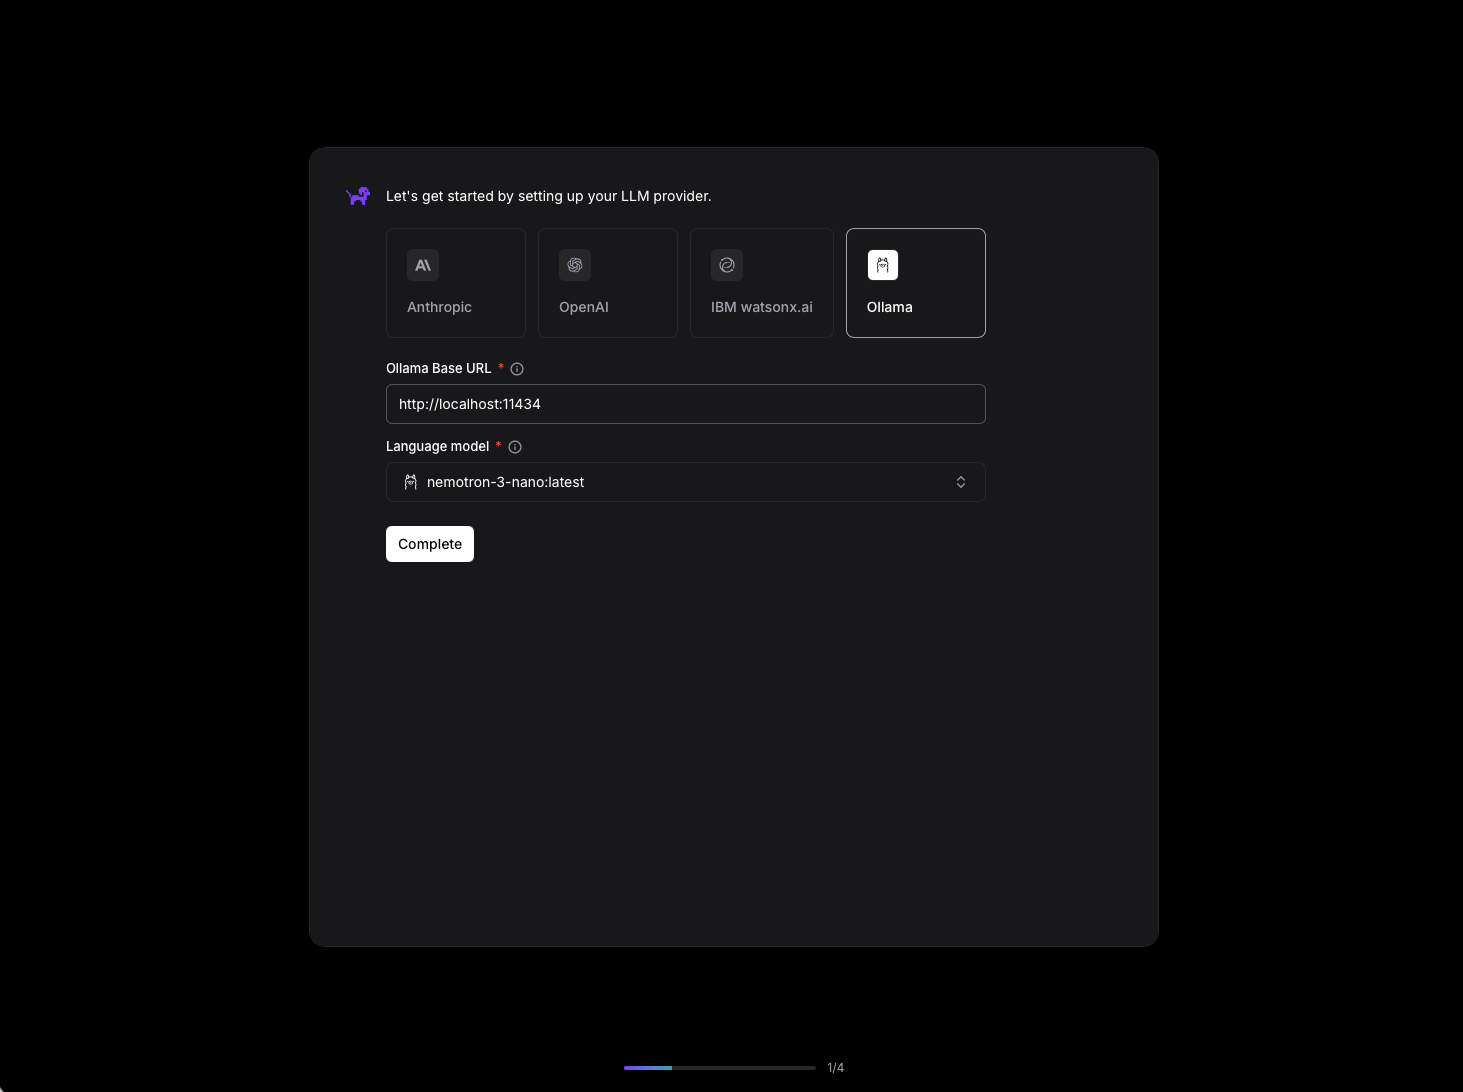
Step 7: Configure the agent
When you set up the agent:
- Choose Ollama as the provider.
- Confirm the Base URL (should already be correct).
- Select Nemotron‑3‑Super from the model drop-down.
If the model is not already loaded, it might take approximately 30 seconds to load into memory.
The UI then guides you through ingesting and discussing your first document, such as a PDF file or Word document.
Step 8: Explore the Langflow logic
Finally, examine the agent logic.
In OpenRAG, select Settings > Agent > Edit in Langflow.
This opens the Langflow canvas where the agent’s logic is defined.
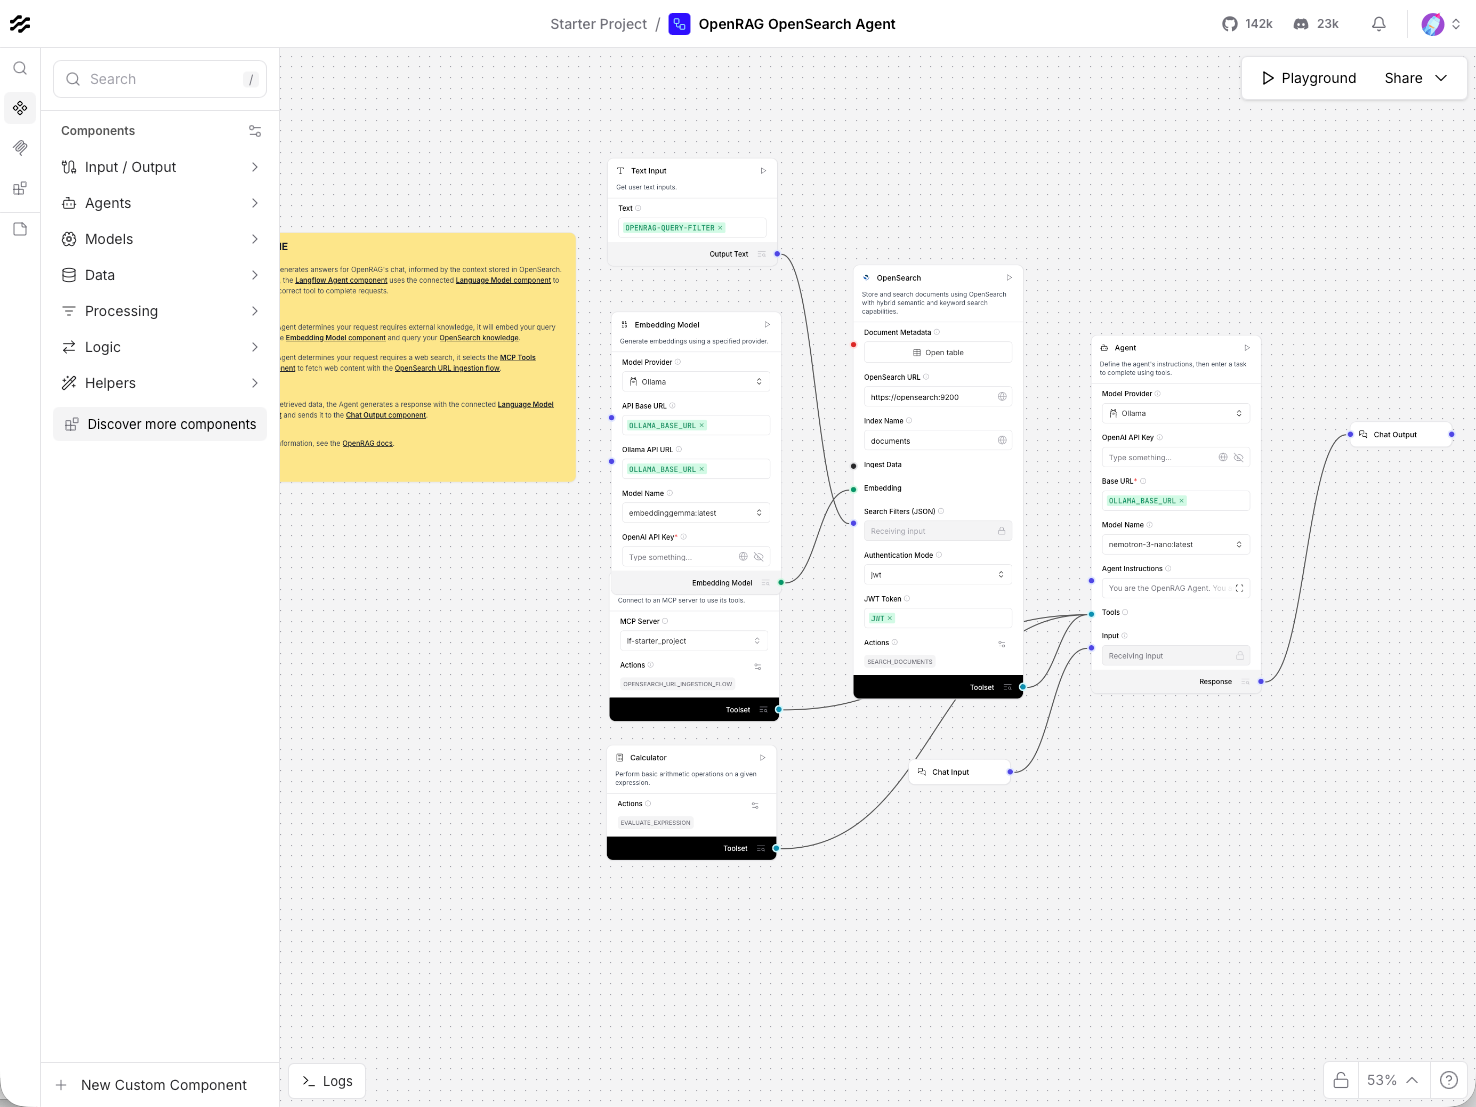
From here, you can explore the other flows that power OpenRAG, such as:
- The main agent flow
- Additional flows for ingesting files and URLs
- How retrieval, prompting, and responses are wired together
Use the OpenRAG UI to ingest more documents in the Knowledge section. OpenRAG connects AI workflows to knowledge bases stored locally or in cloud storage systems such as Google Drive, Microsoft OneDrive, or Amazon S3. OpenRAG supports more than 20 file types, including PDFs, images, PowerPoint presentations, and Excel files. When you ask the agent a question, it checks the knowledge that you provide.
All of this runs offline on your private petaFLOP AI system. OpenRAG can also run on a CPU and use popular model-hosting providers. However, running models locally requires a capable GPU. The required GPU capability depends on several factors that highlight the value of this system's design.
The Nemotron 3 family of models uses a hybrid Transformer–Mamba architecture, which reduces inference-time memory pressure in both capacity and bandwidth. The IBM Granite 4.0 family of models uses a similar architecture. Larger models require more memory than most gaming graphics cards provide. The NVIDIA RTX 5090 has 32 GB of VRAM. The NVIDIA DGX Spark has 128 GB of memory shared between its Grace CPU and Blackwell GPU. This configuration supports larger models, such as gpt-oss-120B and Nemotron 3 Super with NVFP4 quantization, while retaining enough memory to run an embedding model and other processes.
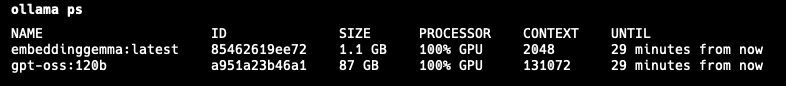
In the previous screen capture, gpt-oss:120b is running because Ollama cannot yet run NVFP4. The Q4_K_M variant of Nemotron 3 Super available in Ollama consumes all available memory. NVFP4-optimized versions of Nemotron 3 Super are available for vLLM, but configuring them correctly requires additional effort. Check whether an NVIDIA NIM is available or whether Ollama supports NVFP4.
Summary
A hybrid edge-and-cloud model is a likely direction for AI deployment. Software can orchestrate a mixture of models and tools on local edge devices, such as the NVIDIA DGX Spark, and in the cloud.
OpenRAG on NVIDIA DGX Spark demonstrates the performance and capabilities of local edge AI. OpenRAG supports this hybrid edge-and-cloud approach today.