Article
Explore the data services underlying IBM watsonx
Use a data fabric approach to define, organize, manage, and deliver trusted data to train and tune AI modelsPowerful AI models start with training data that is high quality and, more importantly, accessible. Organizations seeking to be "AI first" must also be "data first." IBM data services, underlying IBM watsonx and a foundational layer of the IBM generative AI tech stack, are engineered to deliver data at speed and scale across the enterprise. By unifying data access through a data fabric, teams can eliminate data silos and accelerate AI lifecycle workflows.
Data has the potential to be a core differentiator in driving growth and transformation for an organization's business processes. Both a data strategy and a robust data architecture are necessary to make the most of an organization's data. Managing multiple complex data stores often leads to data silos, which are groups of data that are not easily accessed across the organization. Cumbersome access procedures to organizational data all but ensure that its full potential is never unlocked. A modern architectural approach to data, such as a data fabric, is what modern organizations rely on to shape and transform a data-first enterprise.
Data fabric
Data fabric is an architectural approach that pulls data together from various systems, including data lakes, warehouses, SQL databases, and apps, to equip organizations with a holistic view of and comprehensive access to their data. This data fabric approach enables access to data wherever it lives in a hybrid cloud environment, whether it is on-premises, in multiple clouds, or both.

IBM data services
The IBM data services layer is driven by 4 core services that deliver the key functionalities of a data fabric architecture:
- Platform connections to data sources
- Extract, transform, load capabilities
- Synthetic data generation
- Data processing and refinement
Platform connections
Within IBM watsonx, different data assets such as databases, cloud object storage buckets, query engines, and data catalogs are organized into platform catalogs. These catalogs house connectors to access the various data sources:

After you select an asset to add to a catalog, you are prompted to enter the necessary credentials to create a permanent platform connection. These assets can then be added to IBM watsonx or IBM Cloud Pak for Data projects, and you can query data by using the connectors or virtualize data with Watson Query. Connections address the challenges of siloed data sources by unifying data from multiple sources into a single platform, enabling real-time data analysis and insights.
Extract, transform, load
Extract, transform, load (ETL) is a process of combining and harmonizing data from multiple sources into a single, consistent data set for loading into a target system for various analytical, operational, and decision-making purposes. Frequently, insights are needed from data that is stored in multiple sources.
ETL starts with copying or exporting data from a source location into a staging area. Then the data is processed for its intended analysis through data cleansing and transformation. Finally, once the data is in its desired form, the data is loaded into a target source for analysis and business intelligence.
IBM DataStage is the IBM data integration tool that helps you design, develop, and execute jobs to move and transform data. Using a graphical interface in DataStage, you can design data flows that support ETL processes. DataStage is compatible with many IBM and third-party data sources and can load data directly into an IBM watsonx.data data lakehouse.

Synthetic data generator
Synthetic data is data based on real data sets but artificially generated through computer simulations or algorithms. Synthetic data is important because it can aid with research, testing, and development when there is a limited amount of real data. In industries such as healthcare or finance where data privacy is important, synthetic data can help ensure compliance with regulations and organizational policies. Synthetic data is also commonly used to generate data sets for training large language models. Read the IBM Research study on LLM-generated synthetic data.
In IBM Cloud Pak for Data and IBM watsonx, the Synthetic Data Generator is a graphical flow tool that you can use to generate synthetic tabular data based on imported data, production data, or a custom schema. Learn more about generating synthetic tabular data in the IBM watsonx synthetic data documentation.

This no-code solution for synthetic data generation makes it simple for organizations to get reliable and usable data sets that can ultimately accelerate data-driven decision-making.
Data Refinery
Data Refinery is a tool offered in IBM watsonx.ai and IBM Knowledge Catalog. Its function is to simplify data transformation by cleaning and processing raw data before it is used for analytics.
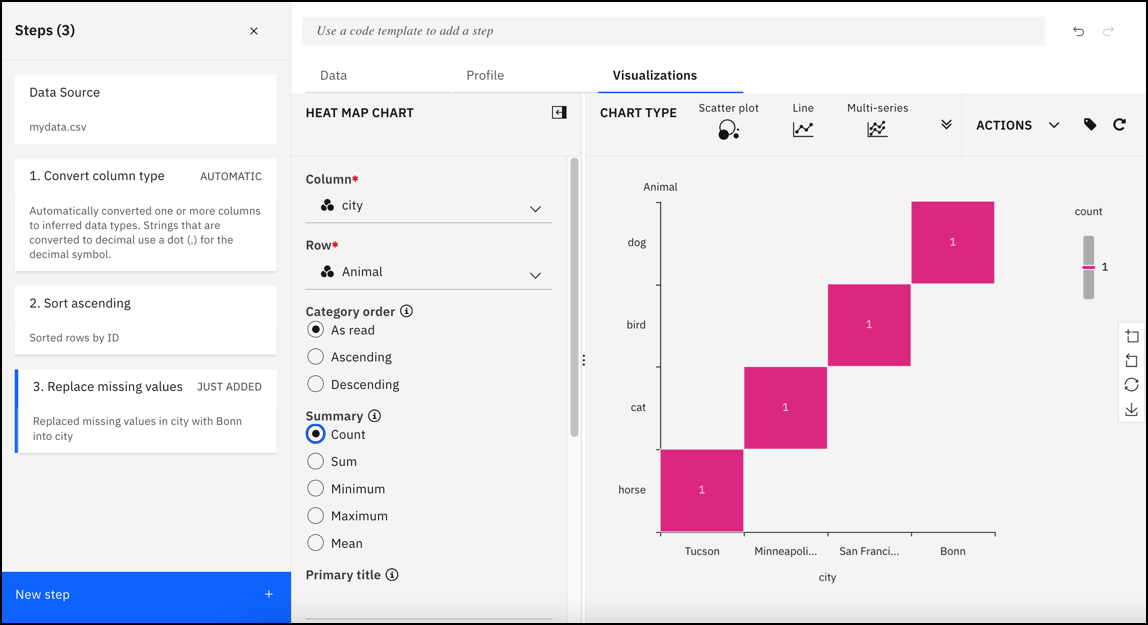
This is accomplished through more than 100 out-of-the-box operations for data cleansing and reshaping. The tool also provides visual representations of data quality and distribution with charts and graphs. This capability is helpful for performing quick exploratory data analysis for machine learning without writing code.
Summary and next steps
Data services form the foundation for a strong data fabric approach to managing enterprise data. These capabilities are provided through the different data services tools offered in IBM watsonx and IBM Cloud Pak for Data, including platform connections, ETL, synthetic data generation, and Data Refinery. Learn more about how IBM watsonx can help your organization become AI first.
Learn more about watsonx and the IBM generative AI tech stack
Now that you have learned about IBM data services, learn more about the IBM watsonx enterprise data and AI platform, which is the foundation for the generative AI tech stack.
Try watsonx.data — IBM's data lakehouse. Try watsonx.ai — the next-generation studio for AI builders.
Explore more articles and tutorials about watsonx on IBM Developer.