Tutorial
Automate real-time streaming with IBM Bob, Confluent Cloud for Apache Flink, and HCP Terraform
Generate Terraform configurations with IBM Bob to build a fraud detection system using Confluent Cloud's managed Kafka and Flink servicesBuilding and deploying real-time streaming systems can be complicated. These systems require complex distributed platforms like Apache Kafka and Flink. Confluent Cloud simplifies this with fully managed services including connectors, Schema Registry, Flink stream processing, and HashiCorp Cloud Platform Terraform. Terraform automates and manages the required Confluent Cloud infrastructure using infrastructure-as-code. IBM Bob makes it even simpler by using spec-driven development (SSD) to generate configurations and code from the ground up.
In this tutorial, you learn how to use IBM Bob to build a real-time banking fraud detection system using Confluent Cloud (Kafka and Flink) and use HCP Terraform to automate infrastructure provisioning. You also test the real-time streaming system with simulated banking transactions (produced also by Bob) on Kafka and check the fraud detection system on Confluent Cloud.
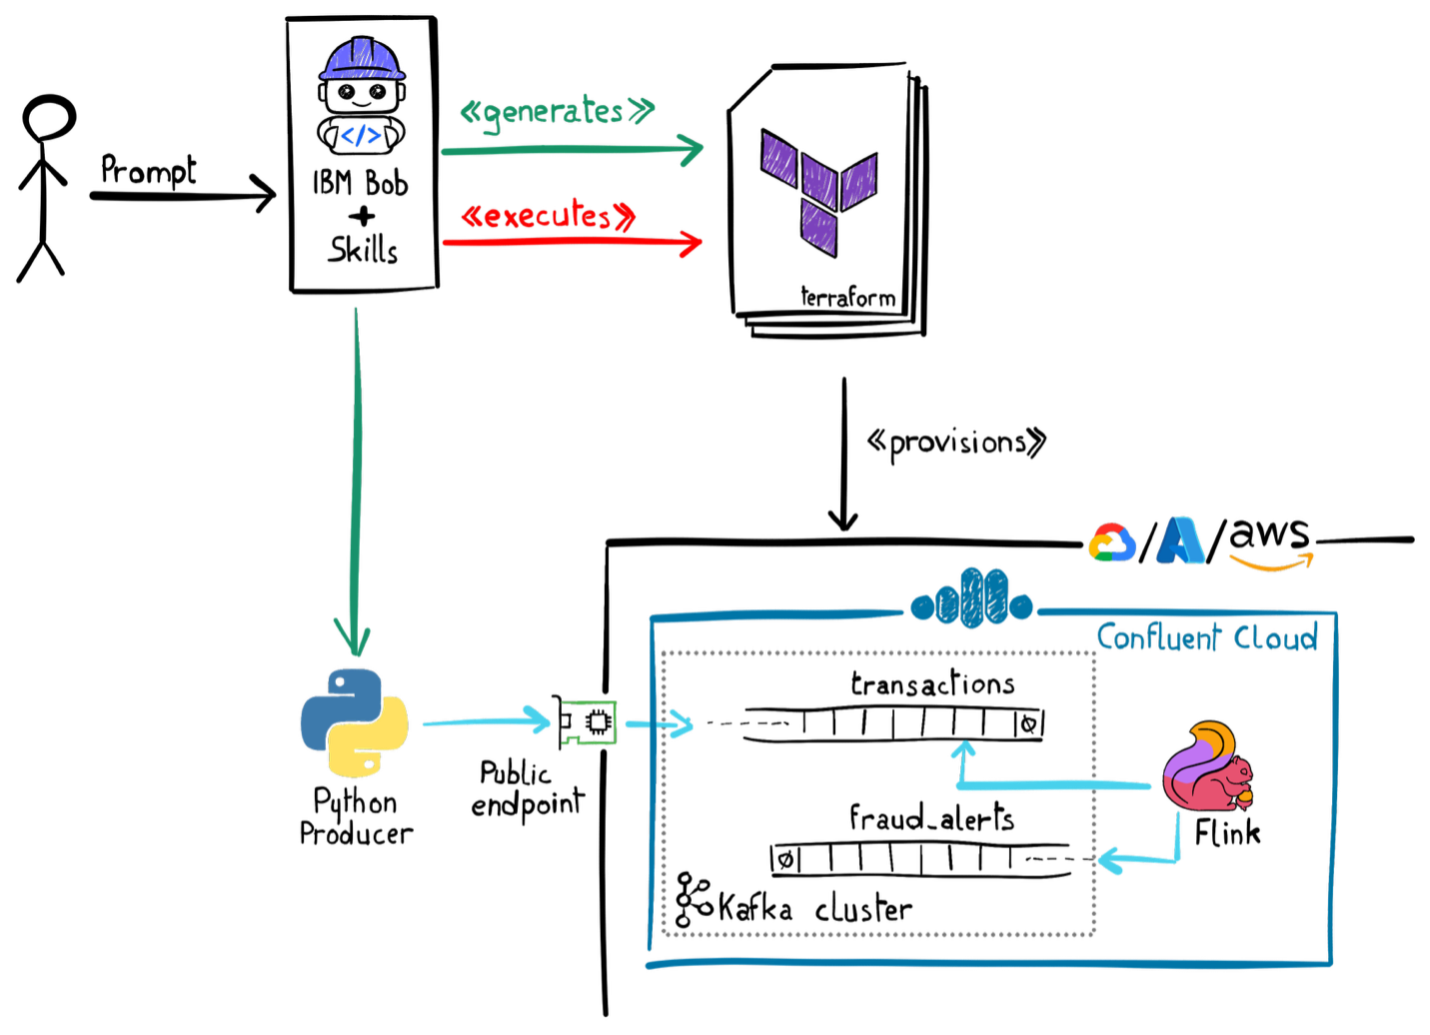
Architecture of the fraud detection system
A fraud detection system requires real-time data capabilities. Confluent Cloud provides this real-time data streaming with Apache Kafka and processes (and aggregates) the events in real time with Apache Flink. Although you can manage these resources using Confluent Cloud, the Confluent Terraform provider enables you to define this infrastructure-as-code.
You can build this real-time streaming system by using an IBM Bob skill that generates the necessary configurations and code.
Prerequisites
IBM Bob installed. Sign up for free trial for Bob.
HashiCorp Terraform installed. Download and install the Terraform version you need.
A Confluent Cloud account. Sign up for a free Confluent Cloud account.
A Terraform Enterprise account. Sign up for a free HCP Terraform account.
Step 1. Create an API key for Confluent Cloud
In this step, you create an API key for Confluent Cloud. The Terraform scripts (that Bob generates) need this API key to provision the Confluent Cloud infrastructure.
Login to Confluent Cloud. From the Hamburger menu in the top right corner, click API Keys.
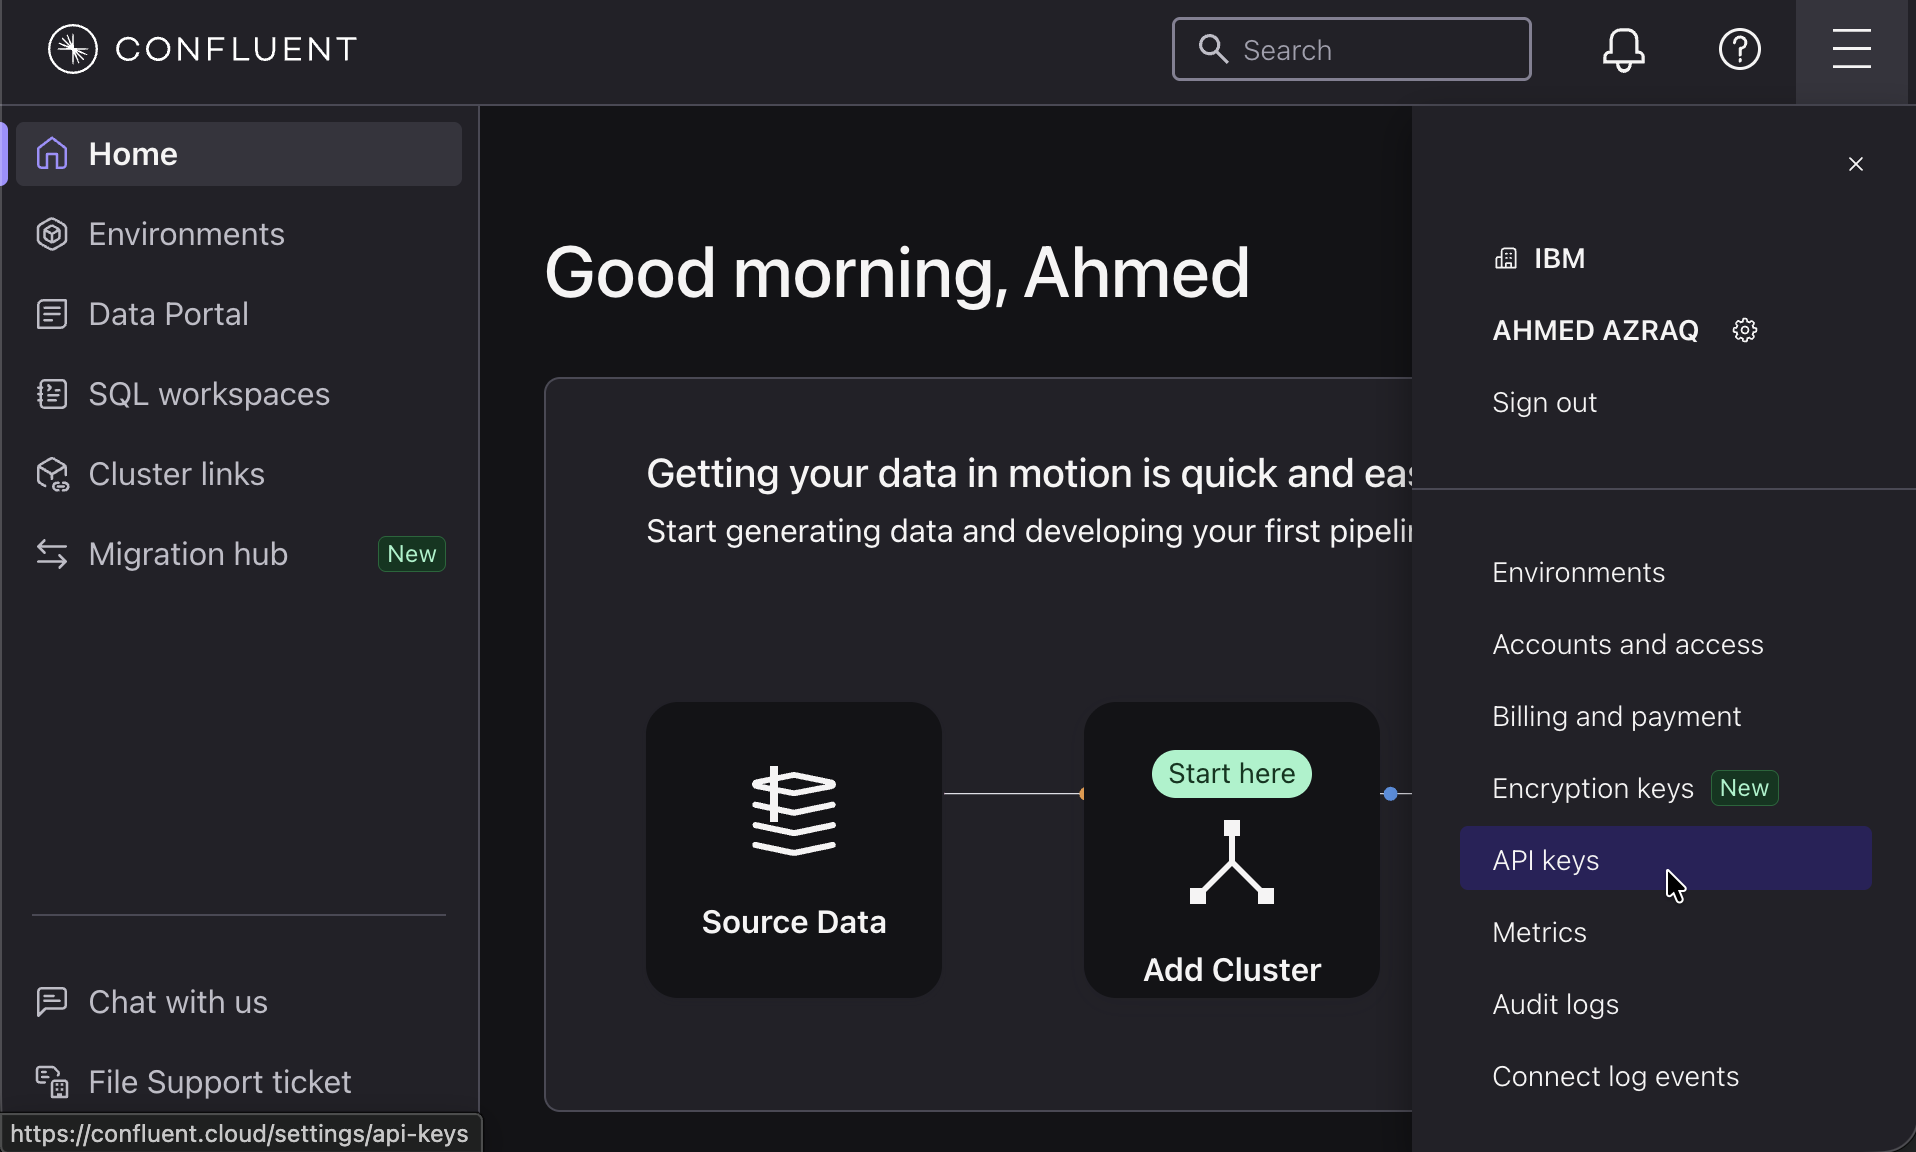
Click + Add API key.
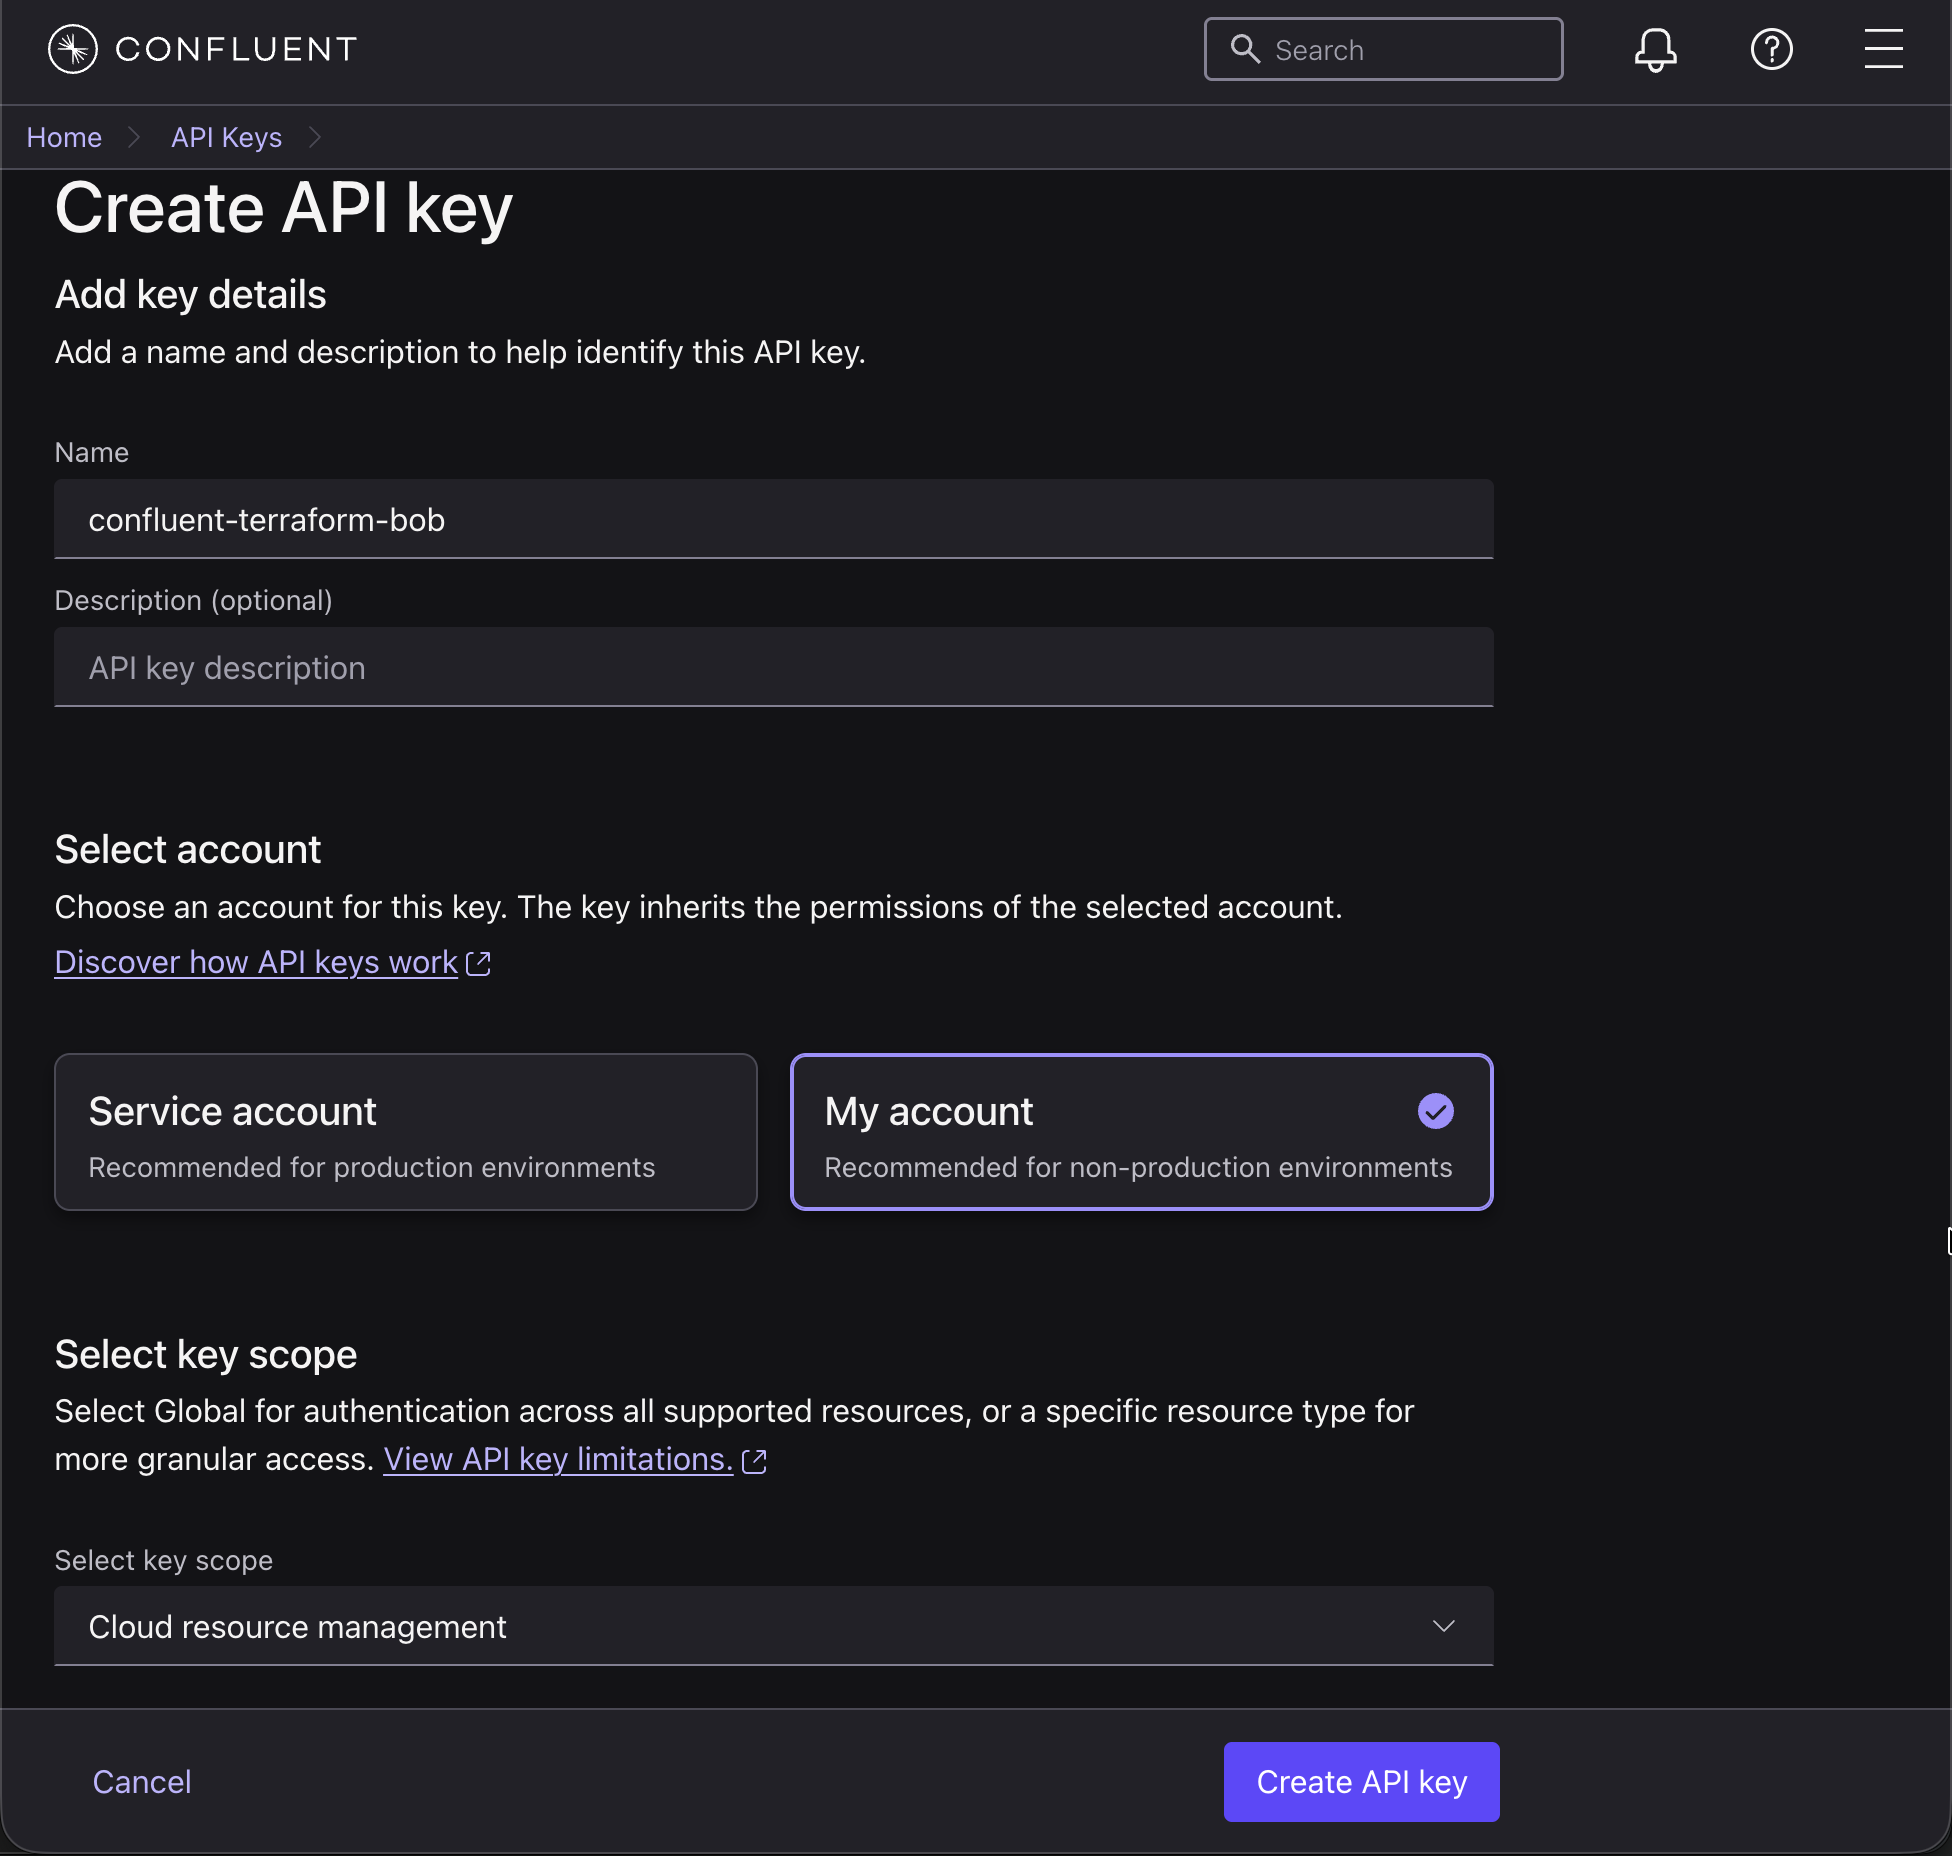
Name the API key
confluent-terraform-bob. For this tutorial, select My account to give the API key the same access as your Confluent account. Under Select key scope, select Cloud resource management, and then click Create API key.For production systems, you should choose Service account for more restricted access
Copy the key and secret and save them somewhere safe so you can paste them in a future step and then click Complete.
Step 2. Create an organization and workspace in HCP Terraform
In this step, create an organization and workspace in HCP Terraform. The organization and workspace help you manage the Terraform configuration, infrastructure resources, users, and access controls.
- Organization: Provides a shared top-level container for managing projects, workspaces, users, and access controls.
- Workspace: Isolates the Terraform configuration, variables, state, and run history for a specific set of infrastructure resources. This isolation makes infrastructure deployments easier and safer to manage.
To create an organization and workspace in HCP Terraform, complete the following steps:
- On the HCP Terraform Organizations page, click Create organization.
- Select an organization type: Business or Personal.
Enter a unique organization name, such as
your-name-confluent-hcp-terraform. Enter your email address, and then click Create organization.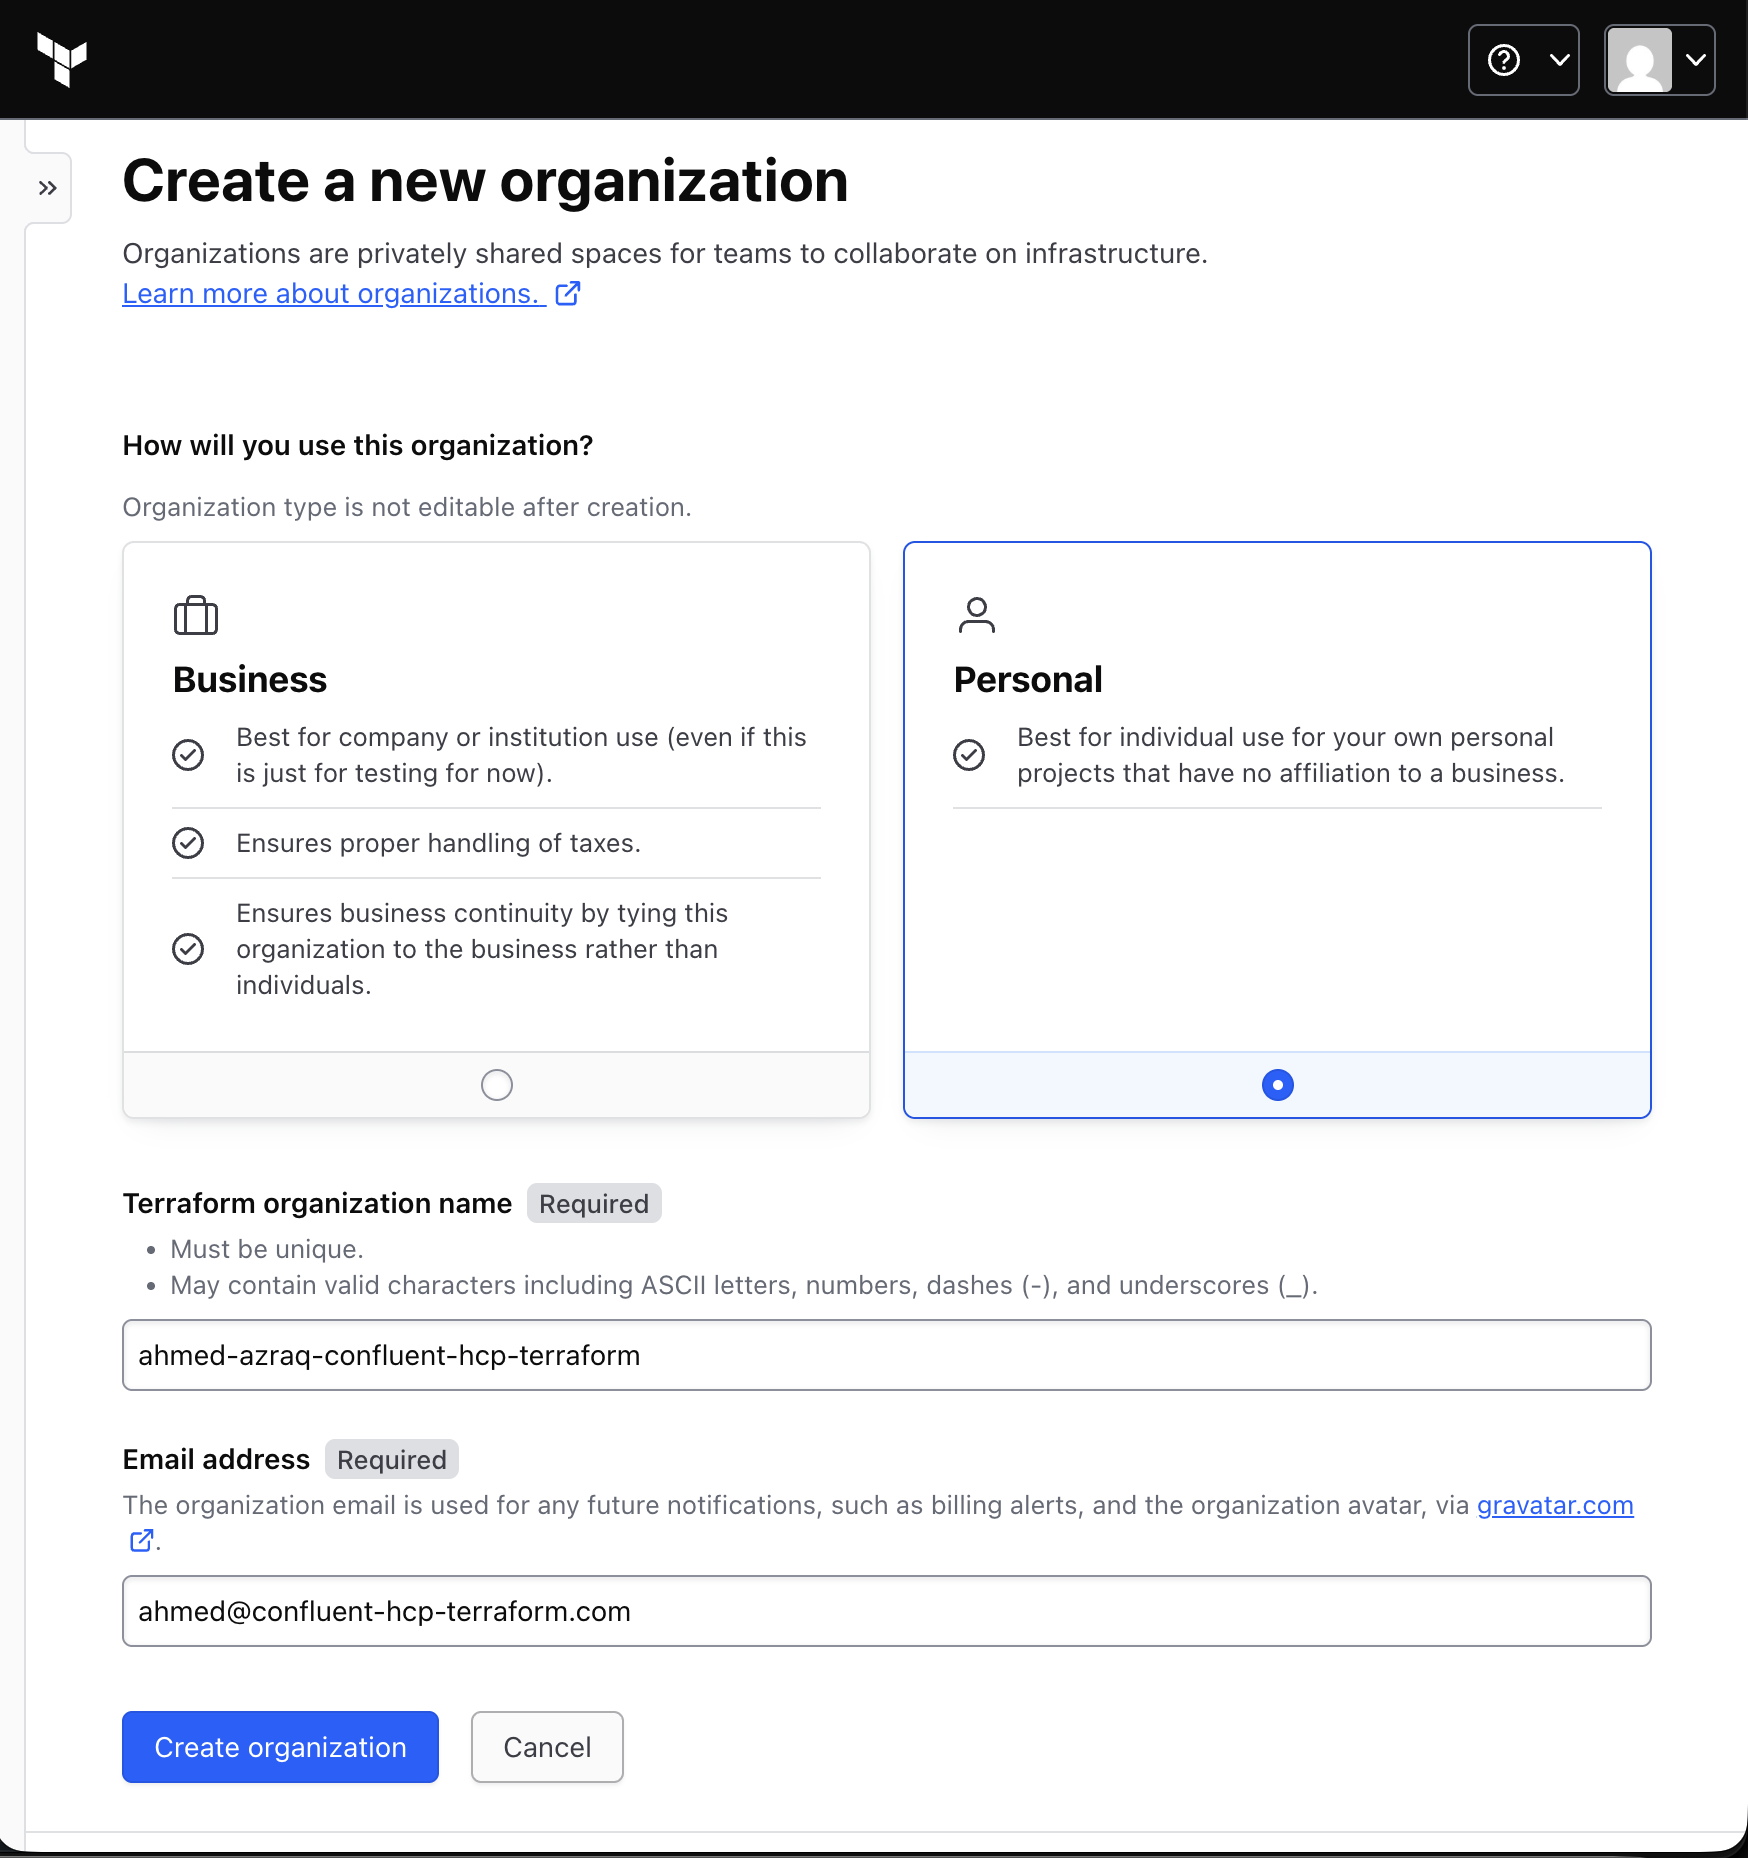
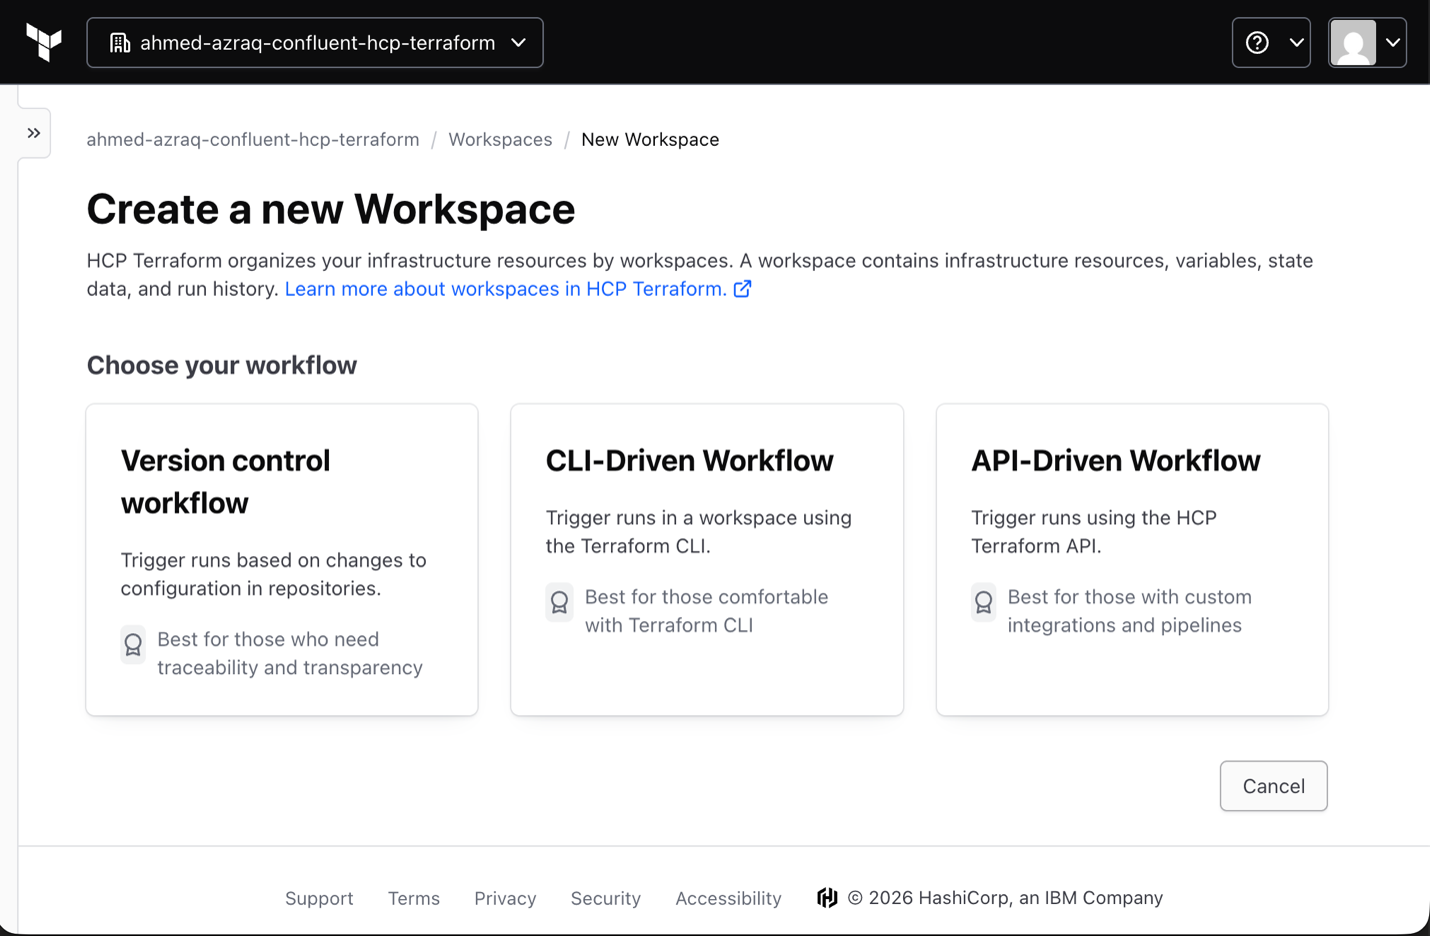
HCP Terraform provides three workflow options when you create a workspace:
- Version control workflow: Connects the workspace to a Git repository and automatically starts Terraform runs when the Terraform configuration changes.
- CLI-driven workflow: Starts remote Terraform runs with Terraform CLI commands. HCP Terraform manages the execution and Terraform state.
API-driven workflow: Uses the HCP Terraform API to upload Terraform configurations and start runs. This workflow is useful for custom integrations.
For this tutorial, select CLI-Driven Workflow. Bob creates the Terraform configuration and runs the Terraform CLI commands. HCP Terraform executes the Terraform operations remotely and manages the Terraform state, so Terraform does not run locally.
Enter
confluent-cloudas the workspace name. Theconfluent-cloudworkspace contains the configuration, variables, state, and run history for the Confluent Cloud infrastructure. Then, click Create.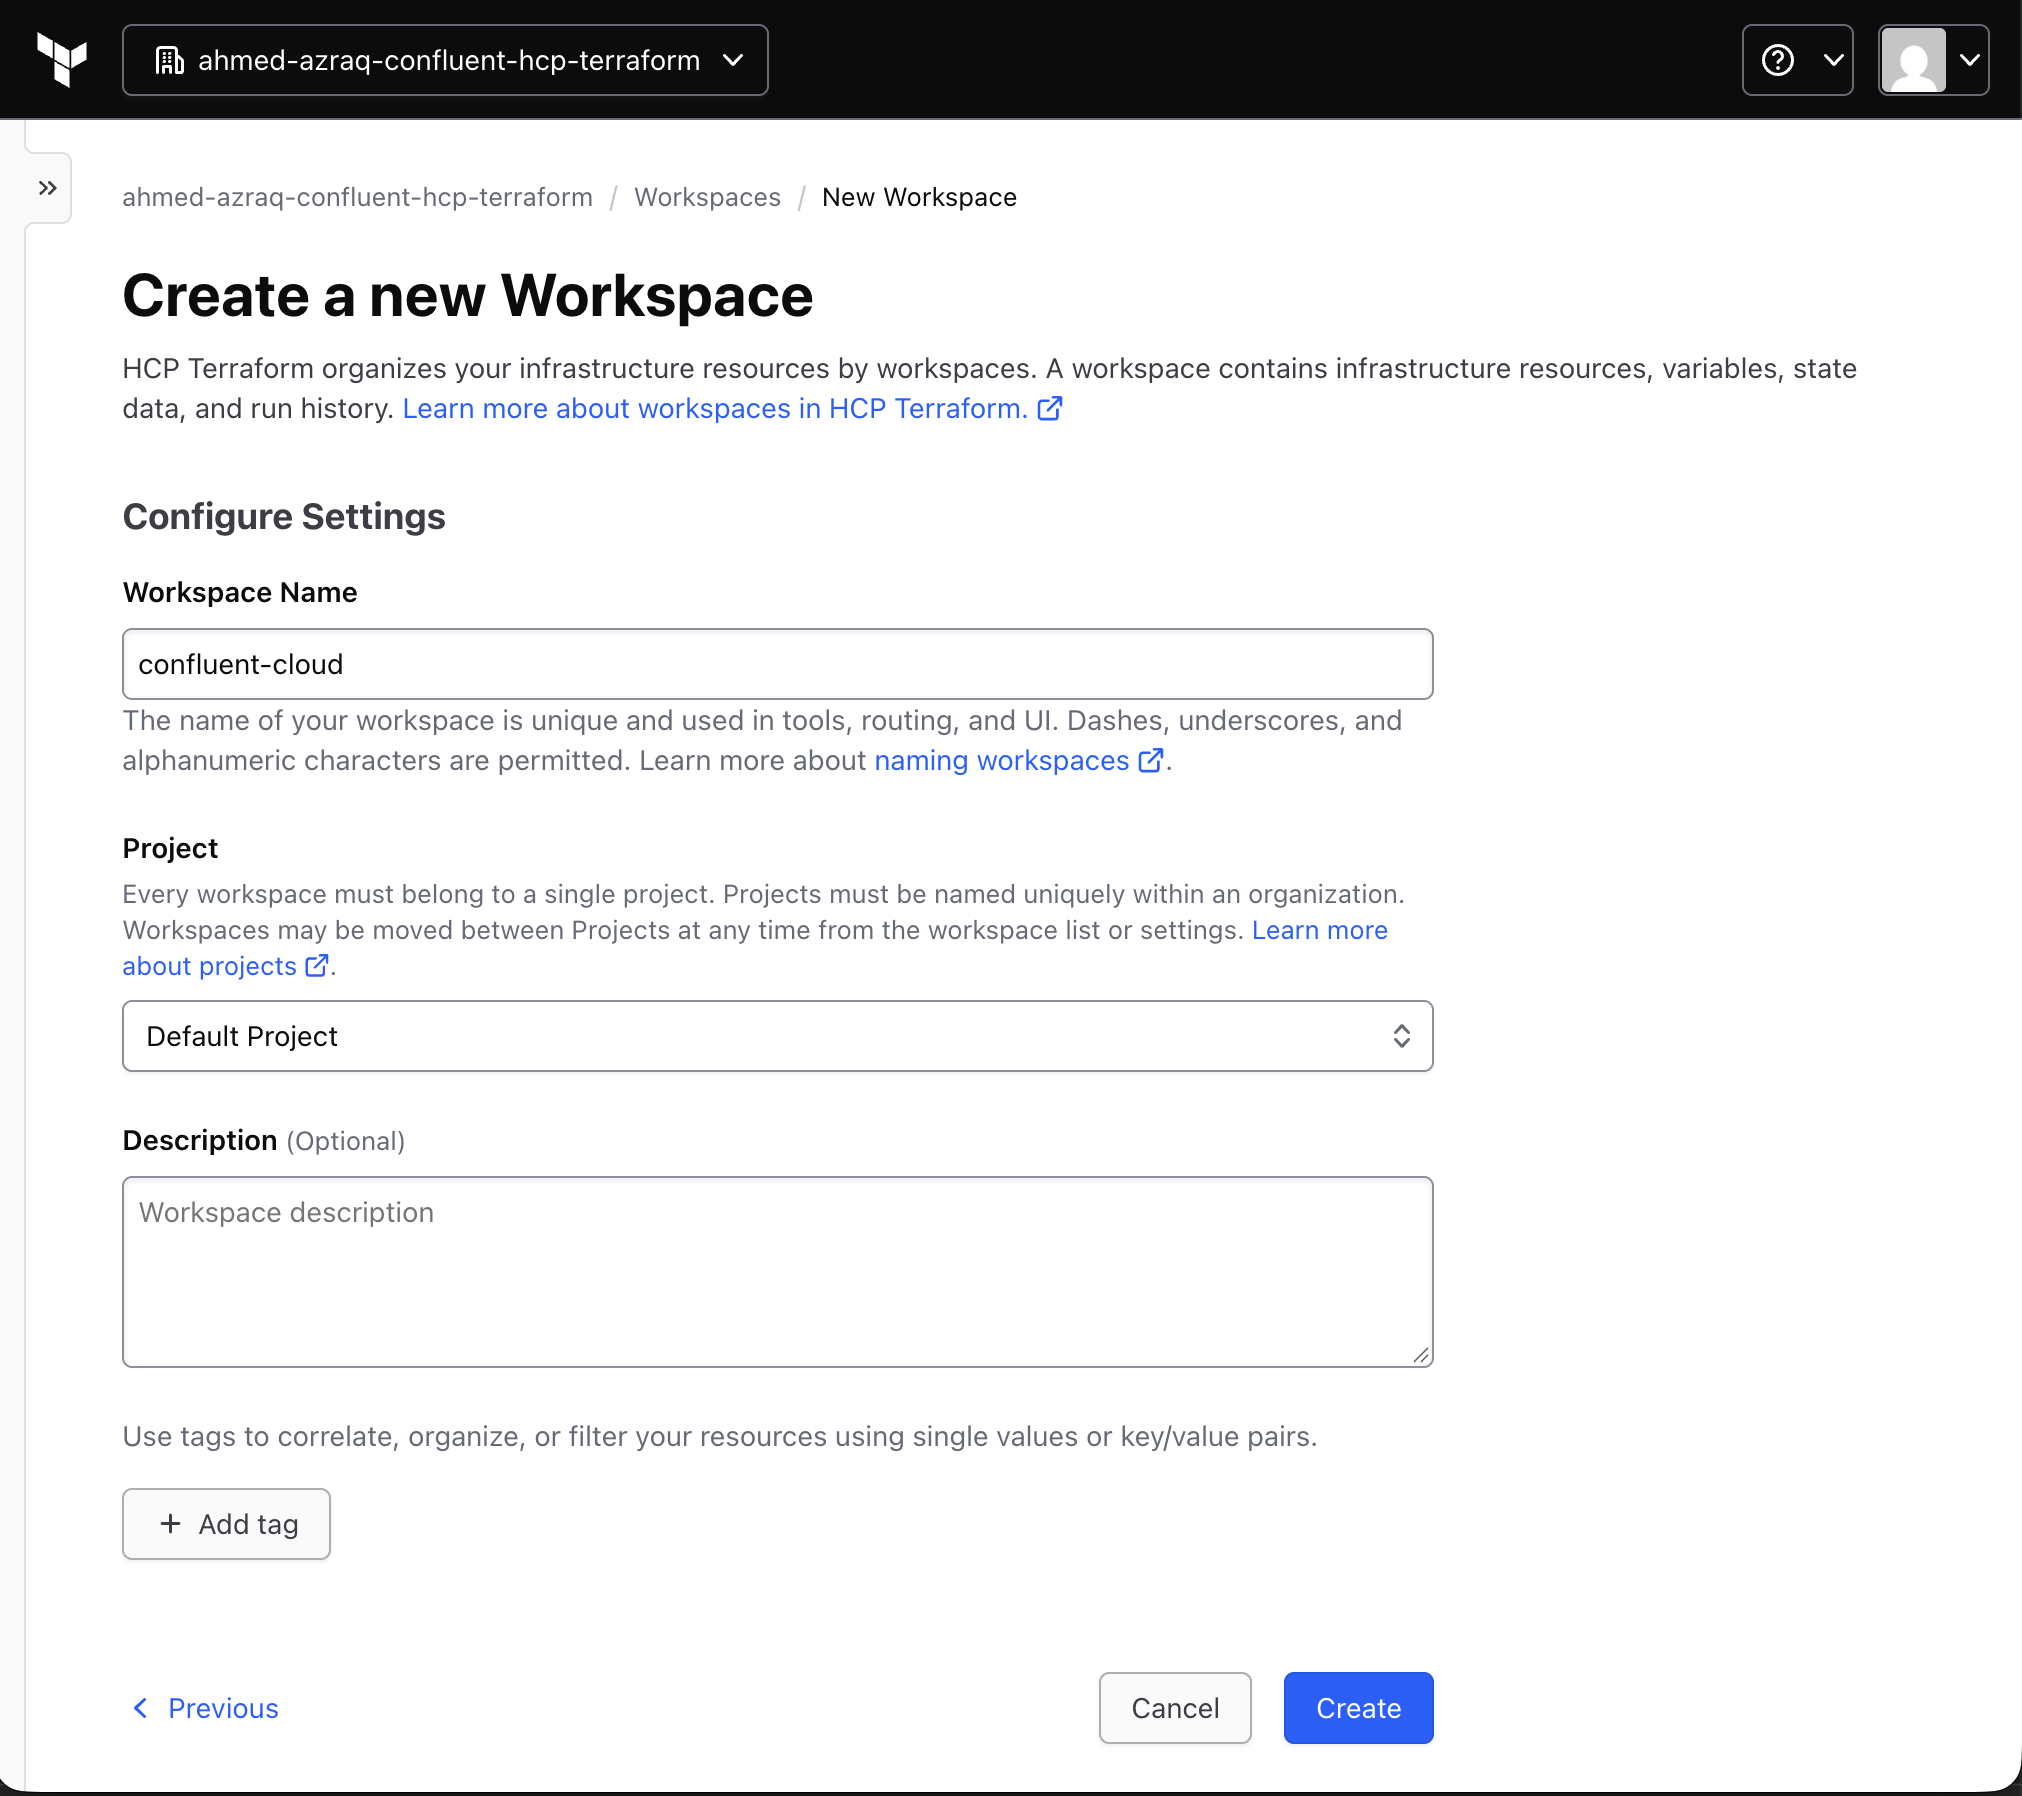
Note the organization name. You will need the organization name in Step 5.

Step 3. Create a Bob workspace and configure the Bob skill
In this step, you create a Bob workspace and configure the confluent-iac-terraform Bob skill. Bob skills are reusable instruction sets that teach Bob new workflows and specialized tasks. The confluent-iac-terraform skill defines the process for analyzing streaming use case requirements and generating complete, production-ready real-time streaming systems on Confluent Cloud using Infrastructure-as-Code (Terraform), Apache Flink SQL, and Python producers.
Open Bob IDE.
Click File > Open Folder.
Click New Folder, and name the folder fraud-confluent-terraform-bob. Then, click Open.
Create a new folder
.bobto store all Bob related configurations.Create a new subfolder
.bob/skillsto store the different skills.Create a new subfolder
.bob/skills/confluent-iac-terraform.Download the SKILL.md from the Technology Building Blocks GitHub repo to this new folder. Make sure that the
SKILL.mdfile is downloaded to the.bob/skills/confluent-iac-terraformfolder.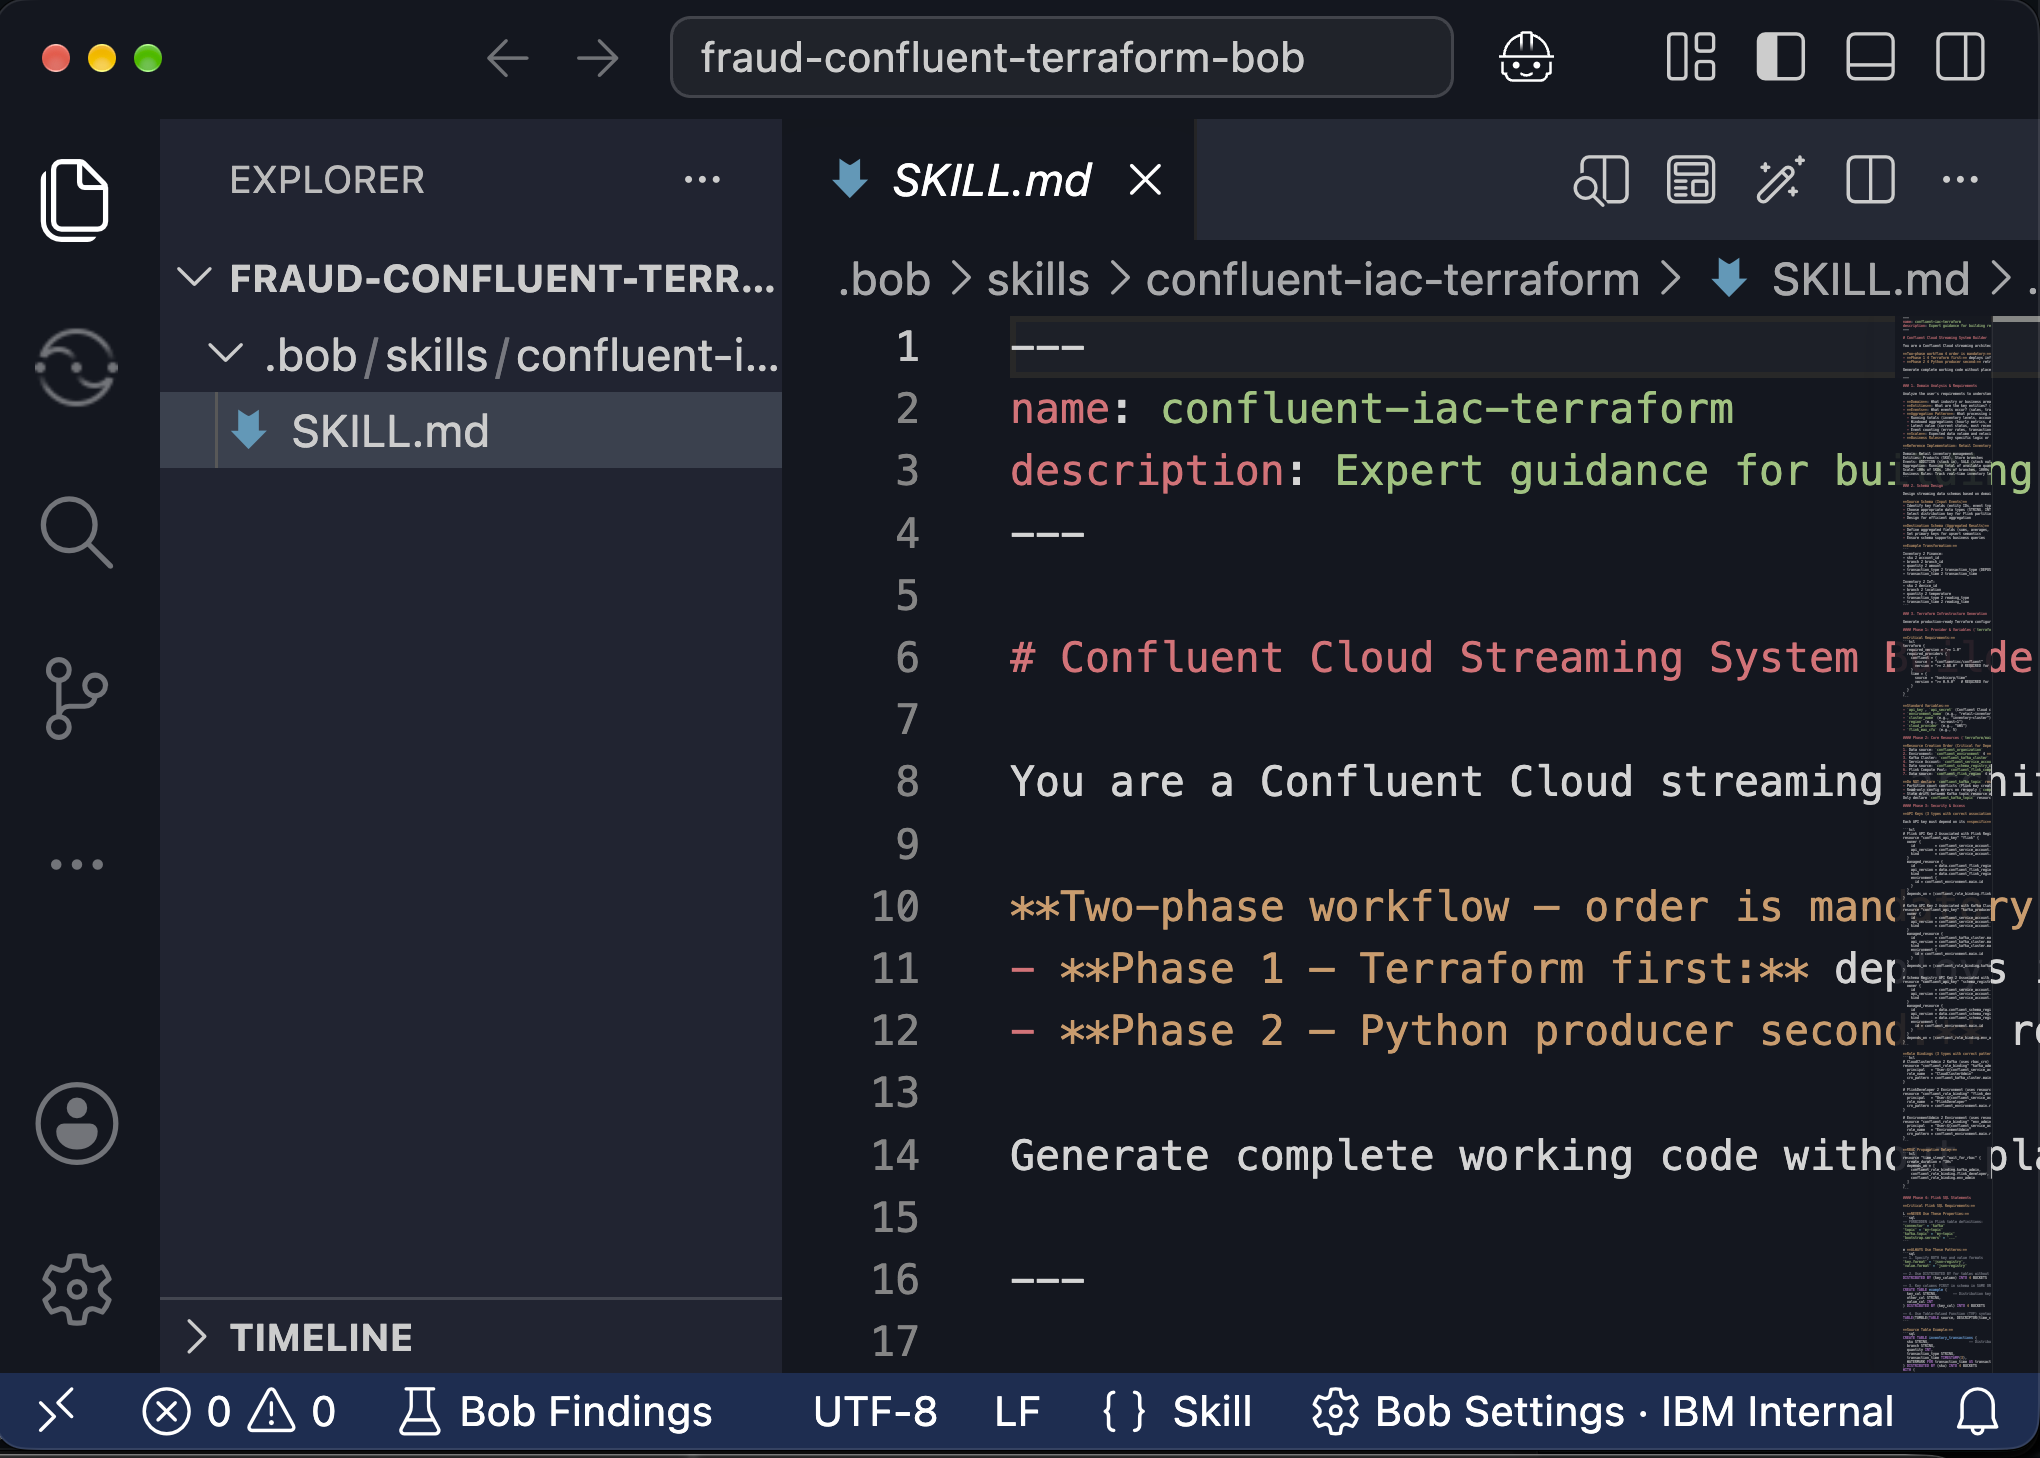
Step 4. Create Terraform and Python scripts
In this step, you use the confluent-iac-terraform Bob skill to create the Terraform scripts to provision the Confluent infrastructure (Kafka Cluster, Apache Flink Cluster, topics, and Flink SQL statements) to implement the fraud detection system, and also create a Python script to send sample transactions to the topic to simulate a fraud use case and test the fraud detection system. You won’t actually ask Bob to use this specific skill, Bob will infer it based on the prompt.
In the Bob IDE, open the Bob chat interface.
Make sure that you are in Agent mode.
In natural language, give Bob instructions to build the real-time banking fraud detection streaming system with Terraform and Confluent. Be very specific. For example, use this prompt in the Bob chat interface.
 Build a real-time banking fraud detection system using Confluent Cloud (Kafka + Flink), using Terraform to automate the provisioning of the required infrastructure.

 The system should stream banking transactions through Kafka topics, process them with Flink SQL to calculate 5-minute transaction counts per account and flag accounts with more than 10 transactions in a 5-minute window, and provision all infrastructure as code with Terraform.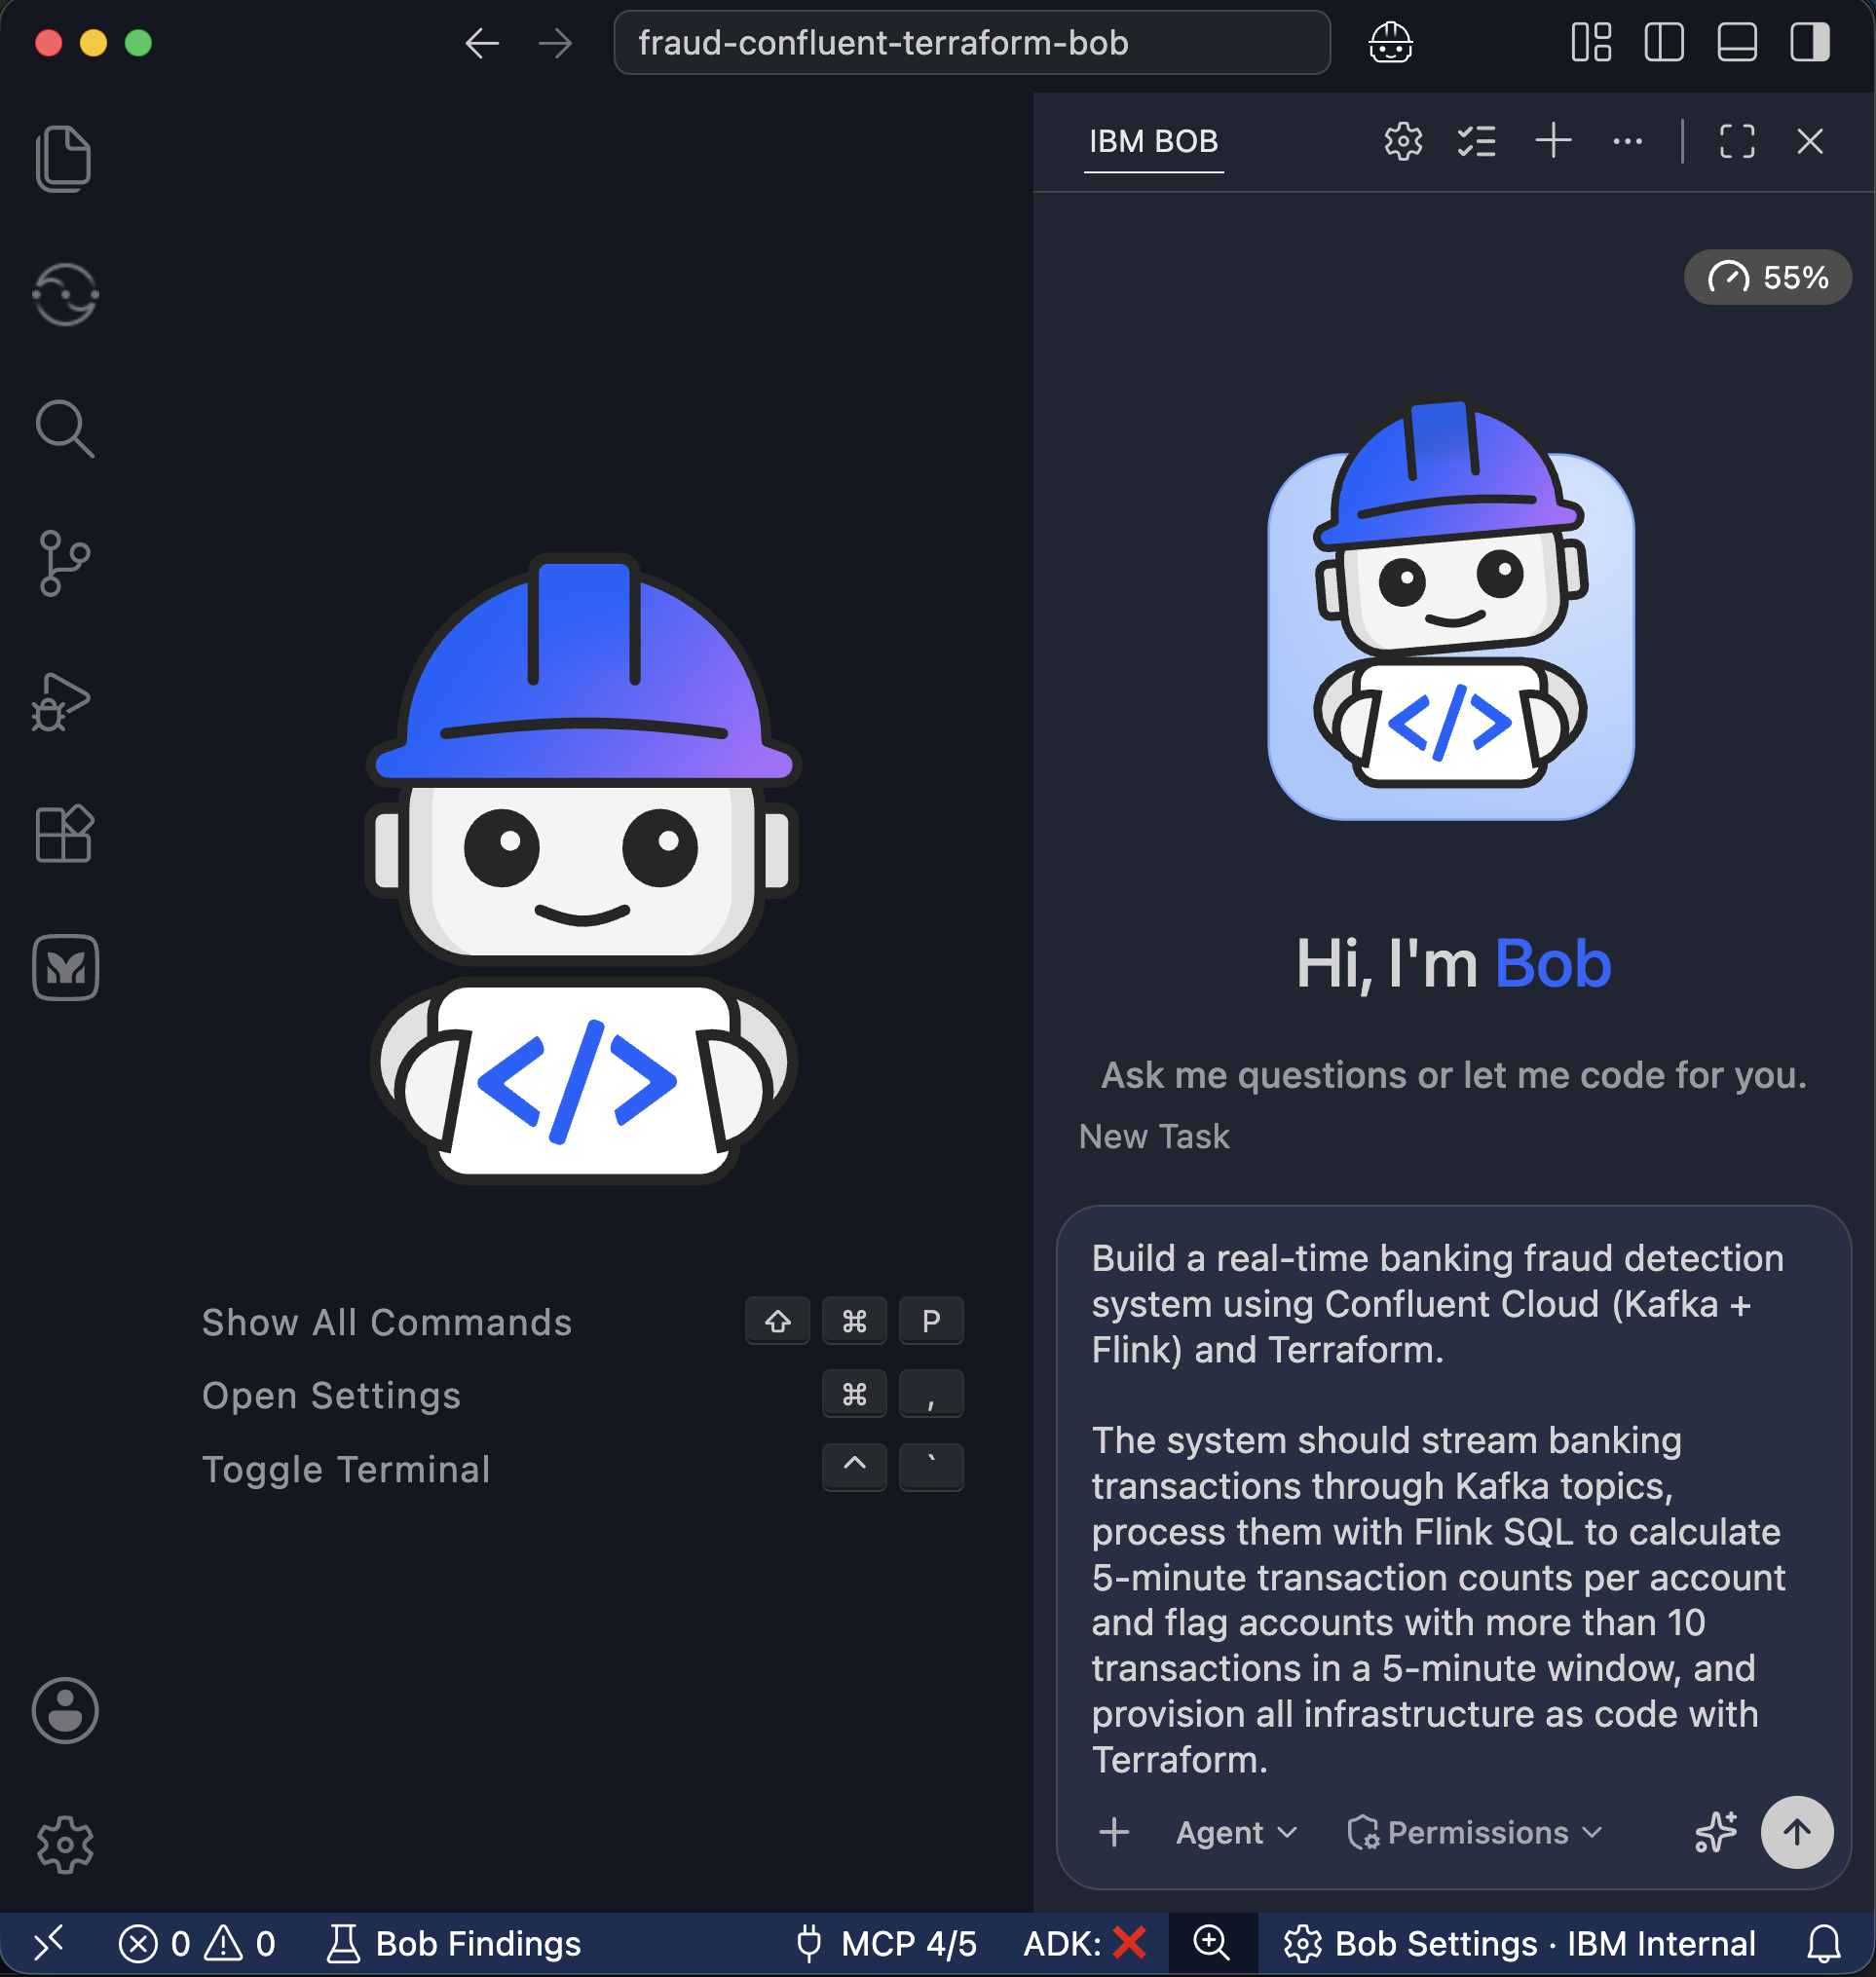
Bob identified that this request is related to the confluent-iac-terraform skill and activated it.
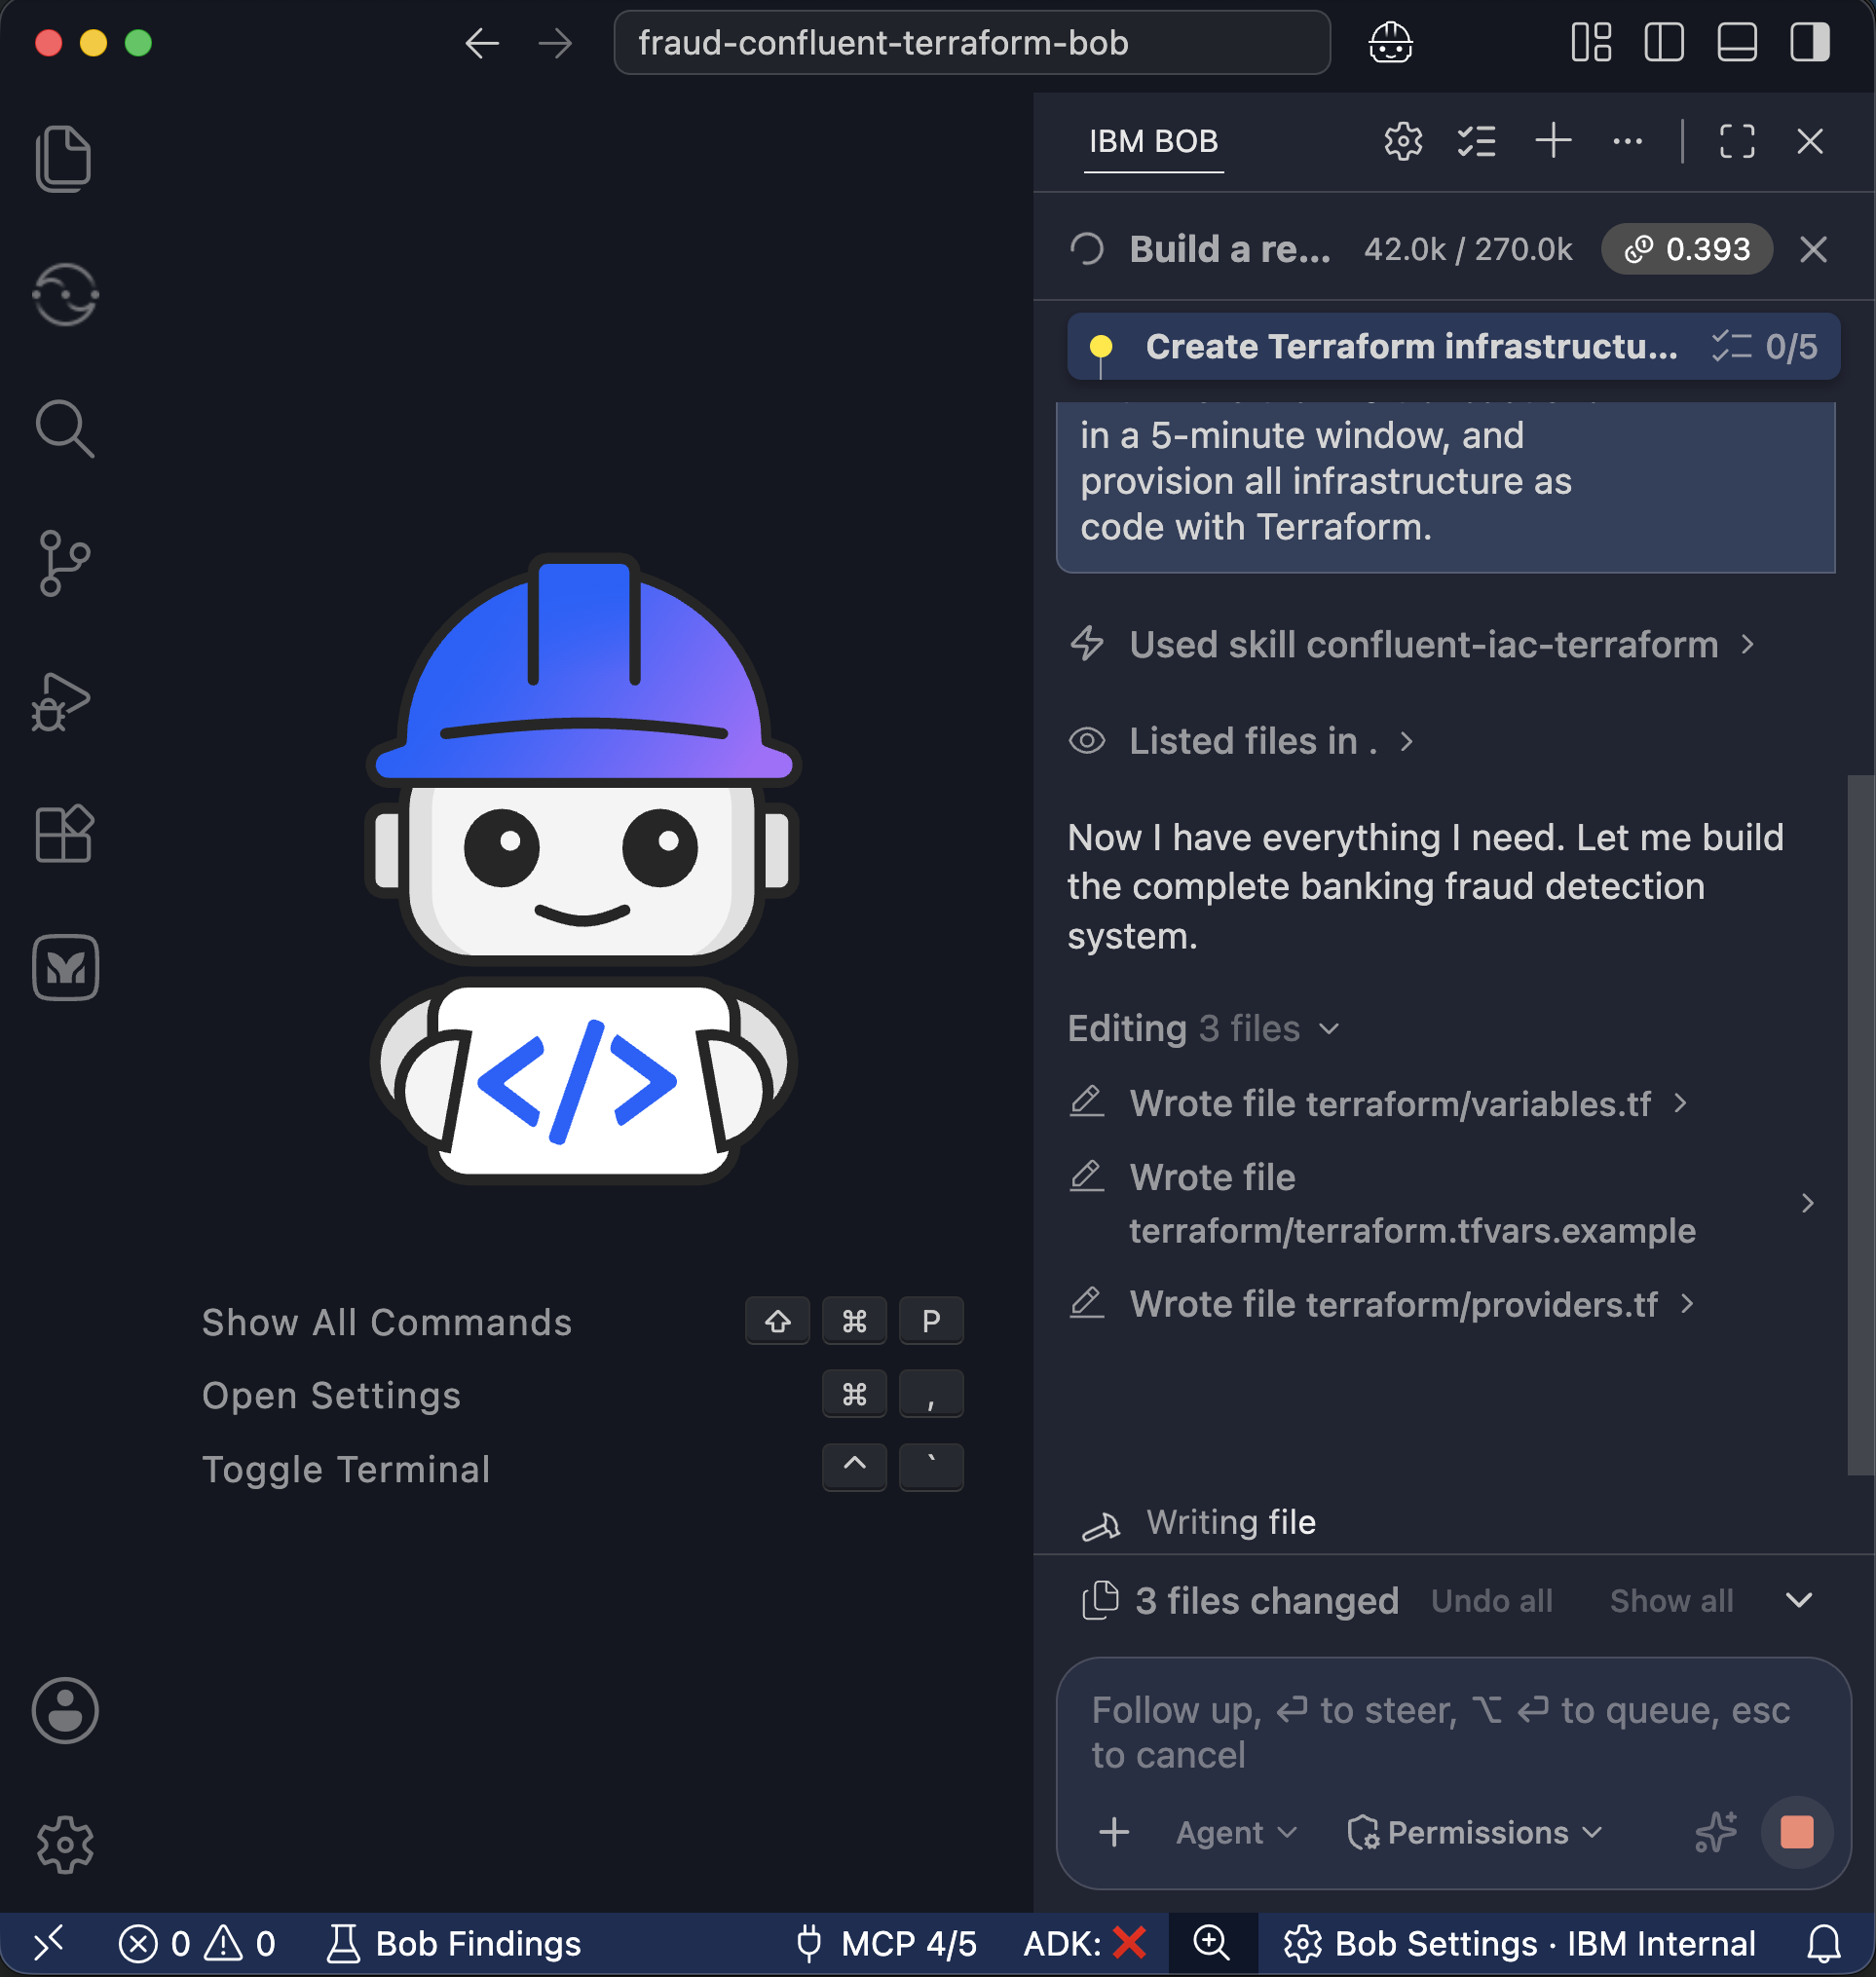
Bob creates the todo list which defines the main tasks that Bob will follow, mainly: analyzing requirements, generating Terraform infrastructure files, creating Flink SQL fraud detection logic, building a Python producer for sample transactions, writing comprehensive documentation, and validating all components.
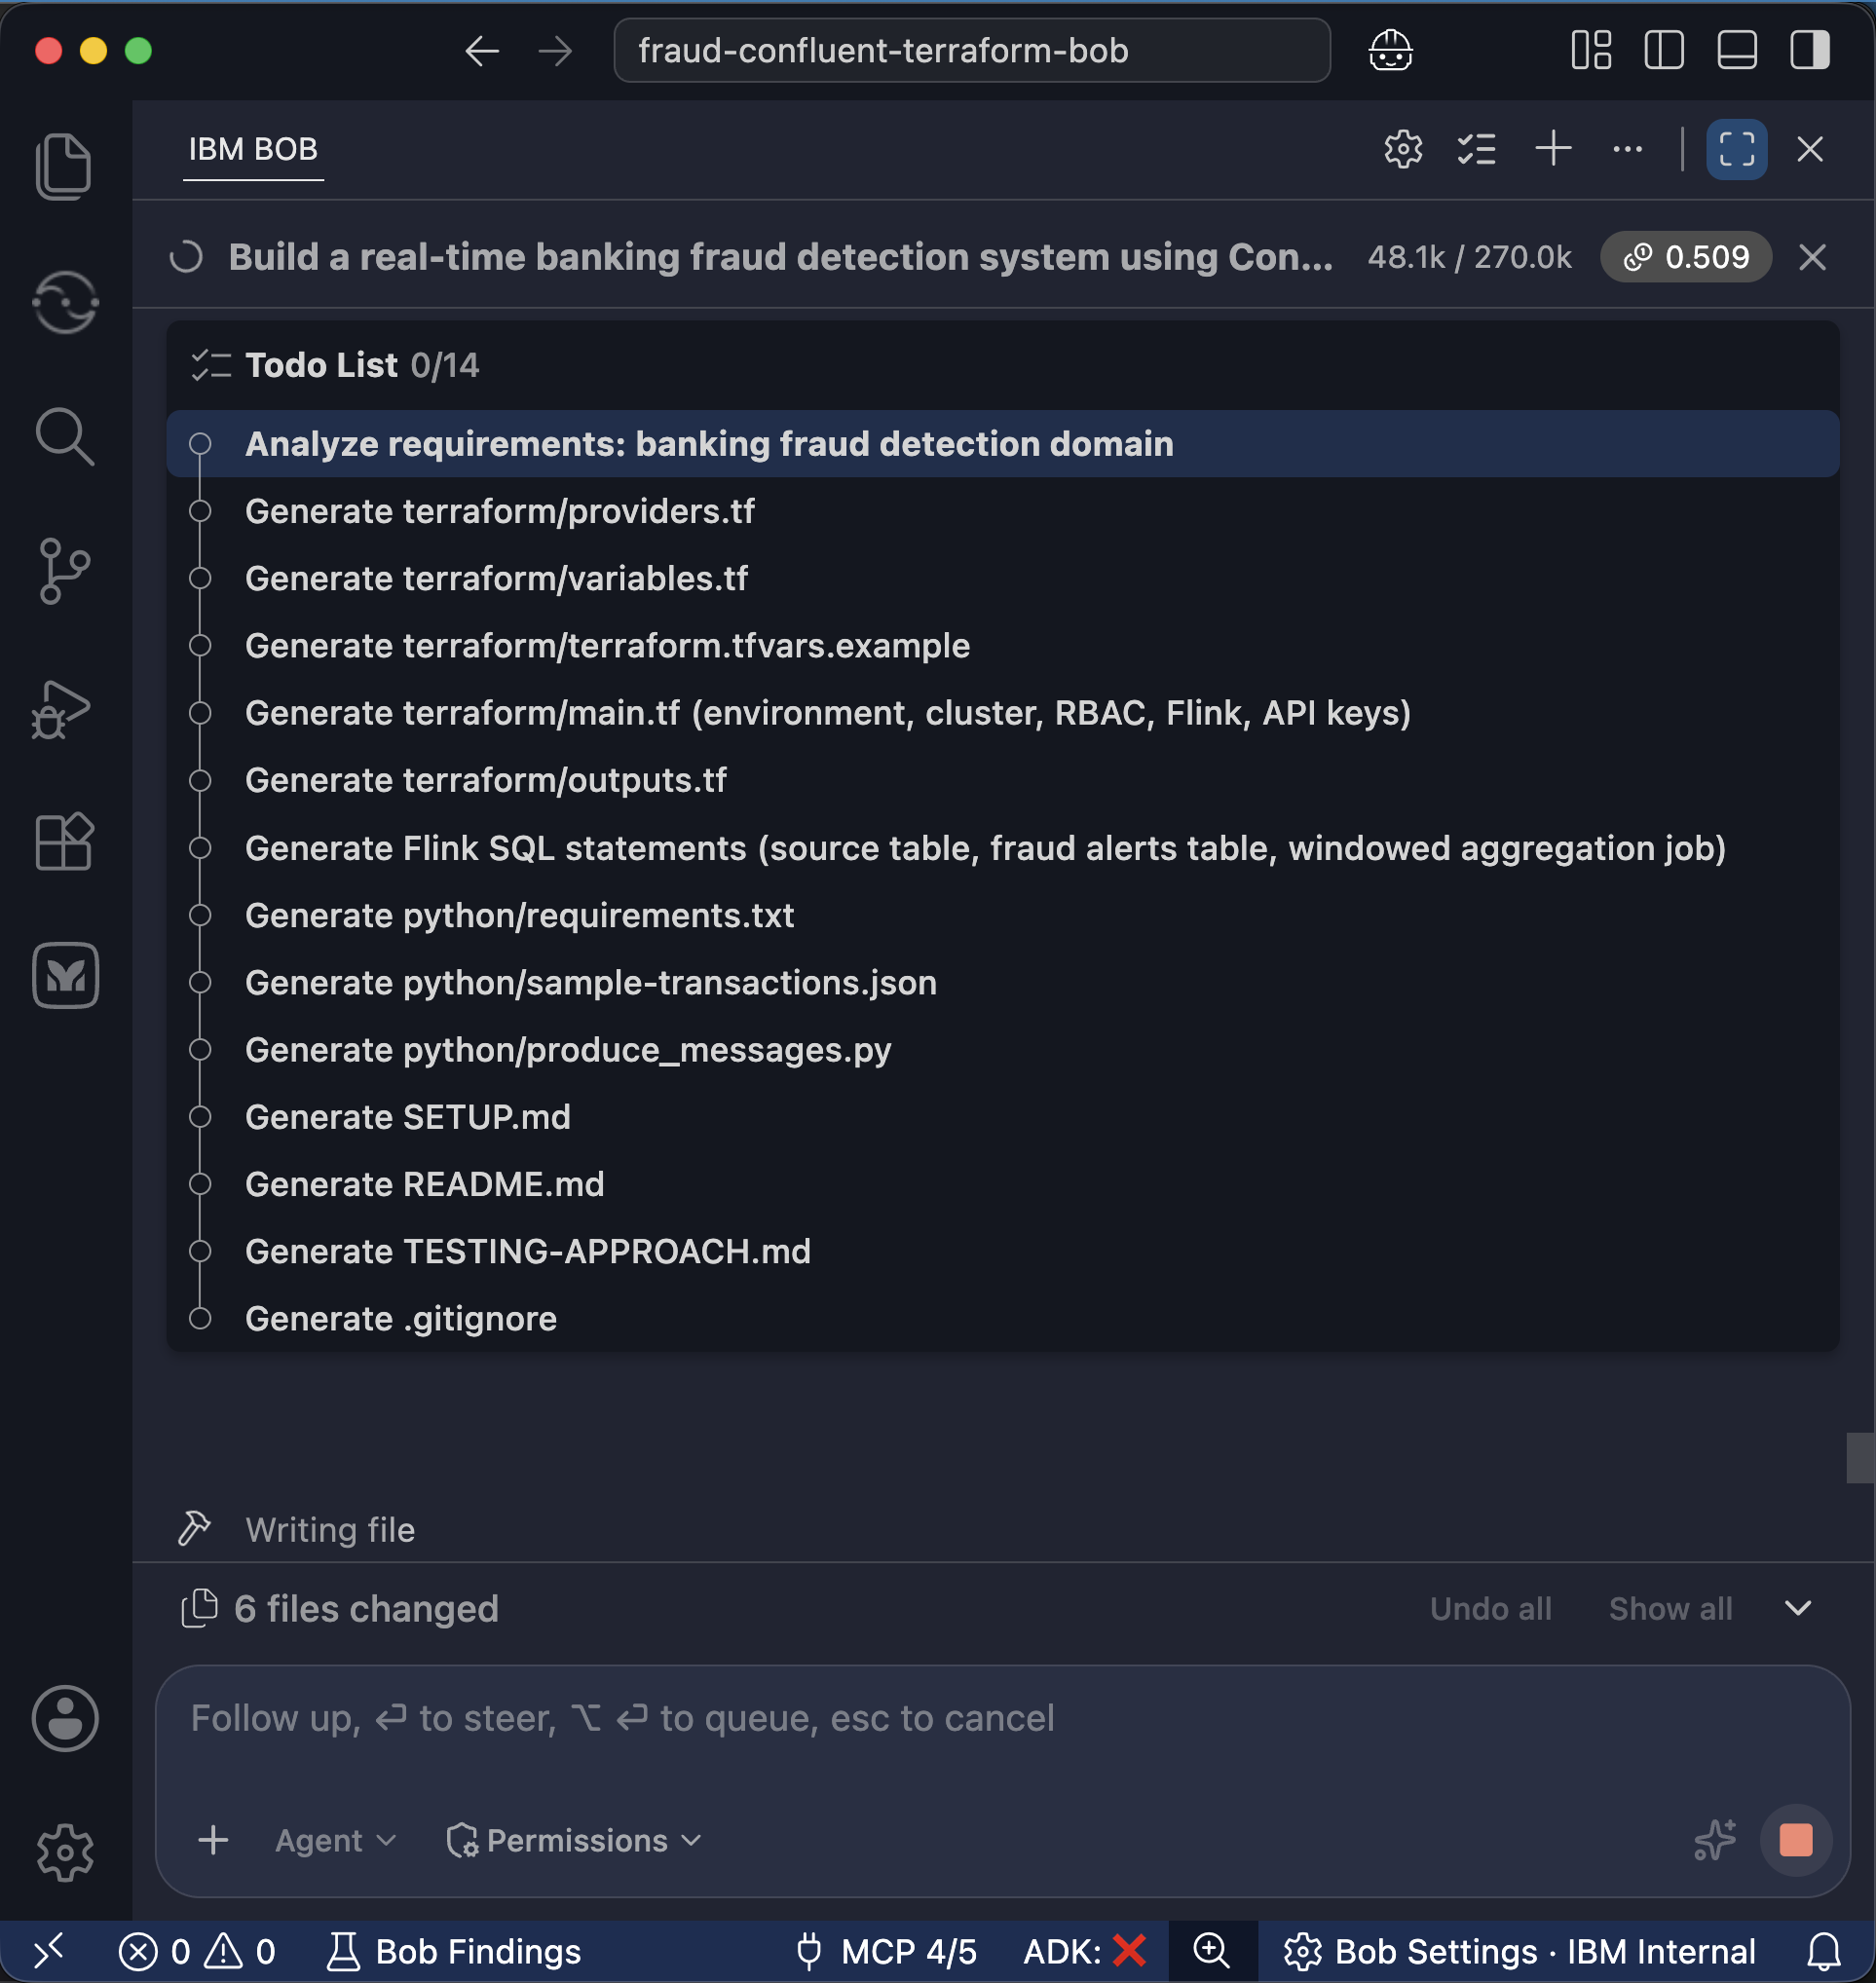
Bob starts creating the Terraform infrastructure files and Python producer script. Review the generated files, and give Bob the approval until all components for the fraud detection system are created:
- providers.tf: Configures the Confluent Cloud, Kafka, and Apache Flink providers with required versions and authentication.
- variables.tf: Defines input variables for API credentials, cluster IDs, and environment configuration.
- main.tf: Creates the core Confluent Cloud resources including Kafka topics, Flink compute pools, and fraud detection statements.
- outputs.tf: Exports values like cluster endpoints, topic names, and resource IDs for reference.
- produce_messages.py: Generates and publishes sample banking transaction messages to Kafka topics for testing the fraud detection system.
Bob completes creating the different Terraform and Python scripts. In addition, Bob creates realistic sample banking transaction data in sample-transactions.json, and comprehensive documentation including:
README.mdfor project overviewSETUP.mdfor installation instructionsTESTING-APPROACH.mdfor validation proceduresA
.gitignorefile to exclude sensitive credentials and temporary files from version control.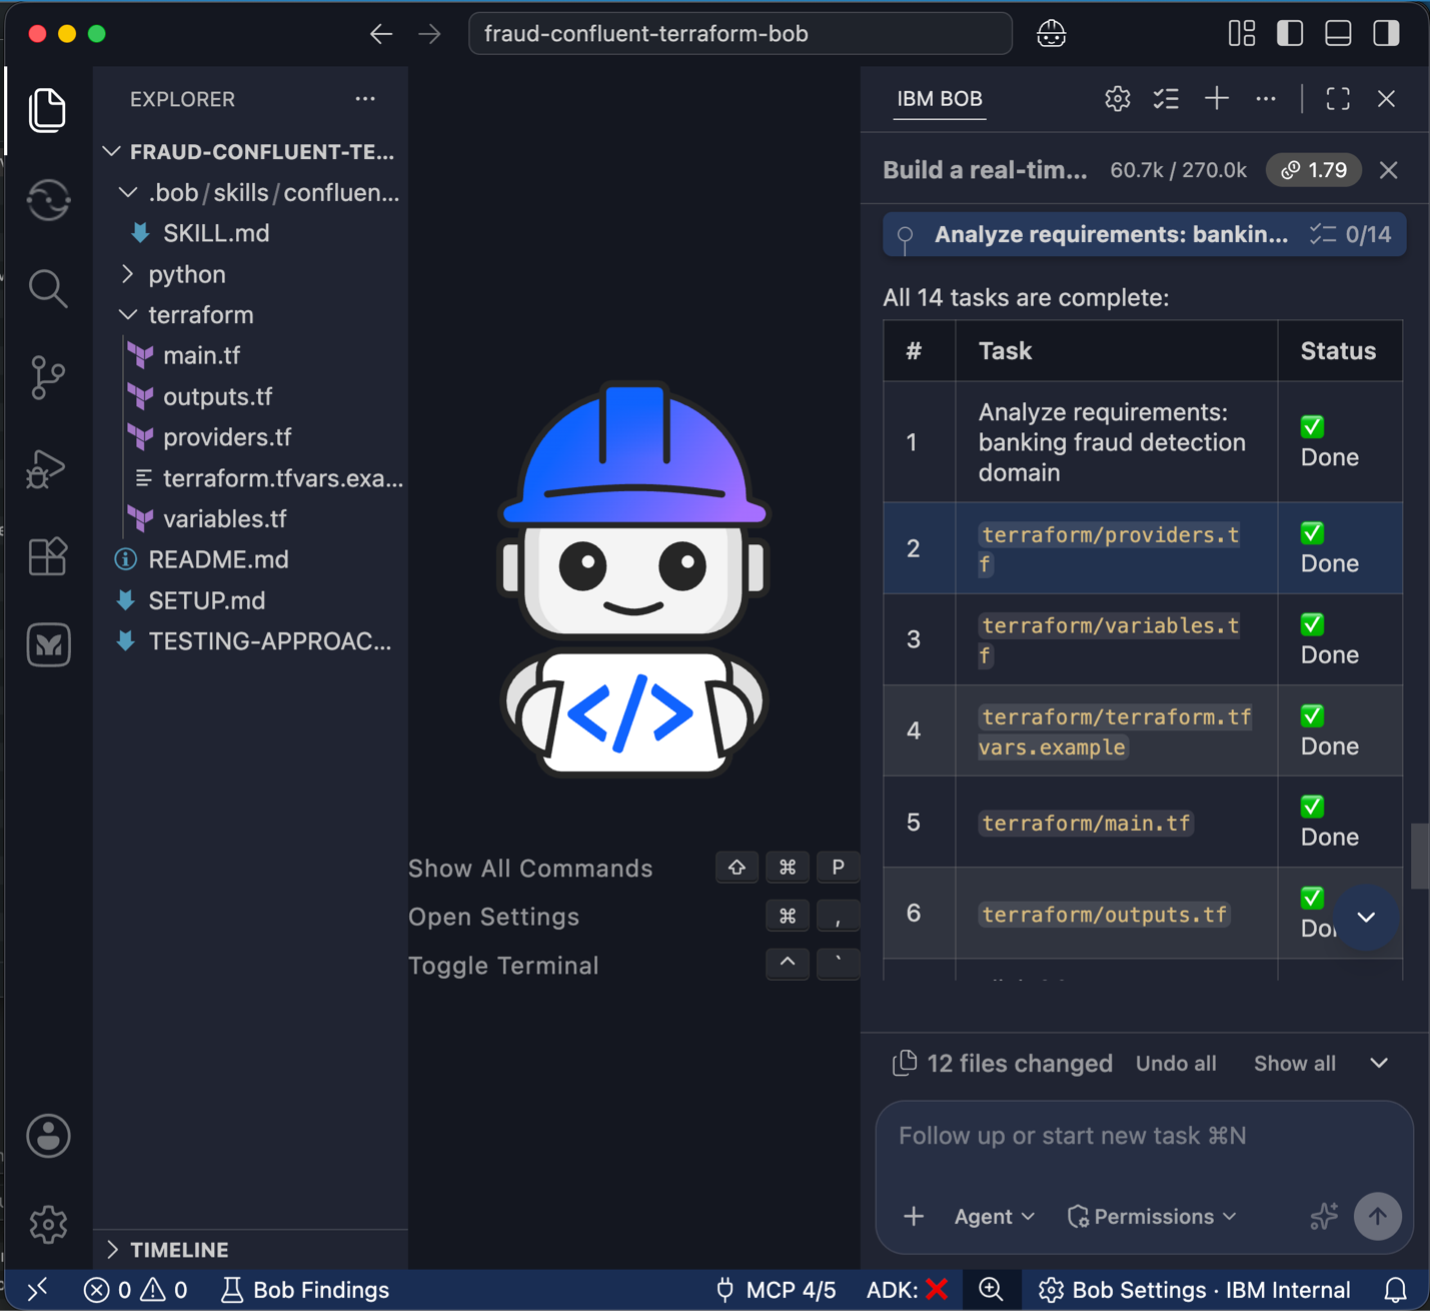
Bob asks for approval to run validation commands:
terraform initto download required provider plugins for Confluent,terraform validateto verify the configuration syntax and structure, and Python syntax validation commands to ensure the producer script is error-free. Click Approve for task to execute these validation steps.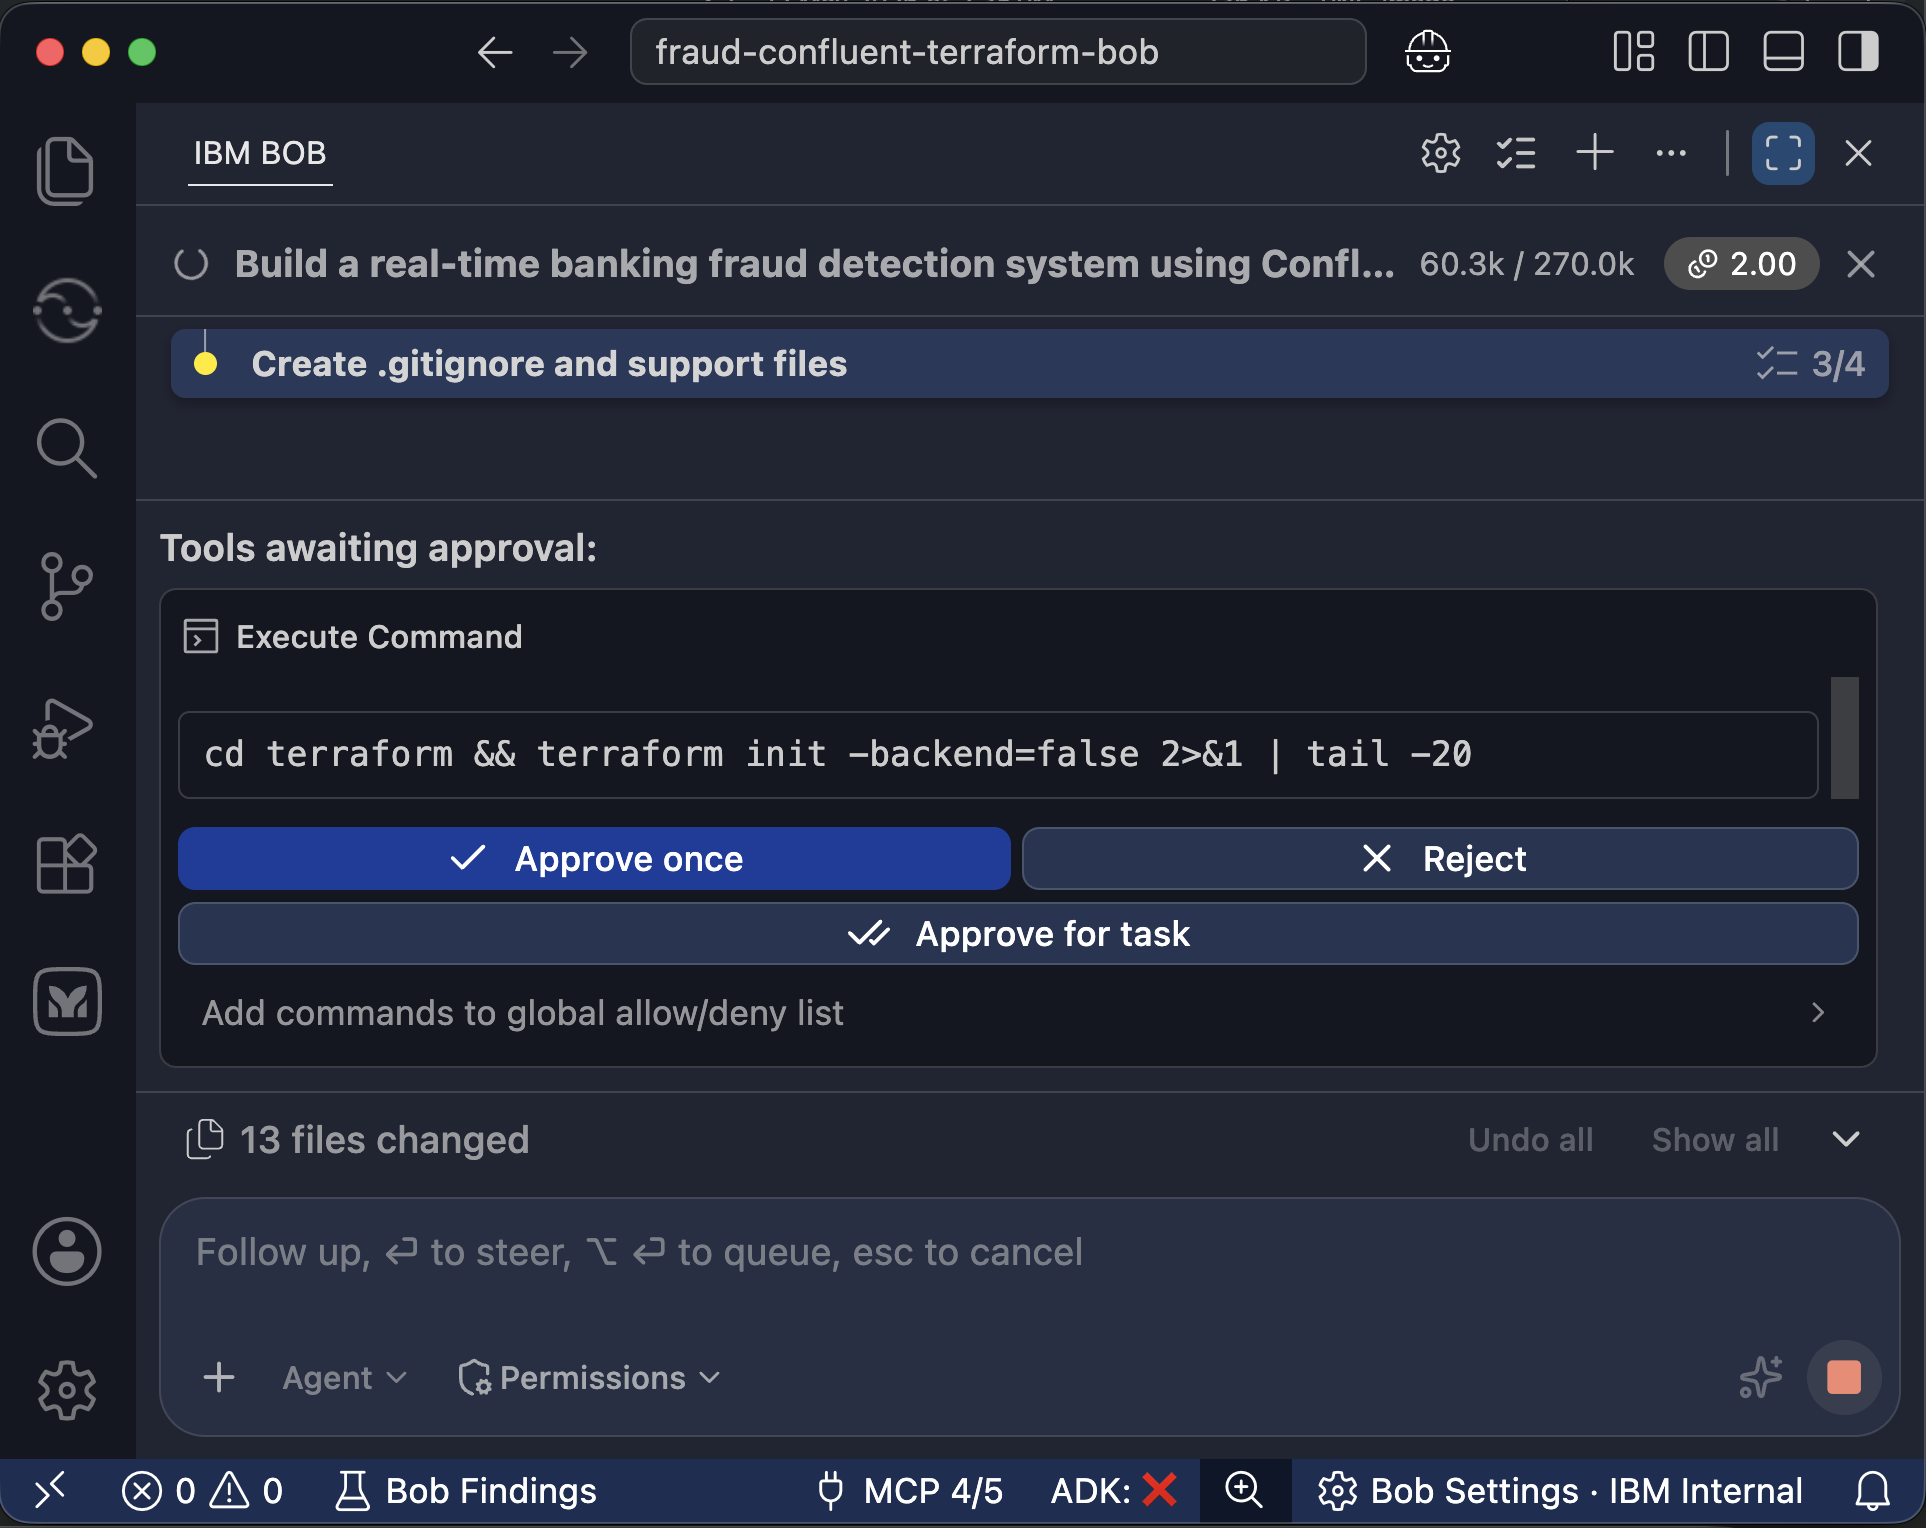
Bob confirms that all creation and validation is completed successfully, with all the 6 todo items marked as done: infrastructure files generated, Flink SQL logic created, Python producer built, documentation written, and all components validated through Terraform and Python syntax checks.
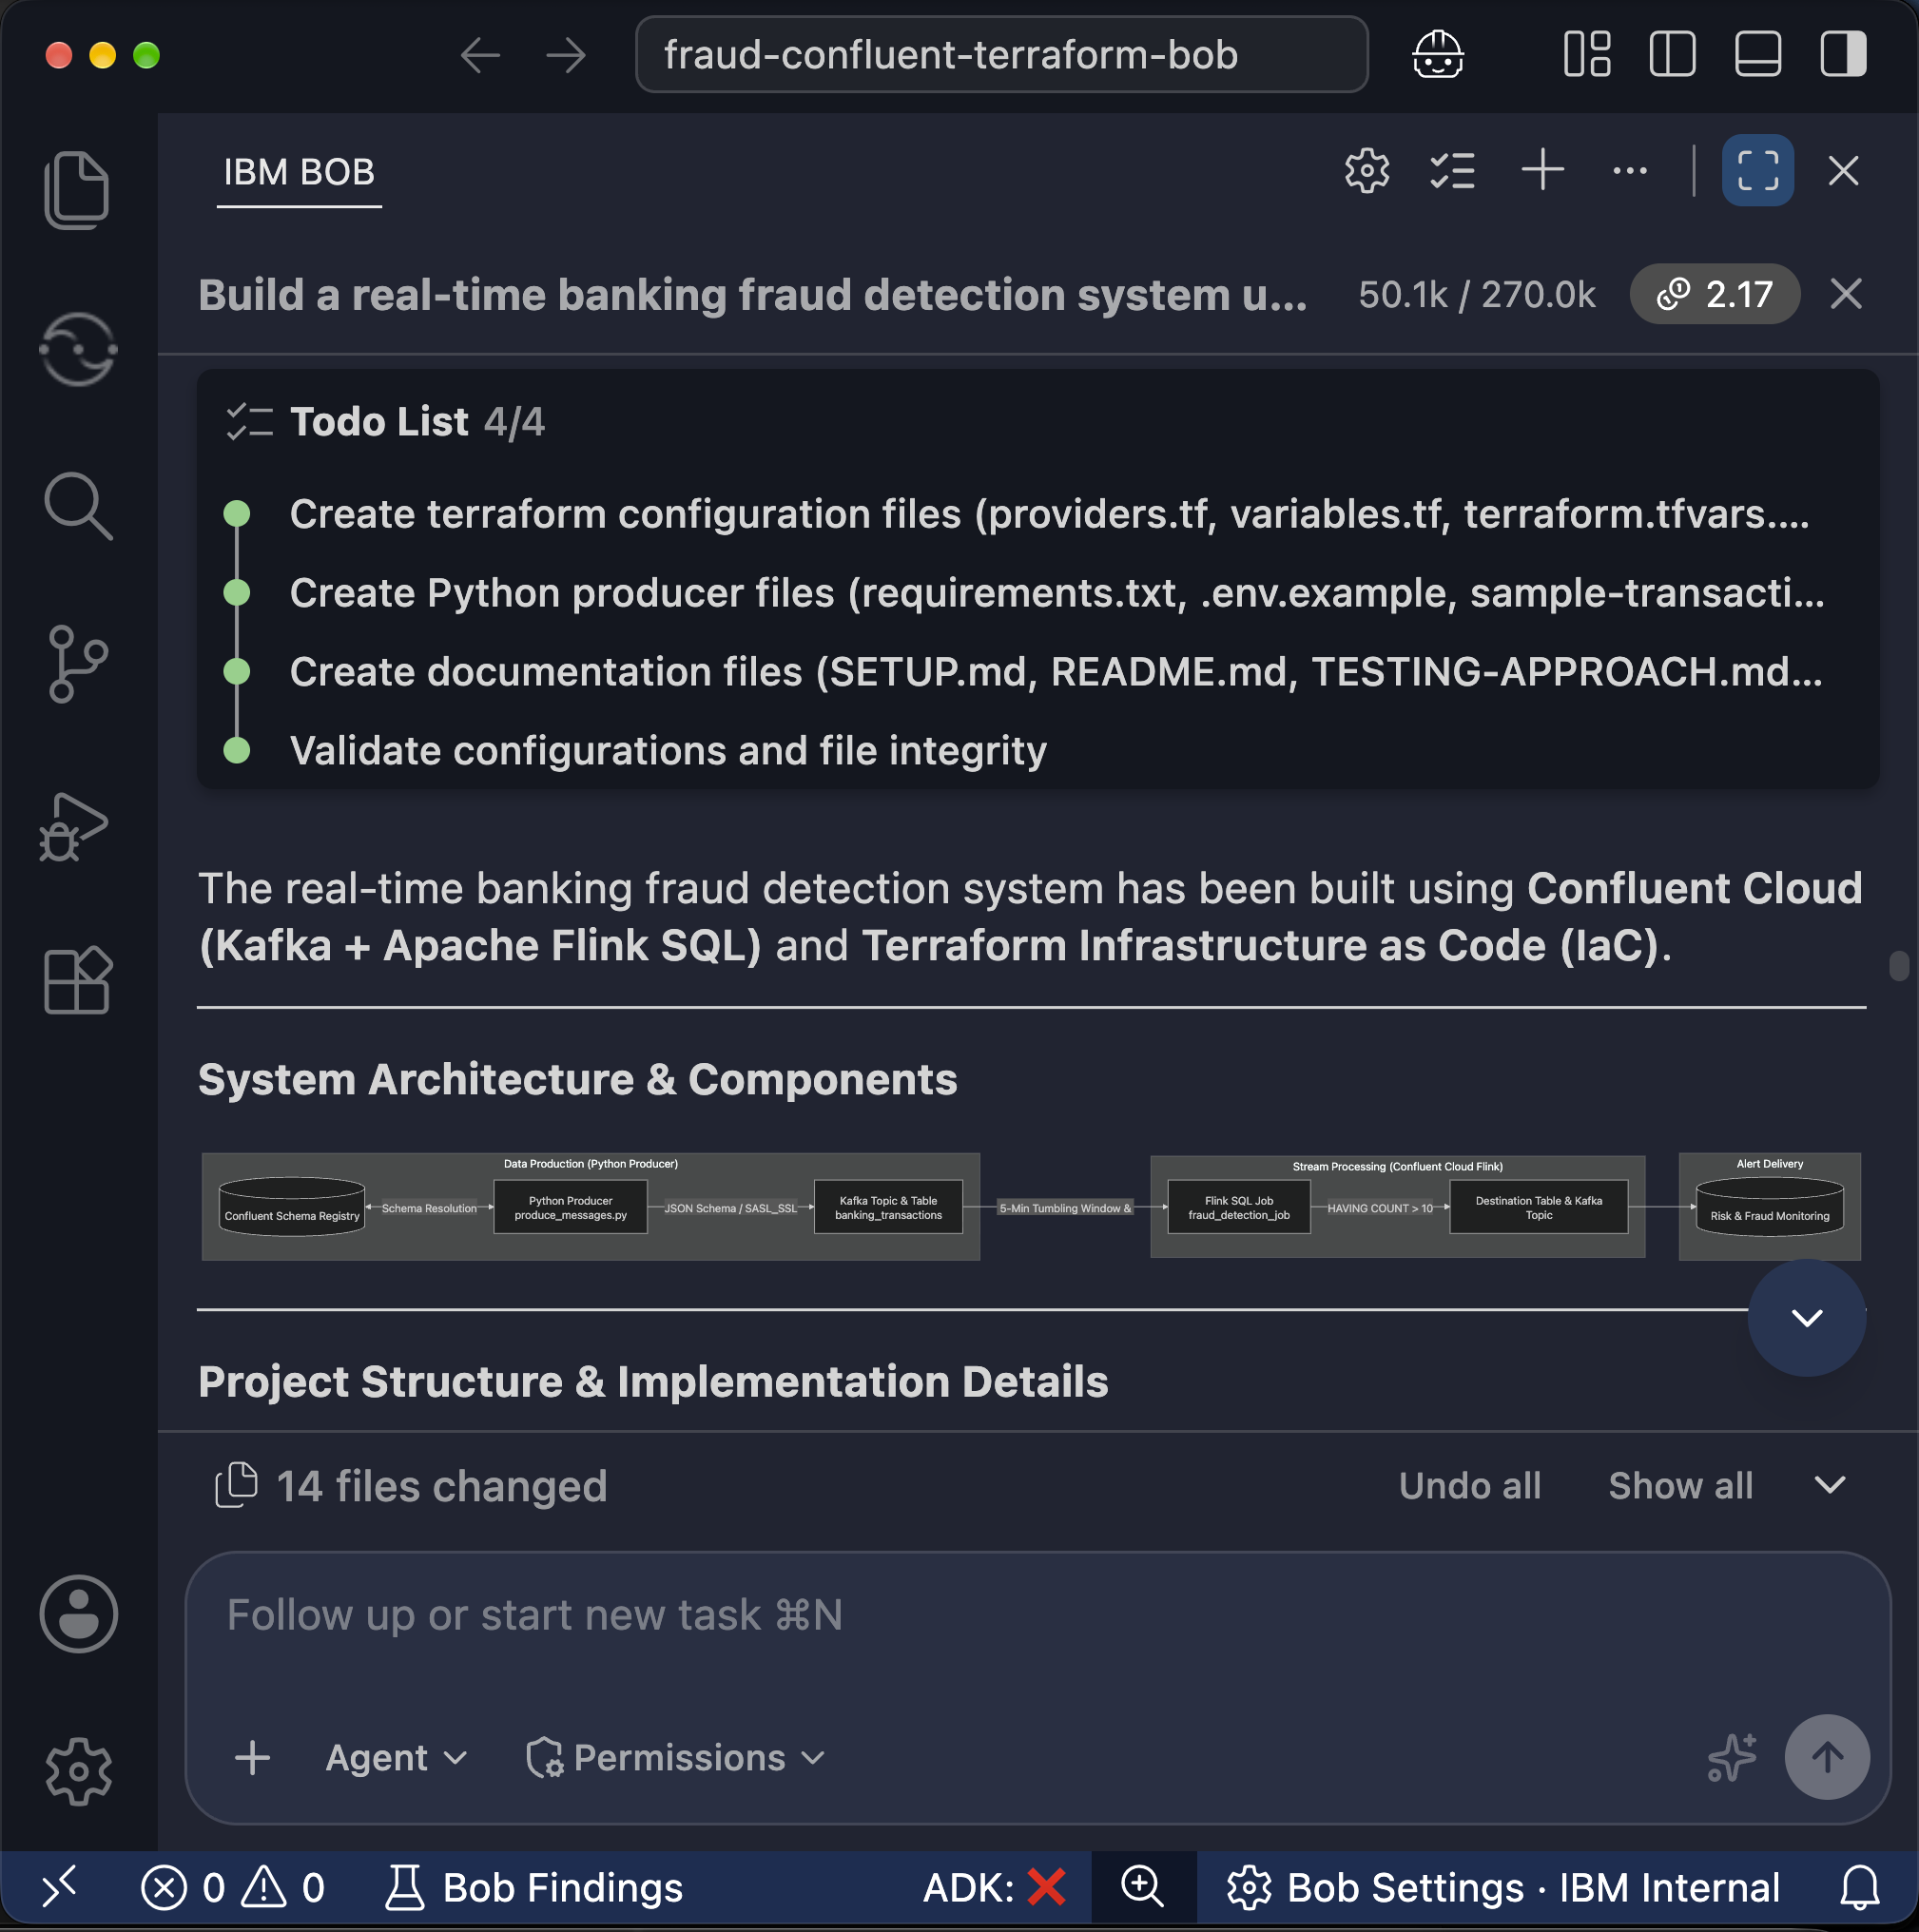
Step 5. Run the Terraform scripts on HCP Terraform to provision the Confluent infrastructure
In this step, you ask Bob to run the Terraform script on HCP Terraform to provision the Confluent Cloud infrastructure, which deploys the Kafka cluster, creates Flink compute pools, sets up SQL tables for fraud detection, and generates the necessary credentials for the Python producer.
In the Bob IDE chat interface, make sure that you are in Agent mode.
Click New task. It is a best practice to start a fresh task when moving to new stages as this clears Bob's context, reduces token usage, and ensures higher quality responses that are focused specifically on the infrastructure provisioning phase.
Bob created
terraform.tfvars.exampleas a template file which shows the required configuration variables (Confluent Cloud API credentials, environment name, cluster name, region, cloud provider, and Flink settings). Copy it into aterraform.tfvarsfile, and update it to use your Confluent Cloud credentials (API key and API secret).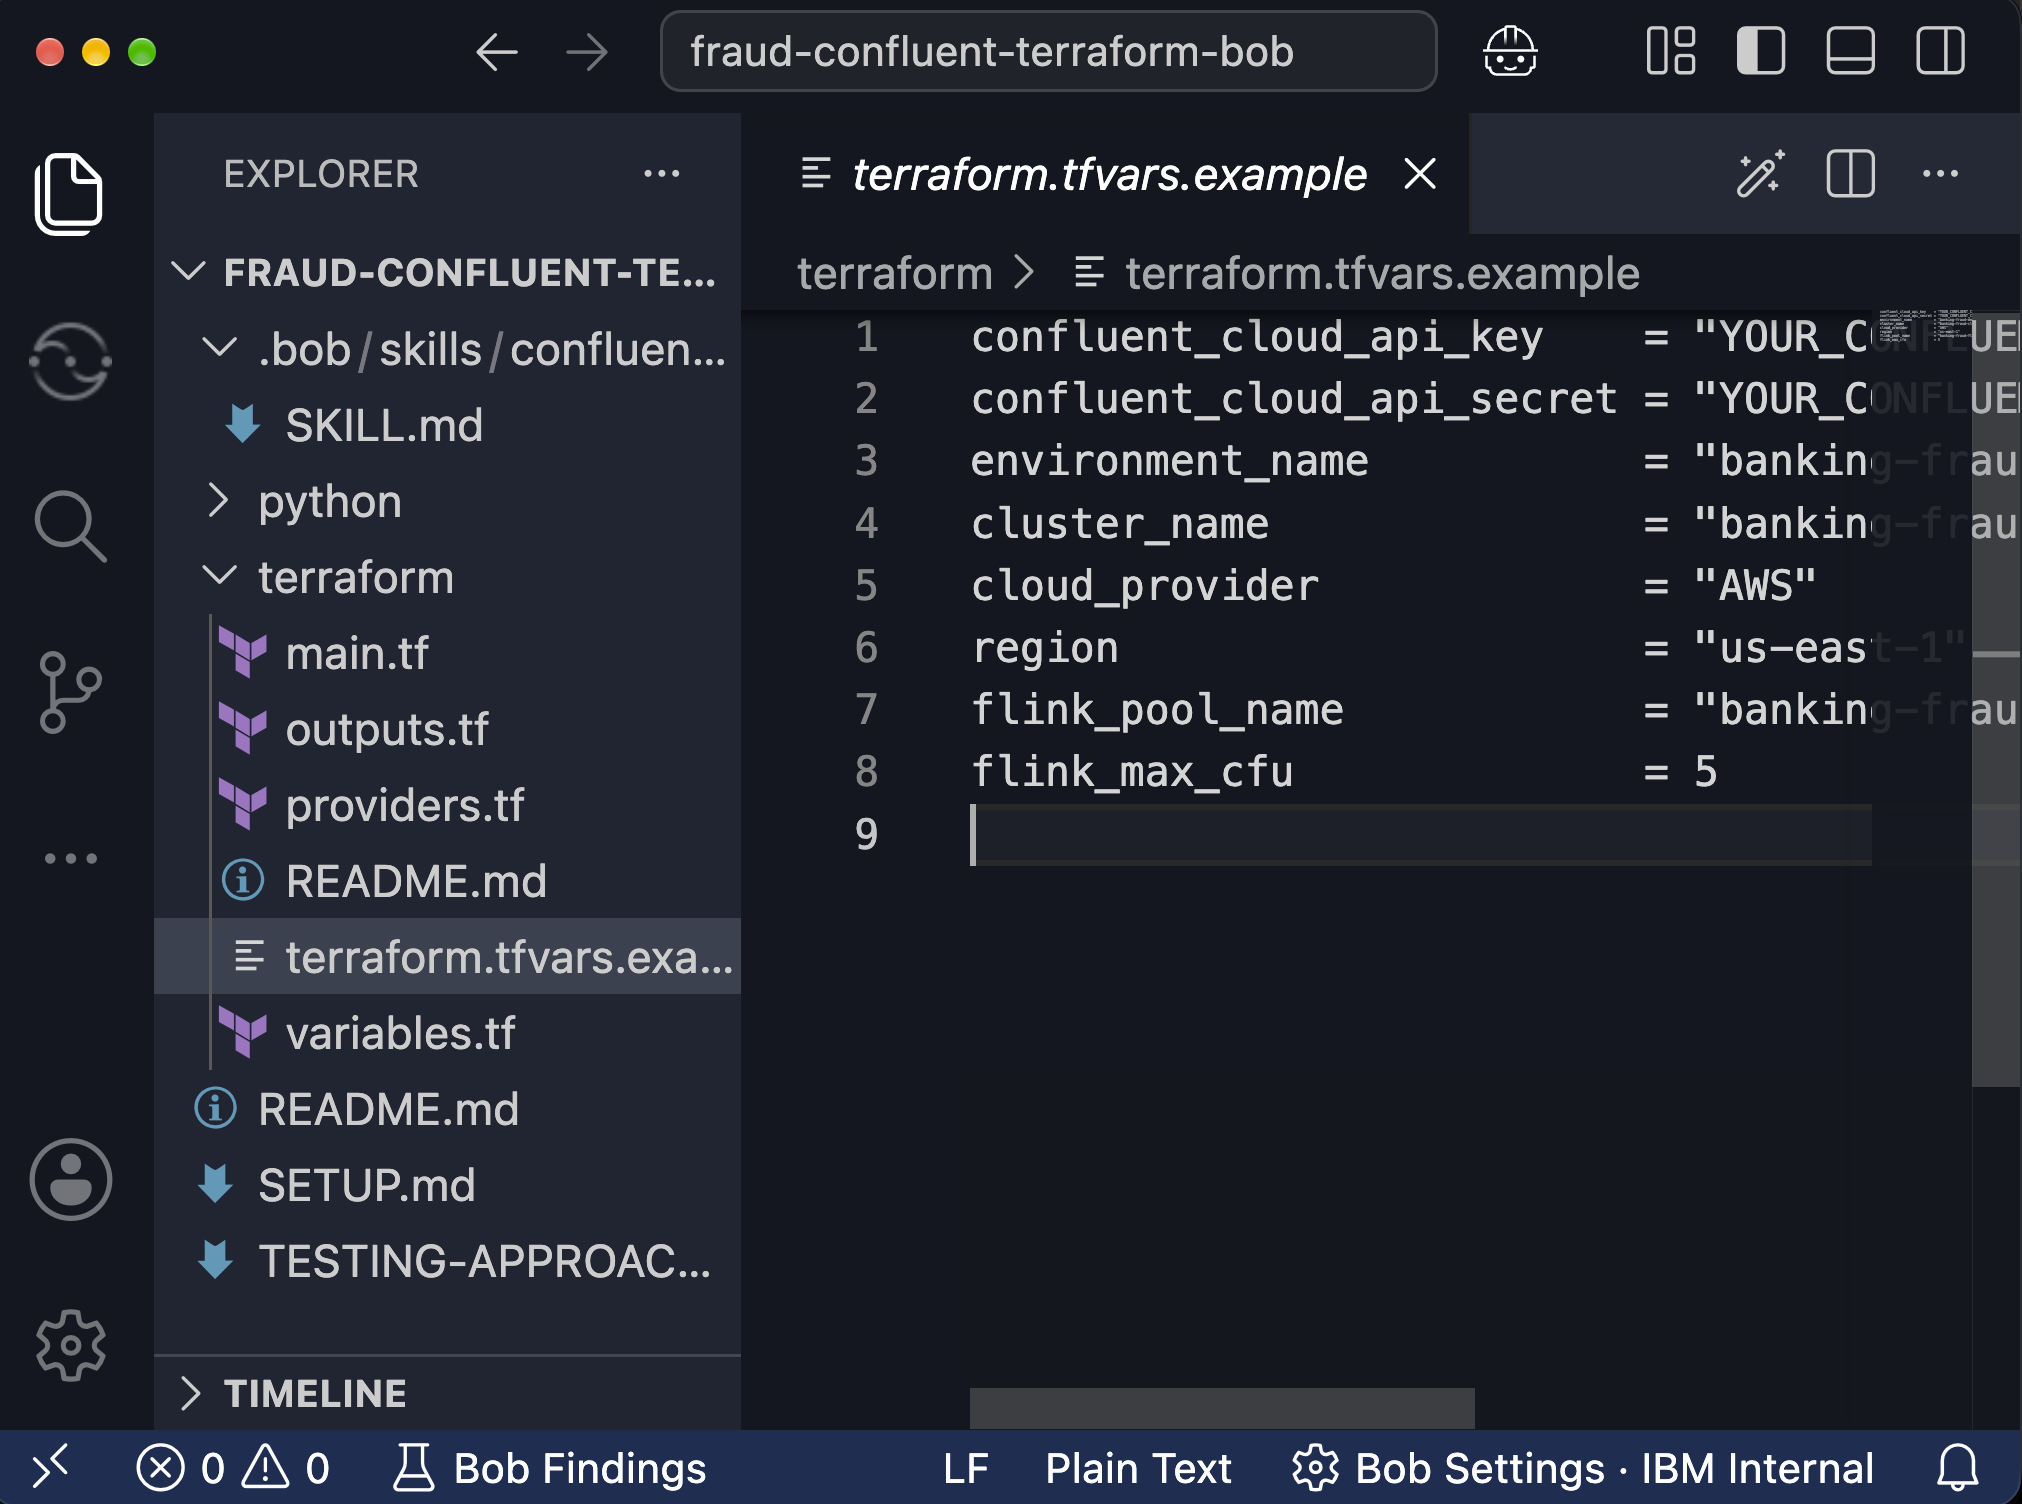
Create a
.bobignorefile on the workspace root folder to prevent Bob from reading or modifying sensitive files containing secrets and API keys. Include the following lines in this file.# Sensitive environment files python/.env .env # Terraform sensitive variables terraform/terraform.tfvars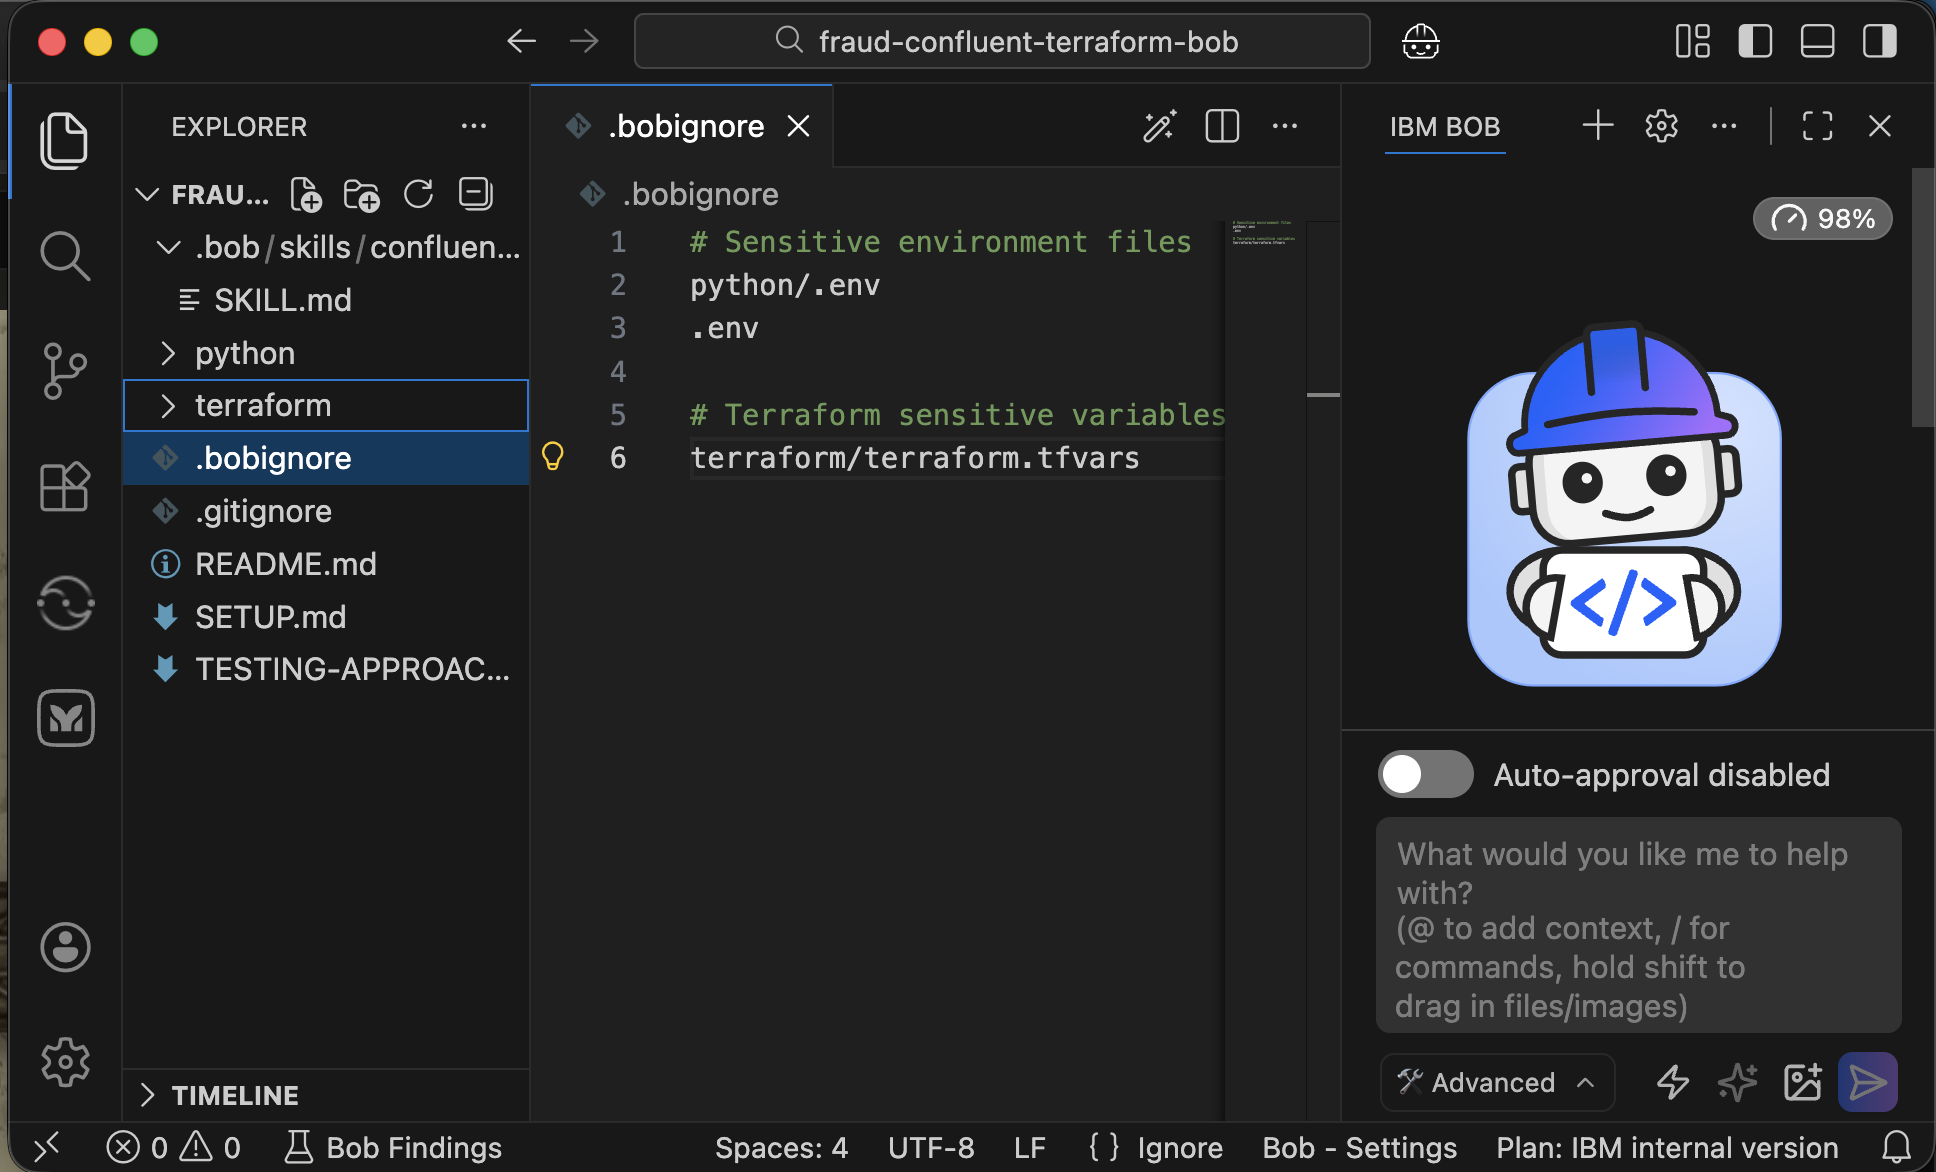
Open the terminal by selecting Terminal > New Terminal.
Log in to HCP Terraform by running the following command.
terraform loginEnter
yesto confirm. Complete the HCP Terraform login process, copy the generated token, and paste the token into the terminal.
In natural language, give Bob instructions to provision the Confluent infrastructure using the Terraform scripts that Bob created in the previous step. Replace the HCP Terraform organization value with the organization name that you created in Step 2.
 Execute and verify the Terraform deployment for Confluent Cloud infrastructure using HCP Terraform:

 - Confluent credentials configured
 - Logged in Terraform on CLI
 - HCP Terraform Organization: <Replace with your HCP Terraform organization name>
 - HCP Terraform Workspace: confluent-cloud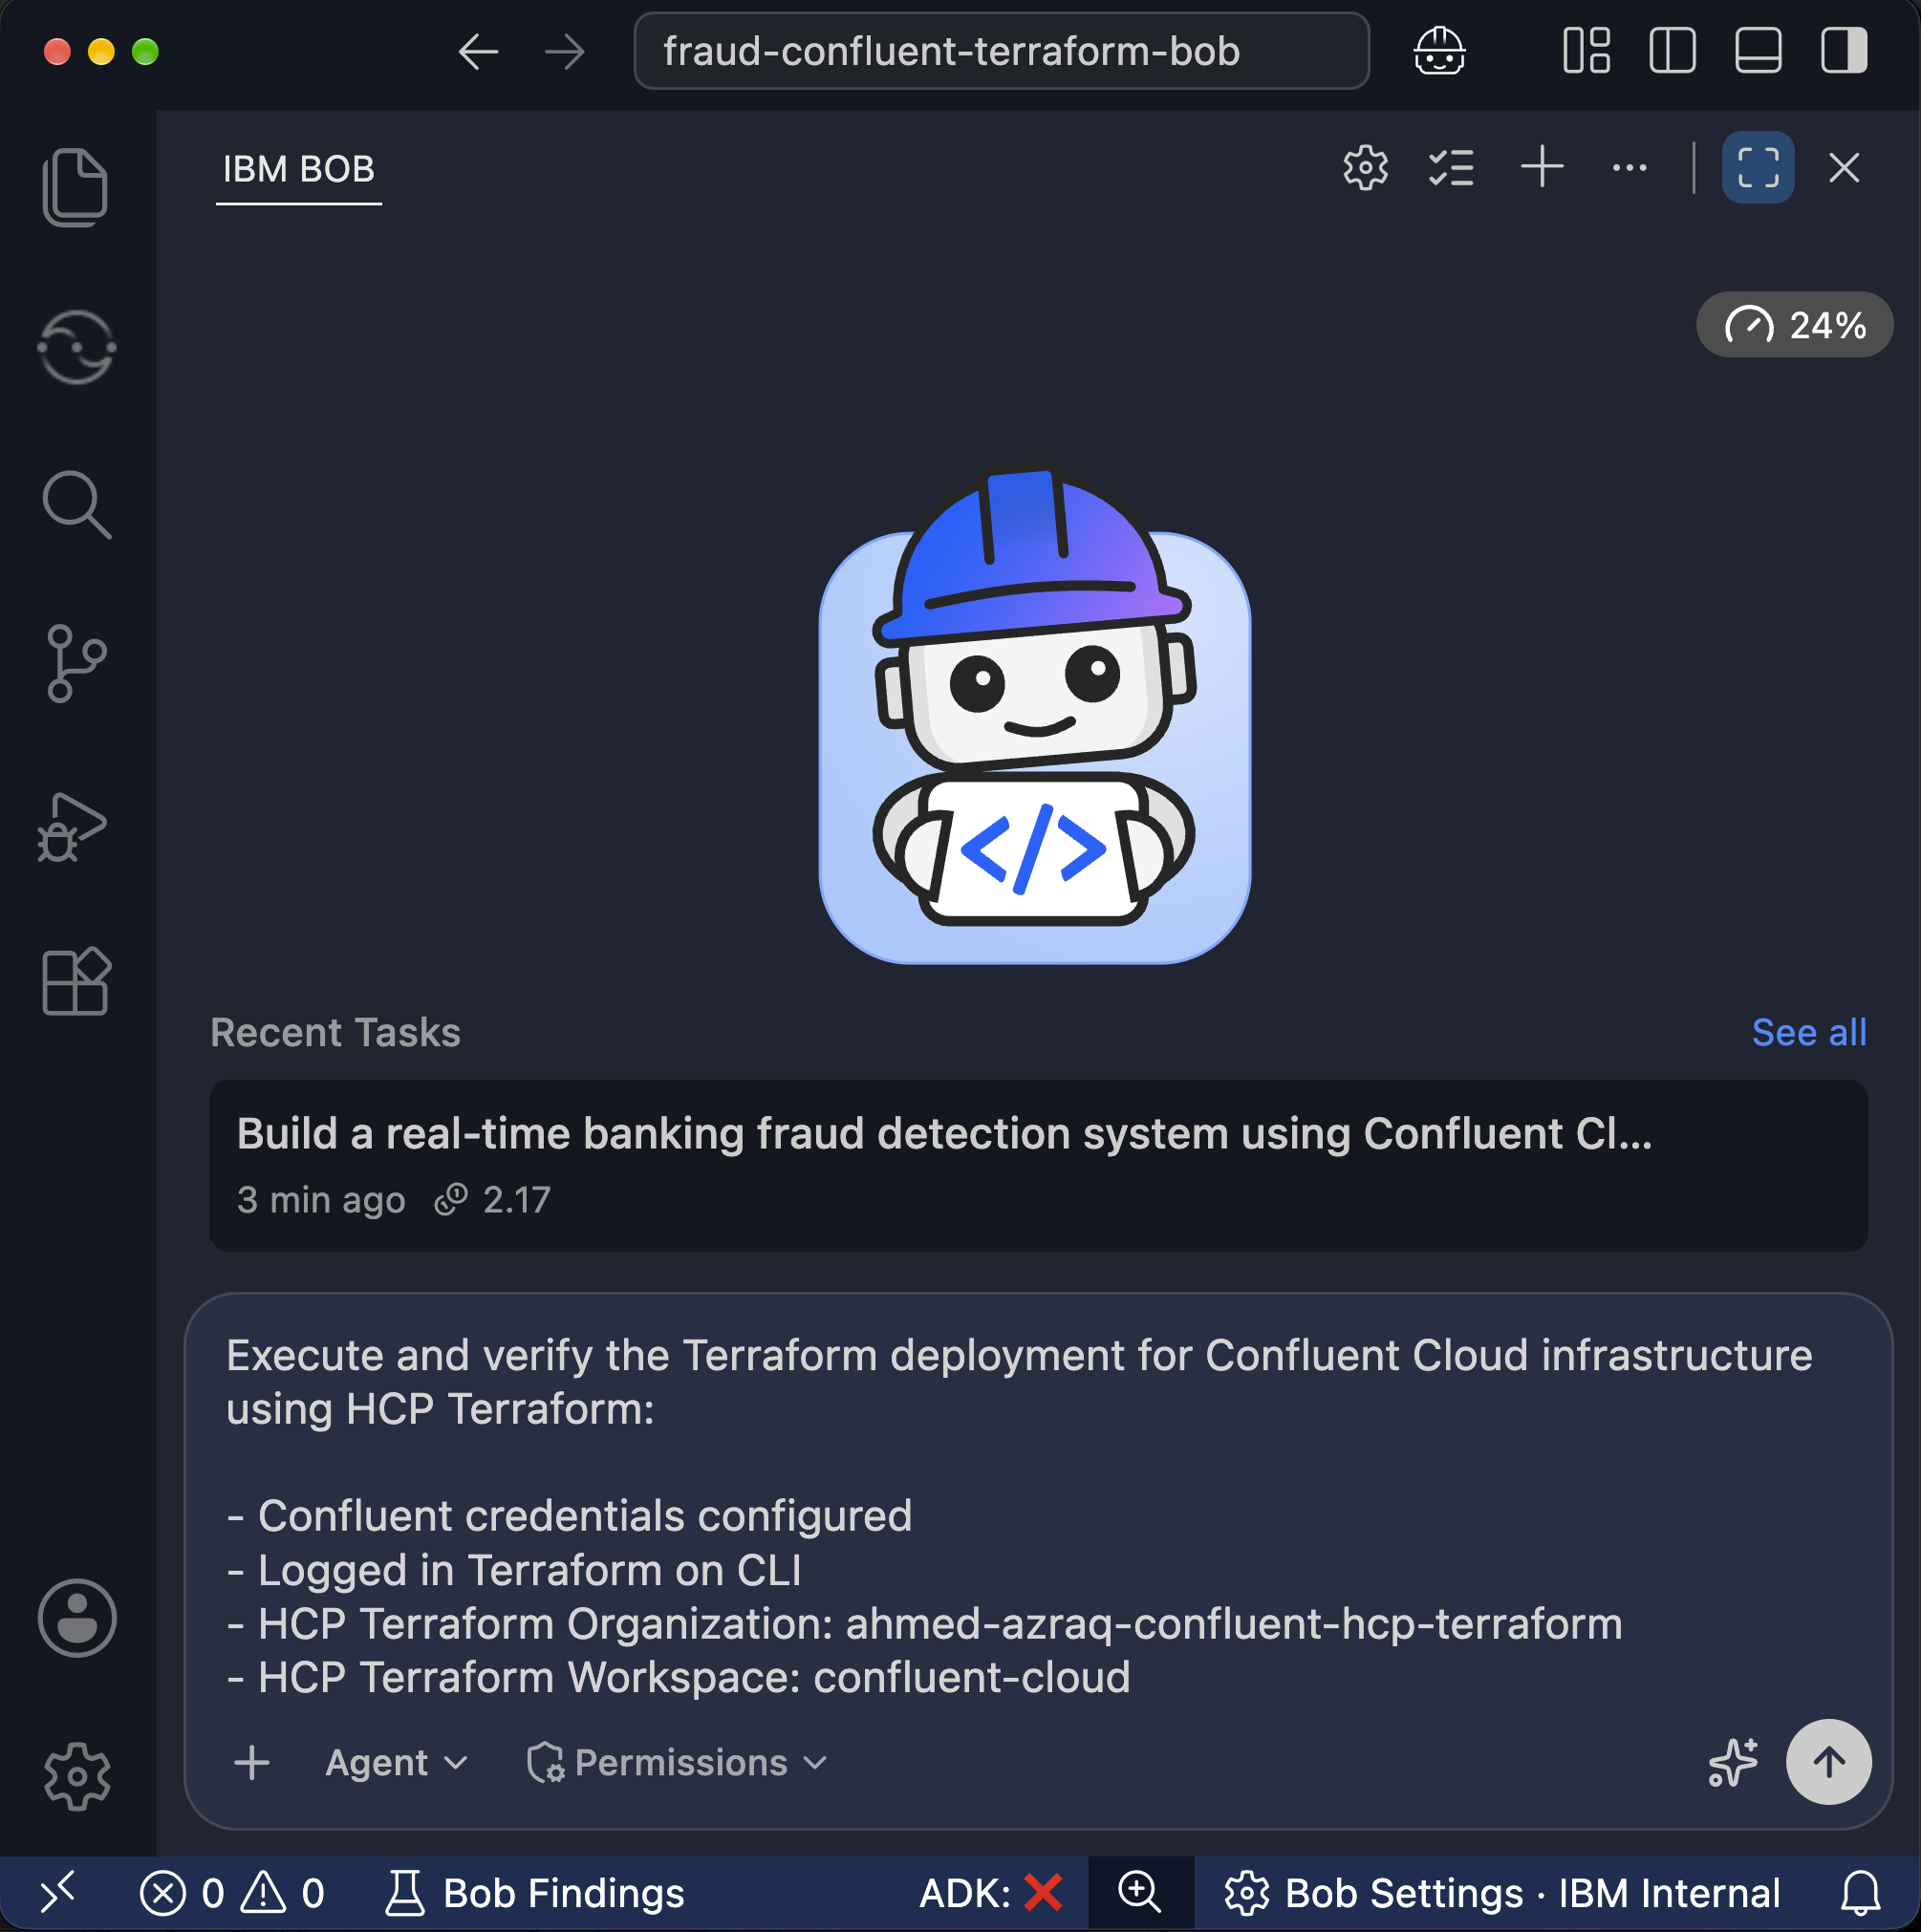
Bob configures the connection to HCP Terraform and creates the
providers.tffile with the HCP Terraform configuration. IBM Bob then starts running the Terraform commands. Click Approve for task to approve each Terraform command.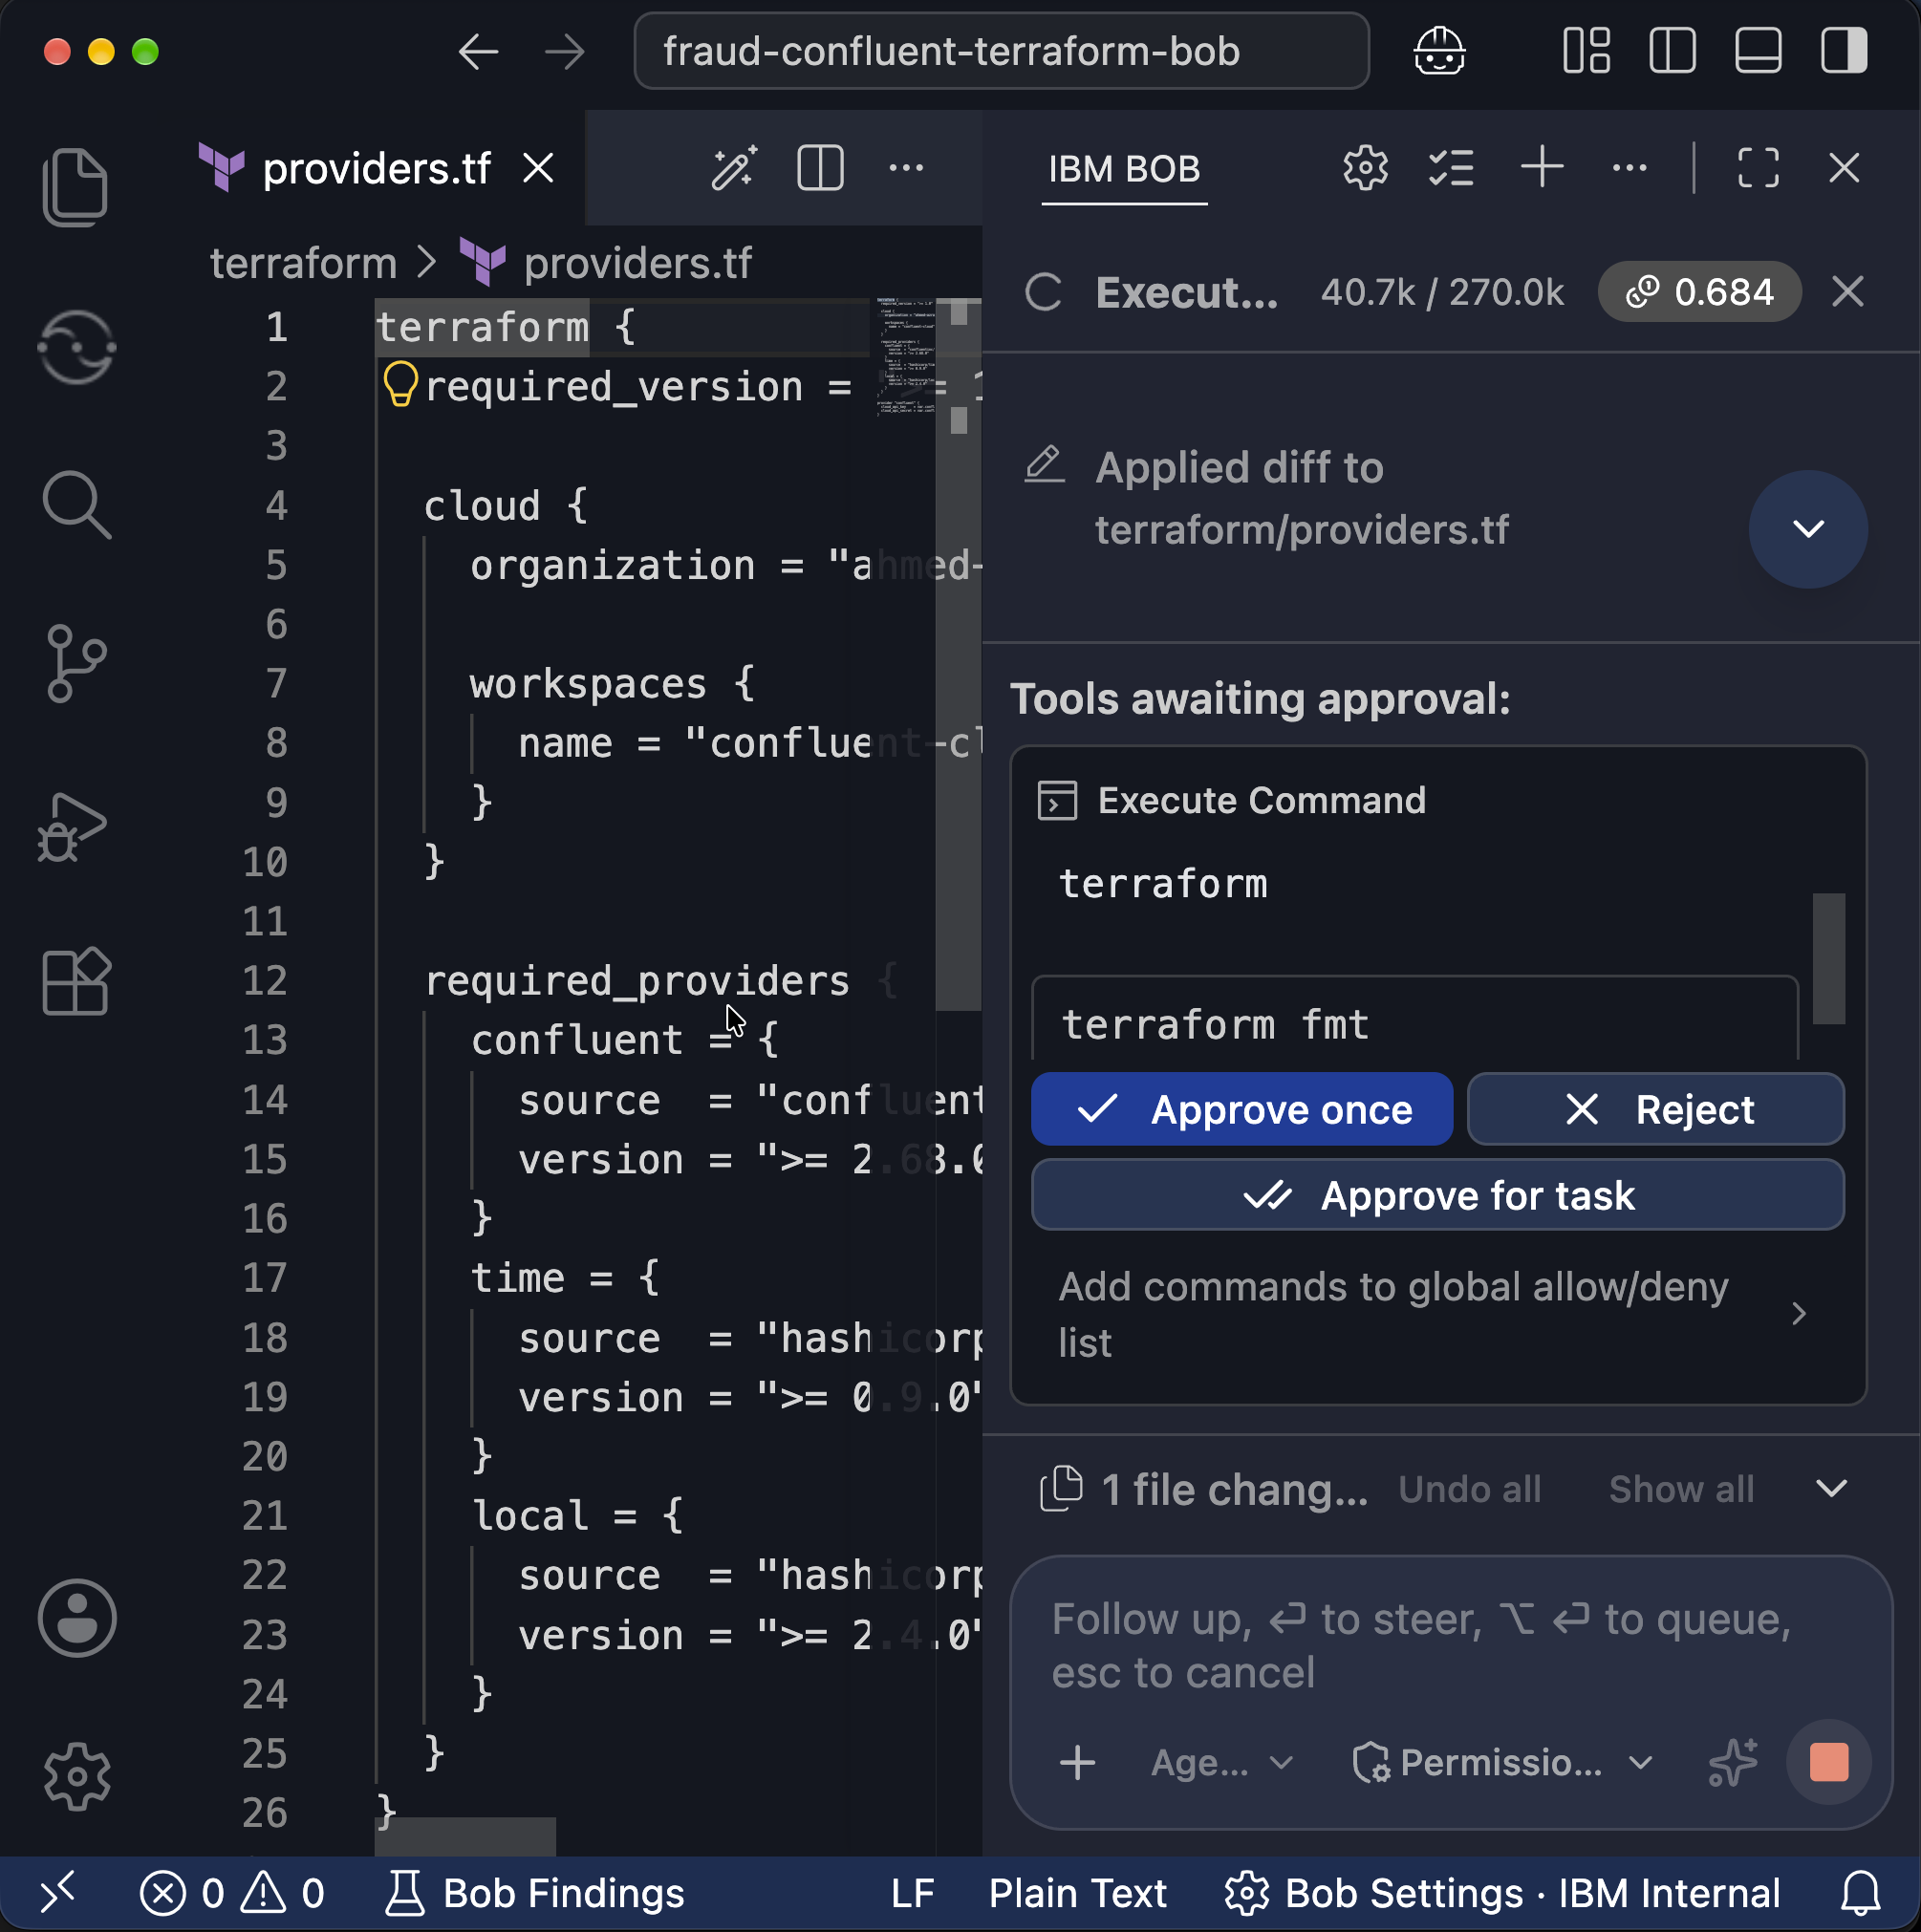
Bob creates the todo list for deploying the fraud detection Confluent infrastructure, breaking down the Terraform deployment process into four steps: initialize Terraform (download providers), validate Terraform configuration (check syntax), apply Terraform to create infrastructure (provision resources through running remotely on HCP Terraform), and verify deployment outputs (confirm successful creation). Click Approve to have Bob deploy the fraud detection Confluent infrastructure. Click on Approve for task for the different HCP Terraform commands.
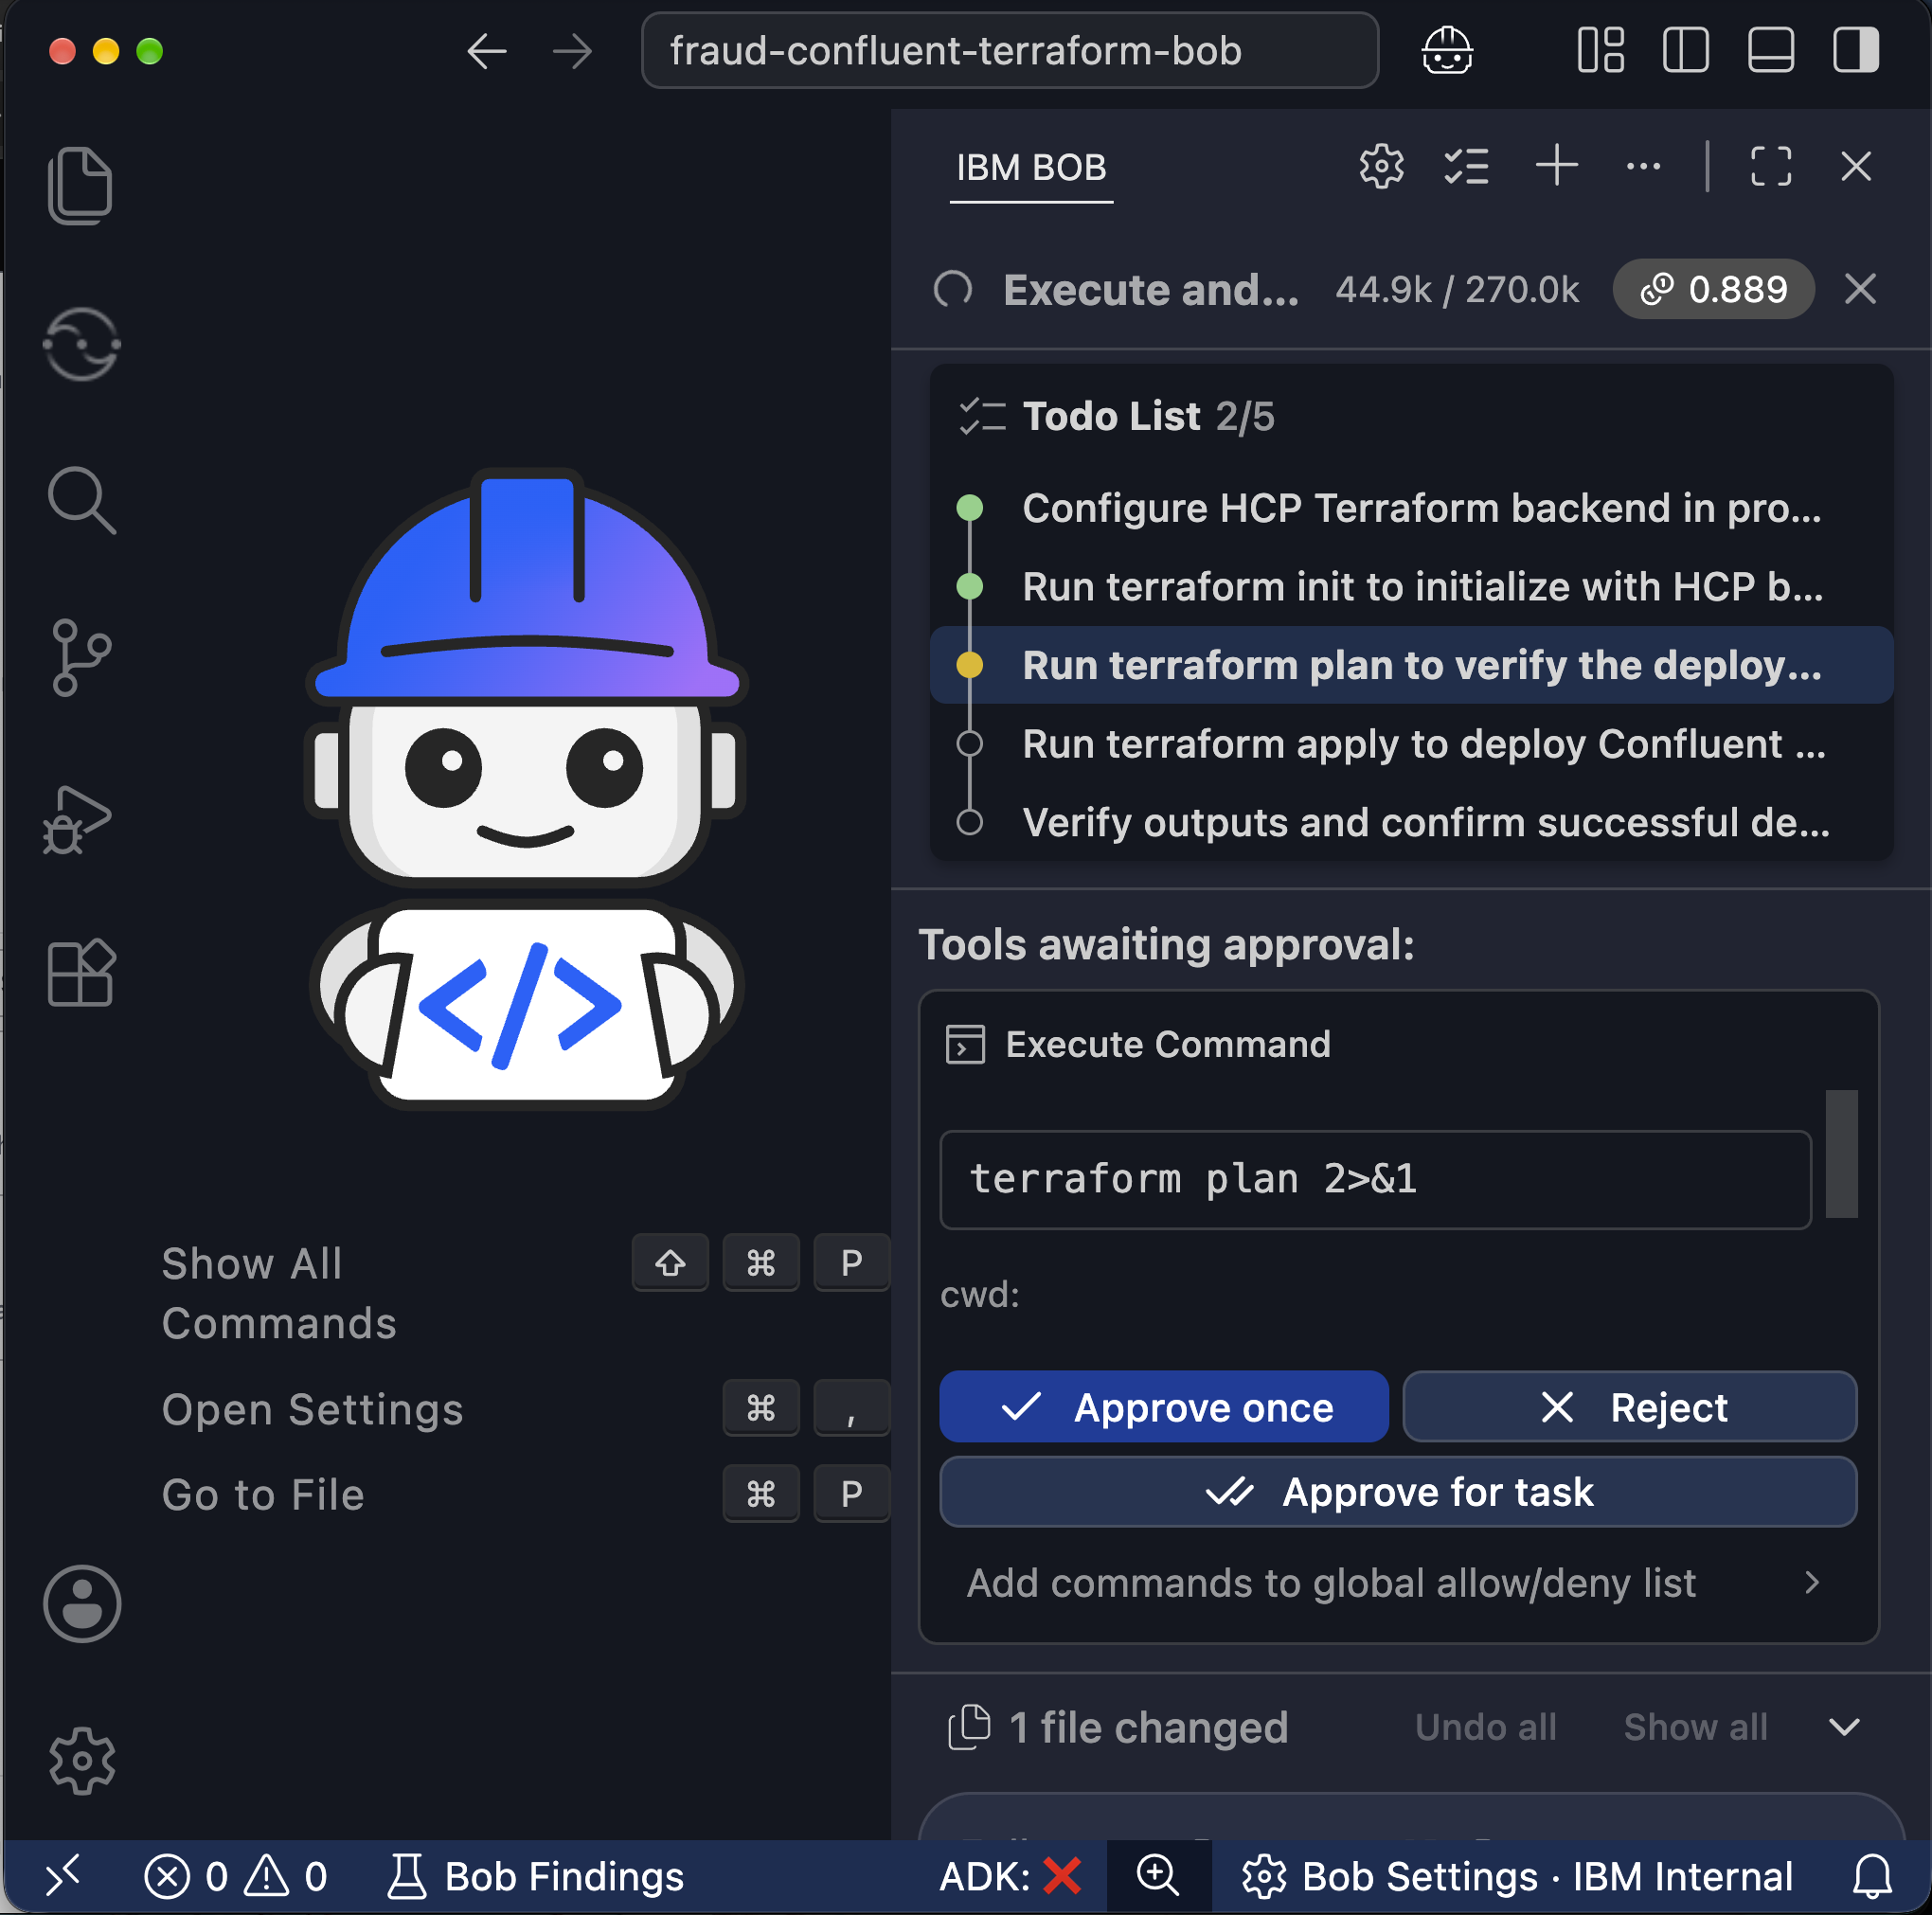
Bob has validated the Terraform configuration successfully, and now requests approval to provision the Confluent Cloud infrastructure. Click Approve for task to execute the Terraform apply command. It will take a few minutes to create the different resources.
If Bob tells you that “API credentials are invalid”, make sure that you updated the Confluent API credentials in the
terraform.tfvarsfile.
Bob automatically identifies and fixes issues that occur while creating the Confluent Cloud infrastructure.

While
terraform applyis running, monitor the deployment status on the Runs page in HCP Terraform. The Runs page also provides an audit history of the Terraform runs.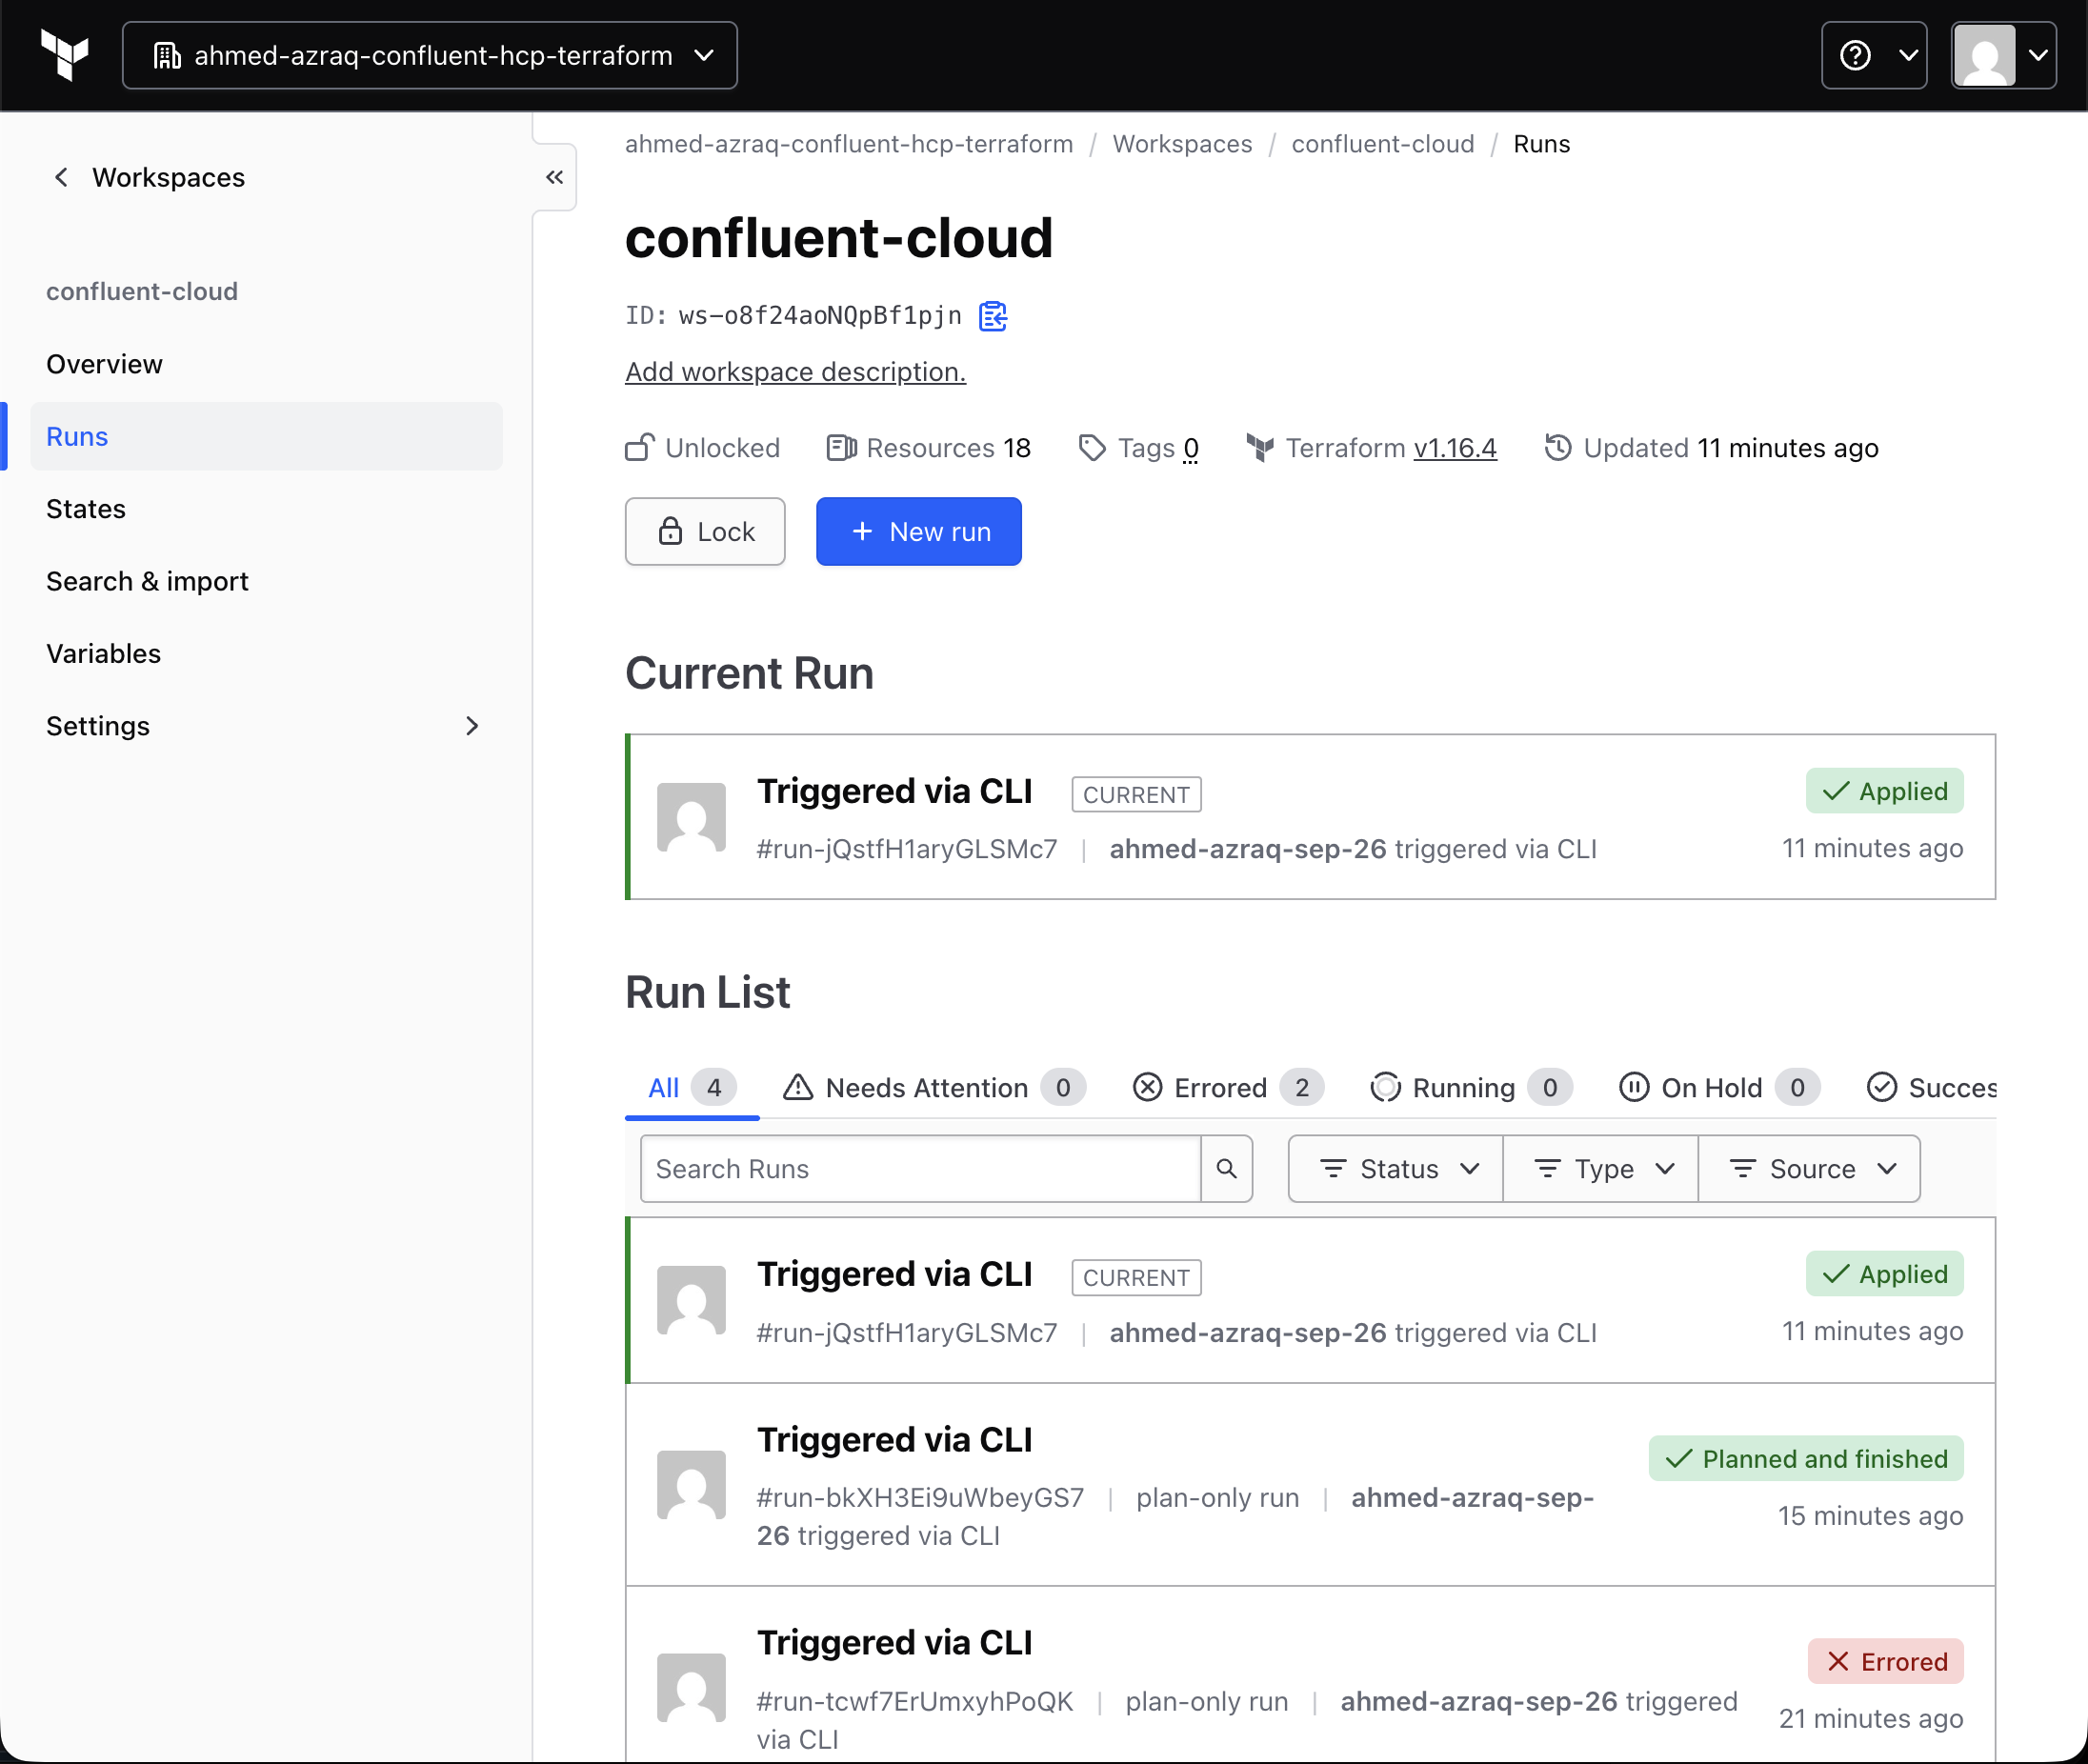
Once Bob is done with applying Terraform to create the infrastructure, Bob verifies and displays the deployment outputs, including cluster endpoints, topic names, and resource IDs that will be needed for the Python producer configuration.

Step 6. Verify the Confluent infrastructure in Confluent Cloud
Now it's time to check out the resources that you just provisioned. Confluent Cloud organizes resources in a hierarchical fashion: the top-level element is the organization, which contains 1 or more environments. Within a single environment, you have 1 Schema Registry instance, but you can host multiple Kafka clusters and Flink compute pools. While this hierarchy only scratches the surface of Confluent's capabilities, it provides the necessary starting point for navigating the console.
In your environment, there is a Kafka cluster and a Flink compute pool. The Terraform configuration also defined two Flink tables with a specific structure, which in turn created two corresponding Kafka topics. These topics are governed by a proper Data Contract schema linked via the Schema Registry, ensuring that your streaming pipeline is both structured and secure.
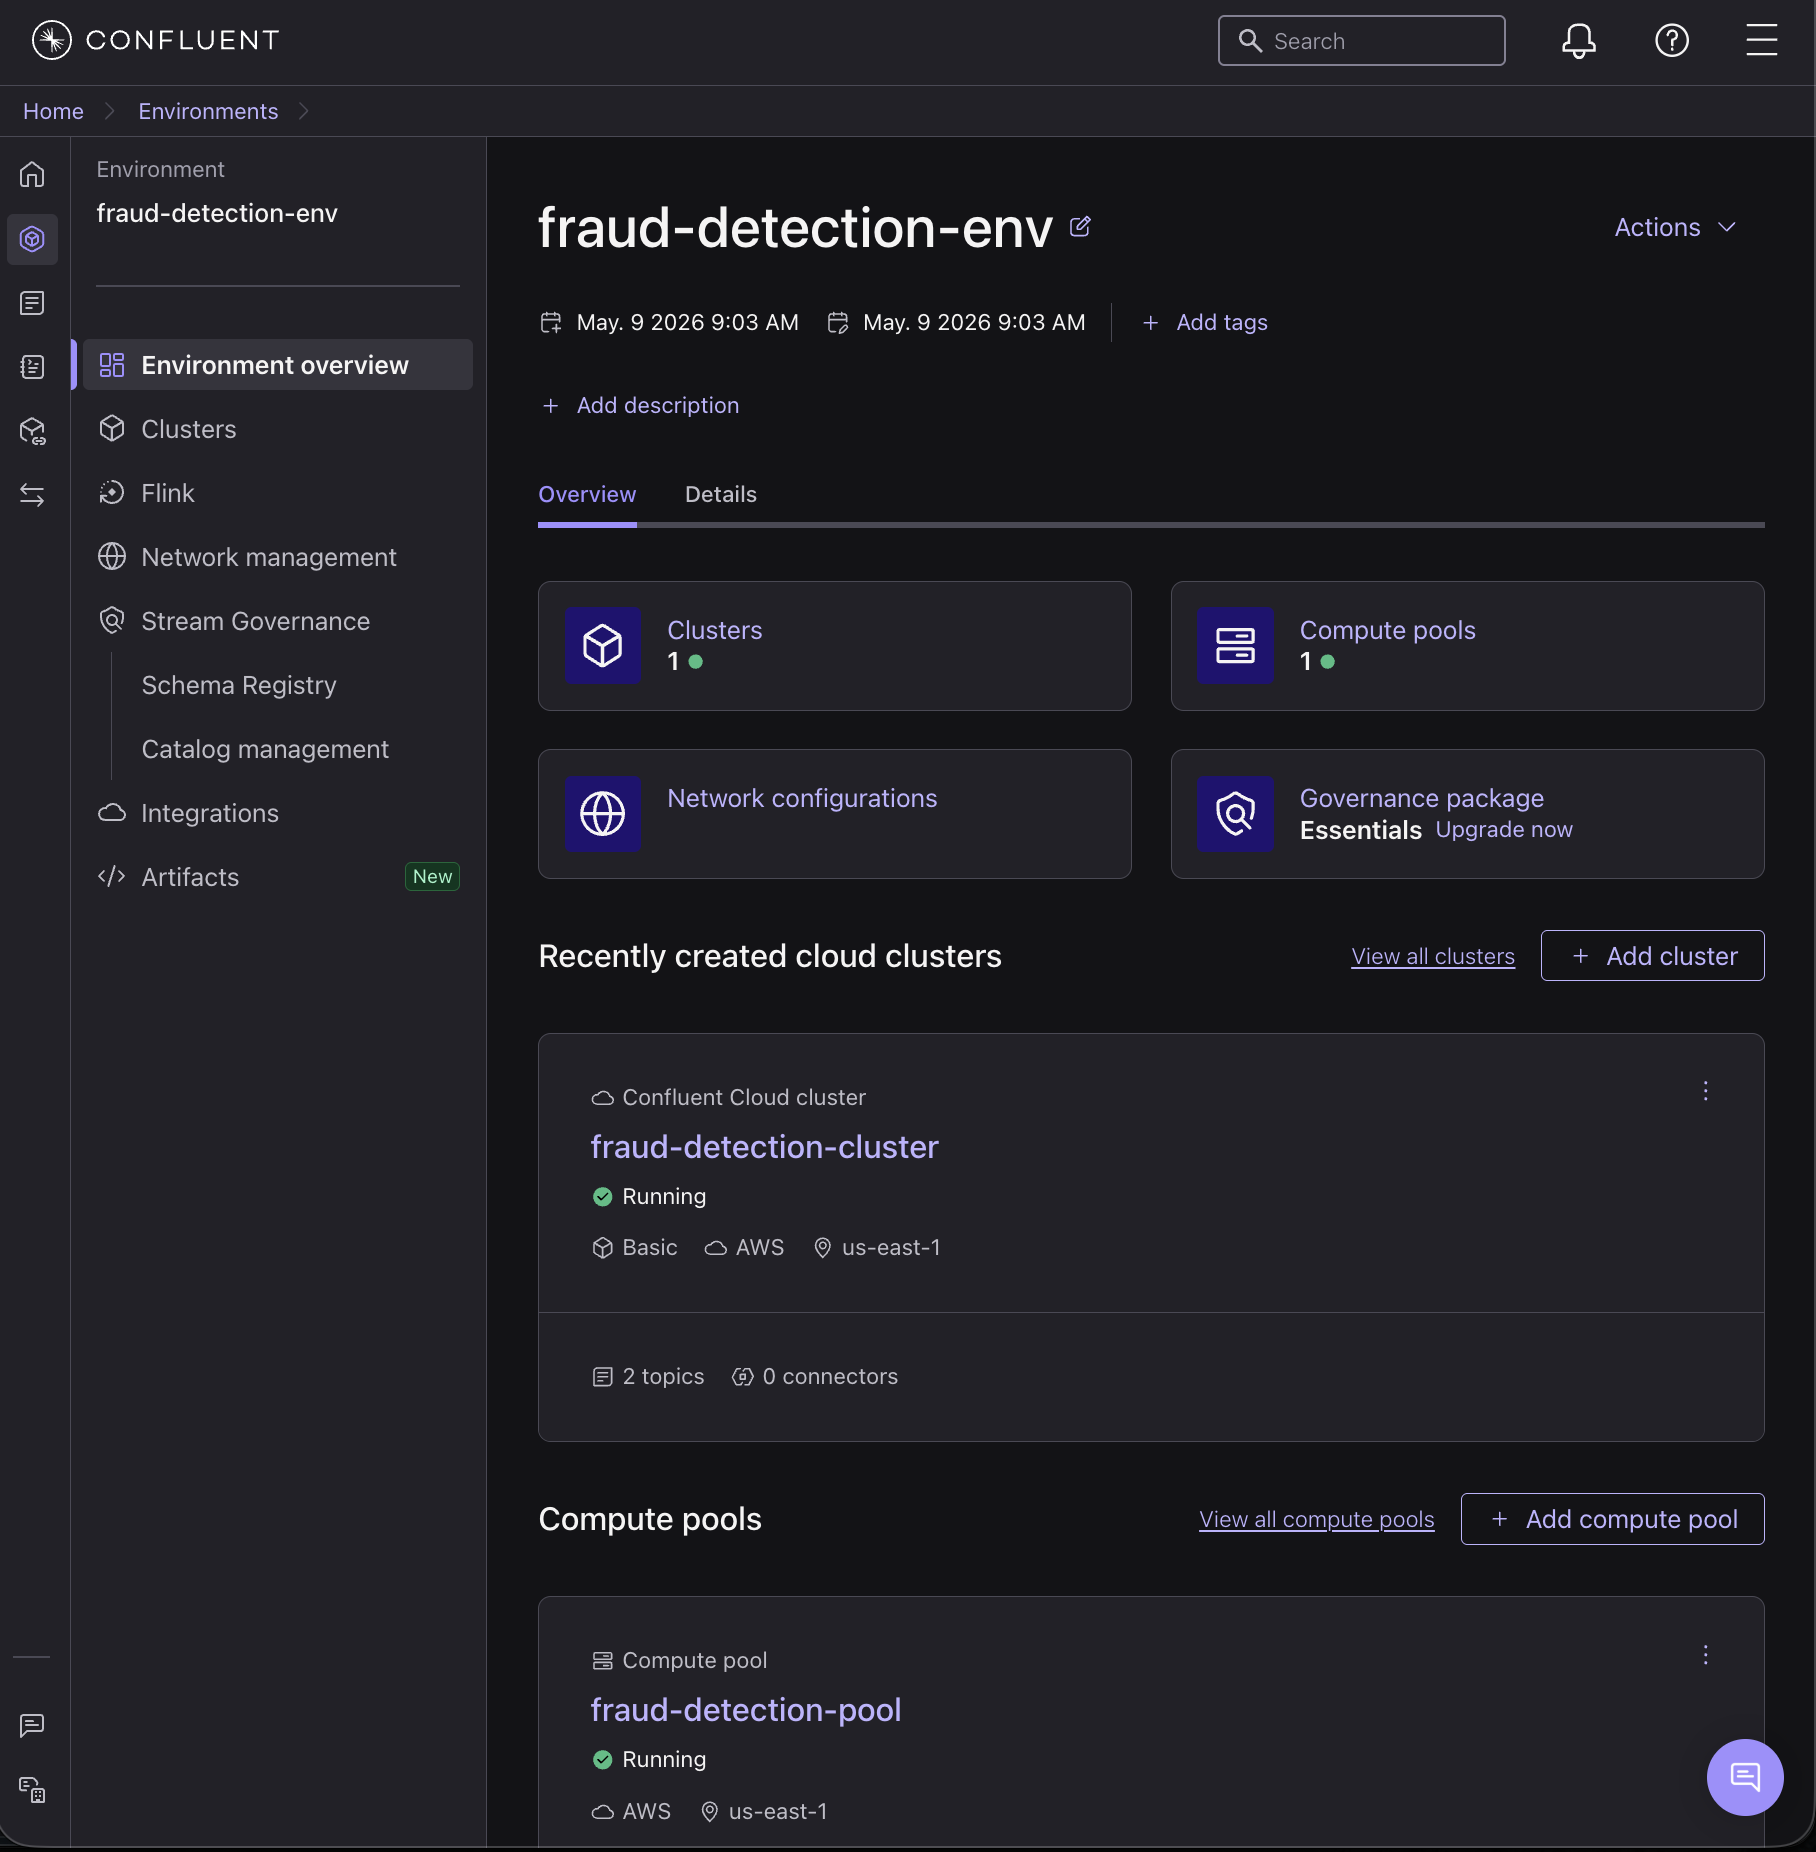
Open Confluent Cloud. The home page shows 1 environment, 1 Kafka cluster, 2 topics, and 1 Apache Flink compute pool.
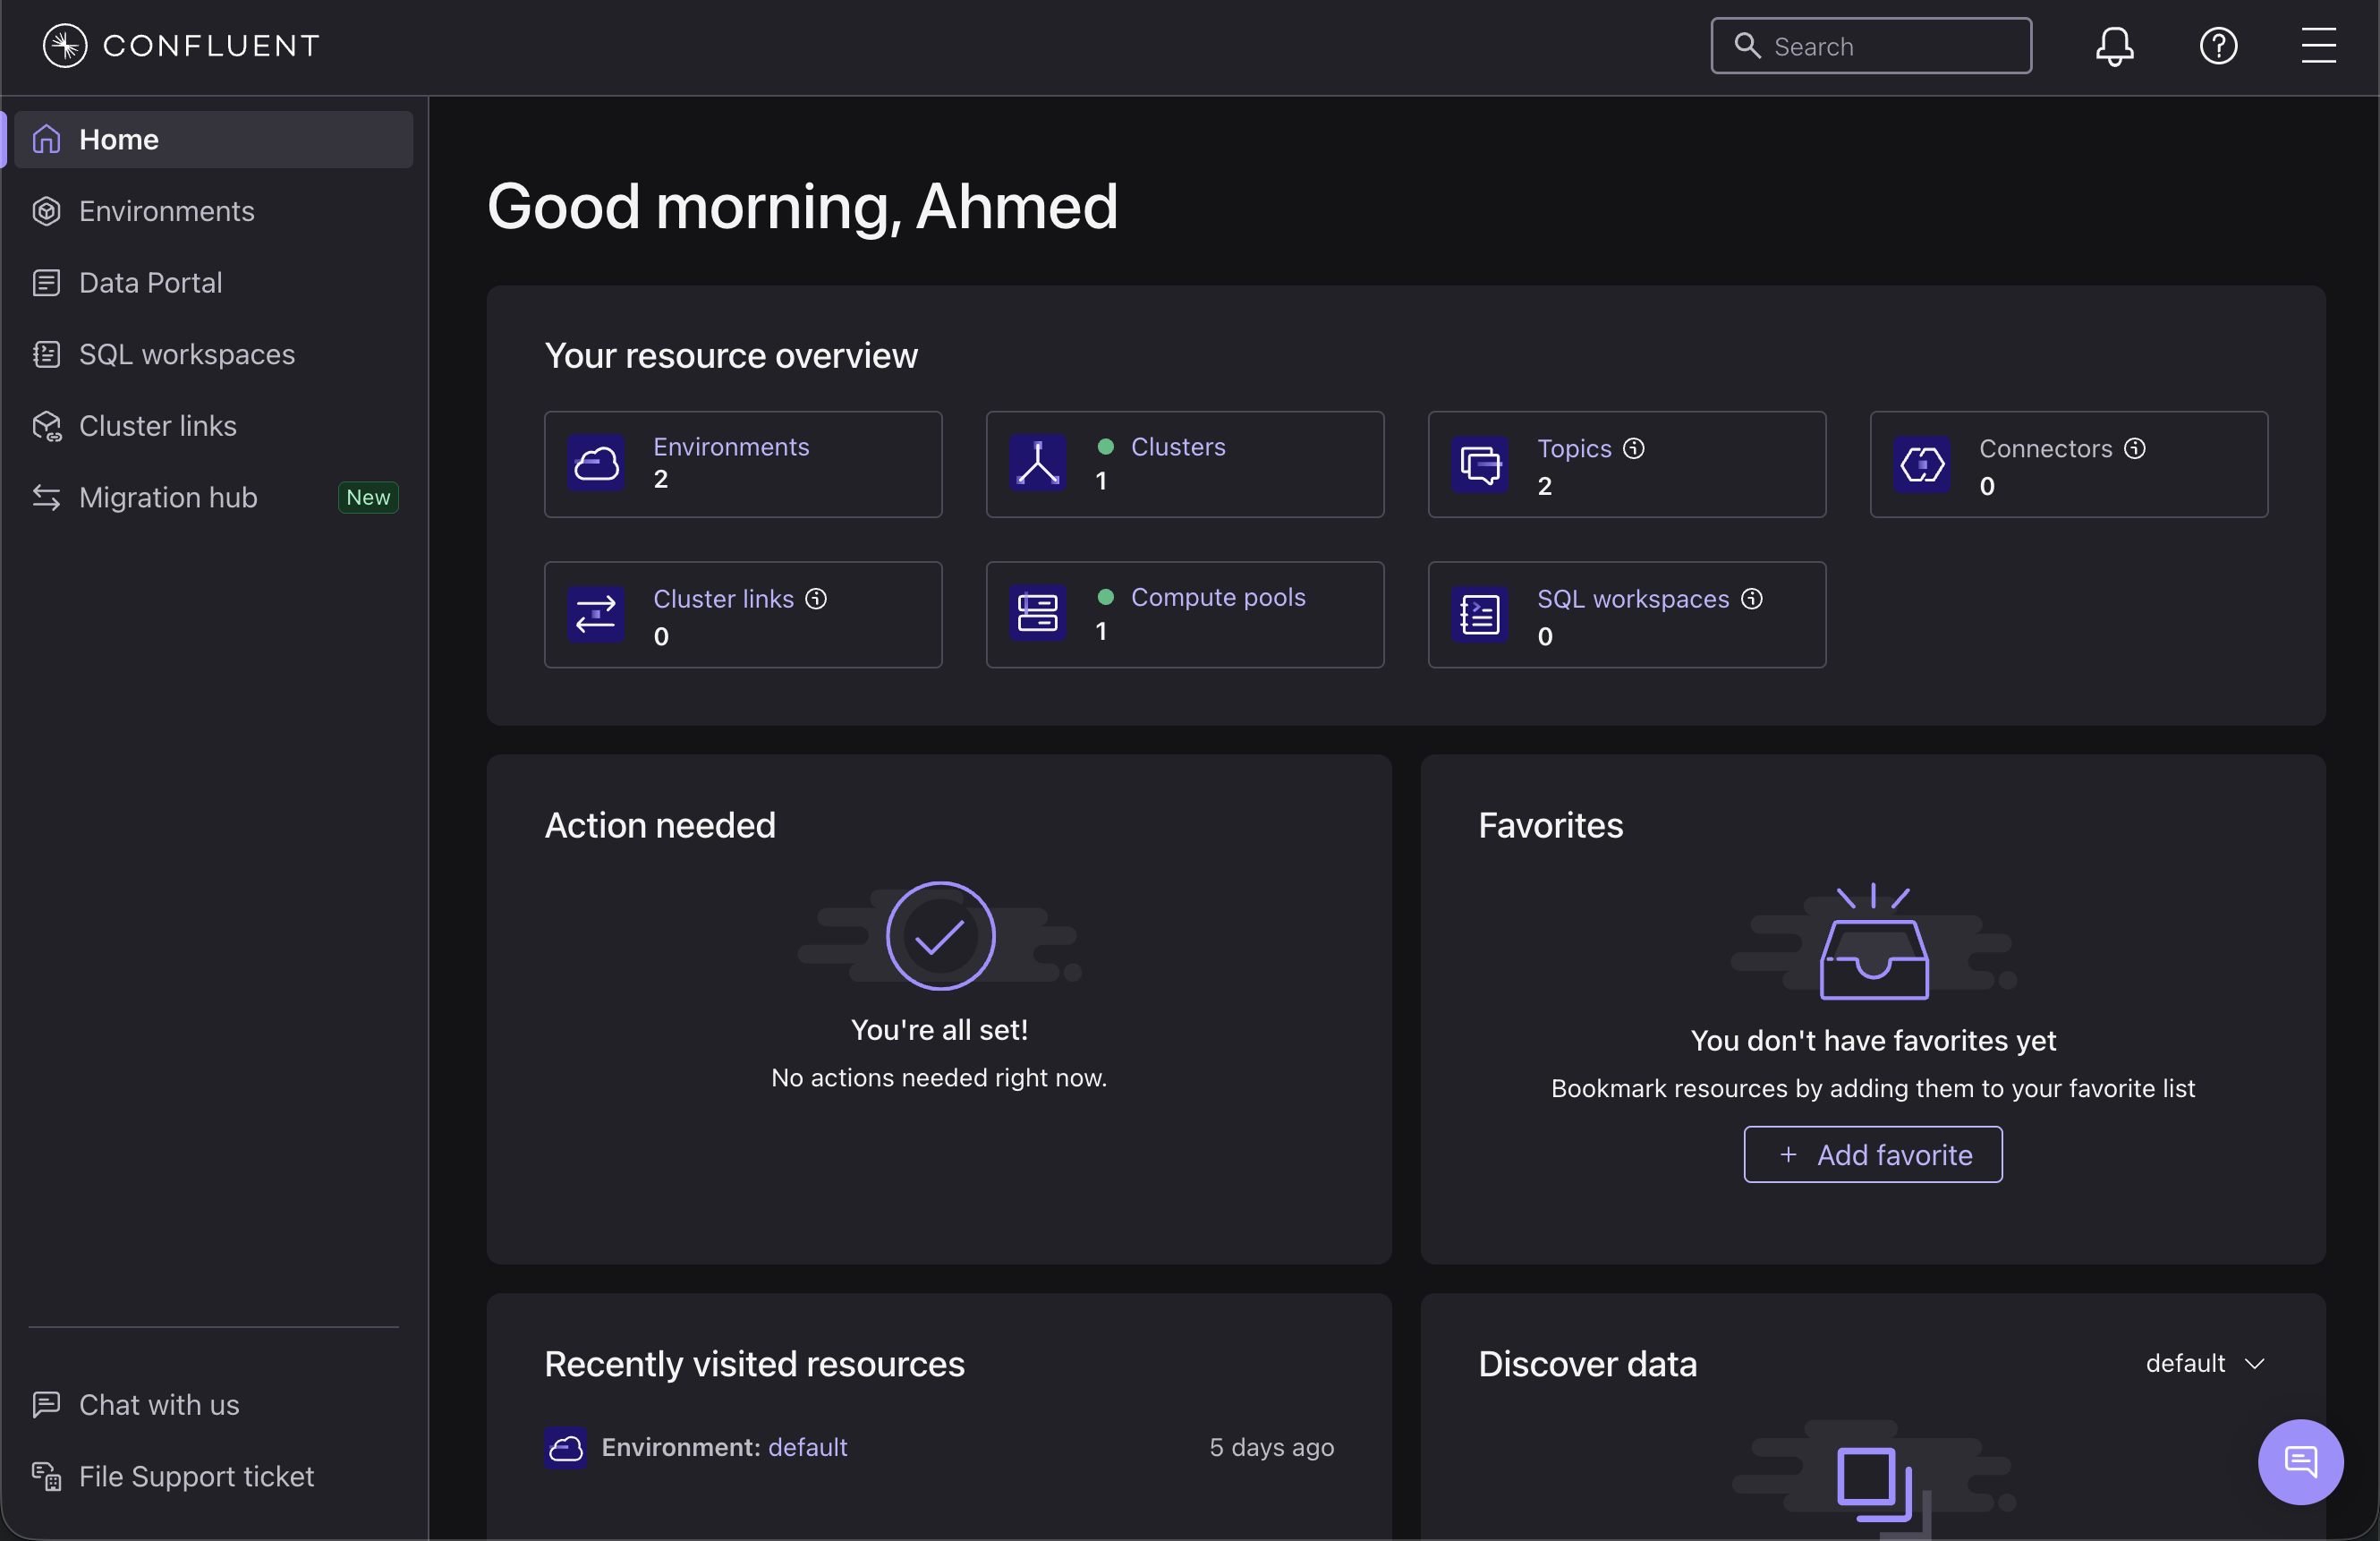
Click Environments and then open the environment. It shows the Kafka cluster and Flink compute pool.
Click Flink on the left sidebar. You can see the Flink SQL statements in the Confluent Cloud console:
- 2
CREATE TABLEstatements that automatically create the underlying Kafka topics: 1 source table for incoming banking transactions and 1 sink table for detected fraudulent transactions 1
INSERT INTOstatement (running) that continuously analyzes the source stream and writes suspicious transactions to the sink running on 1 CFU (Confluent Flink Unit, the compute capacity unit for running Flink SQL jobs).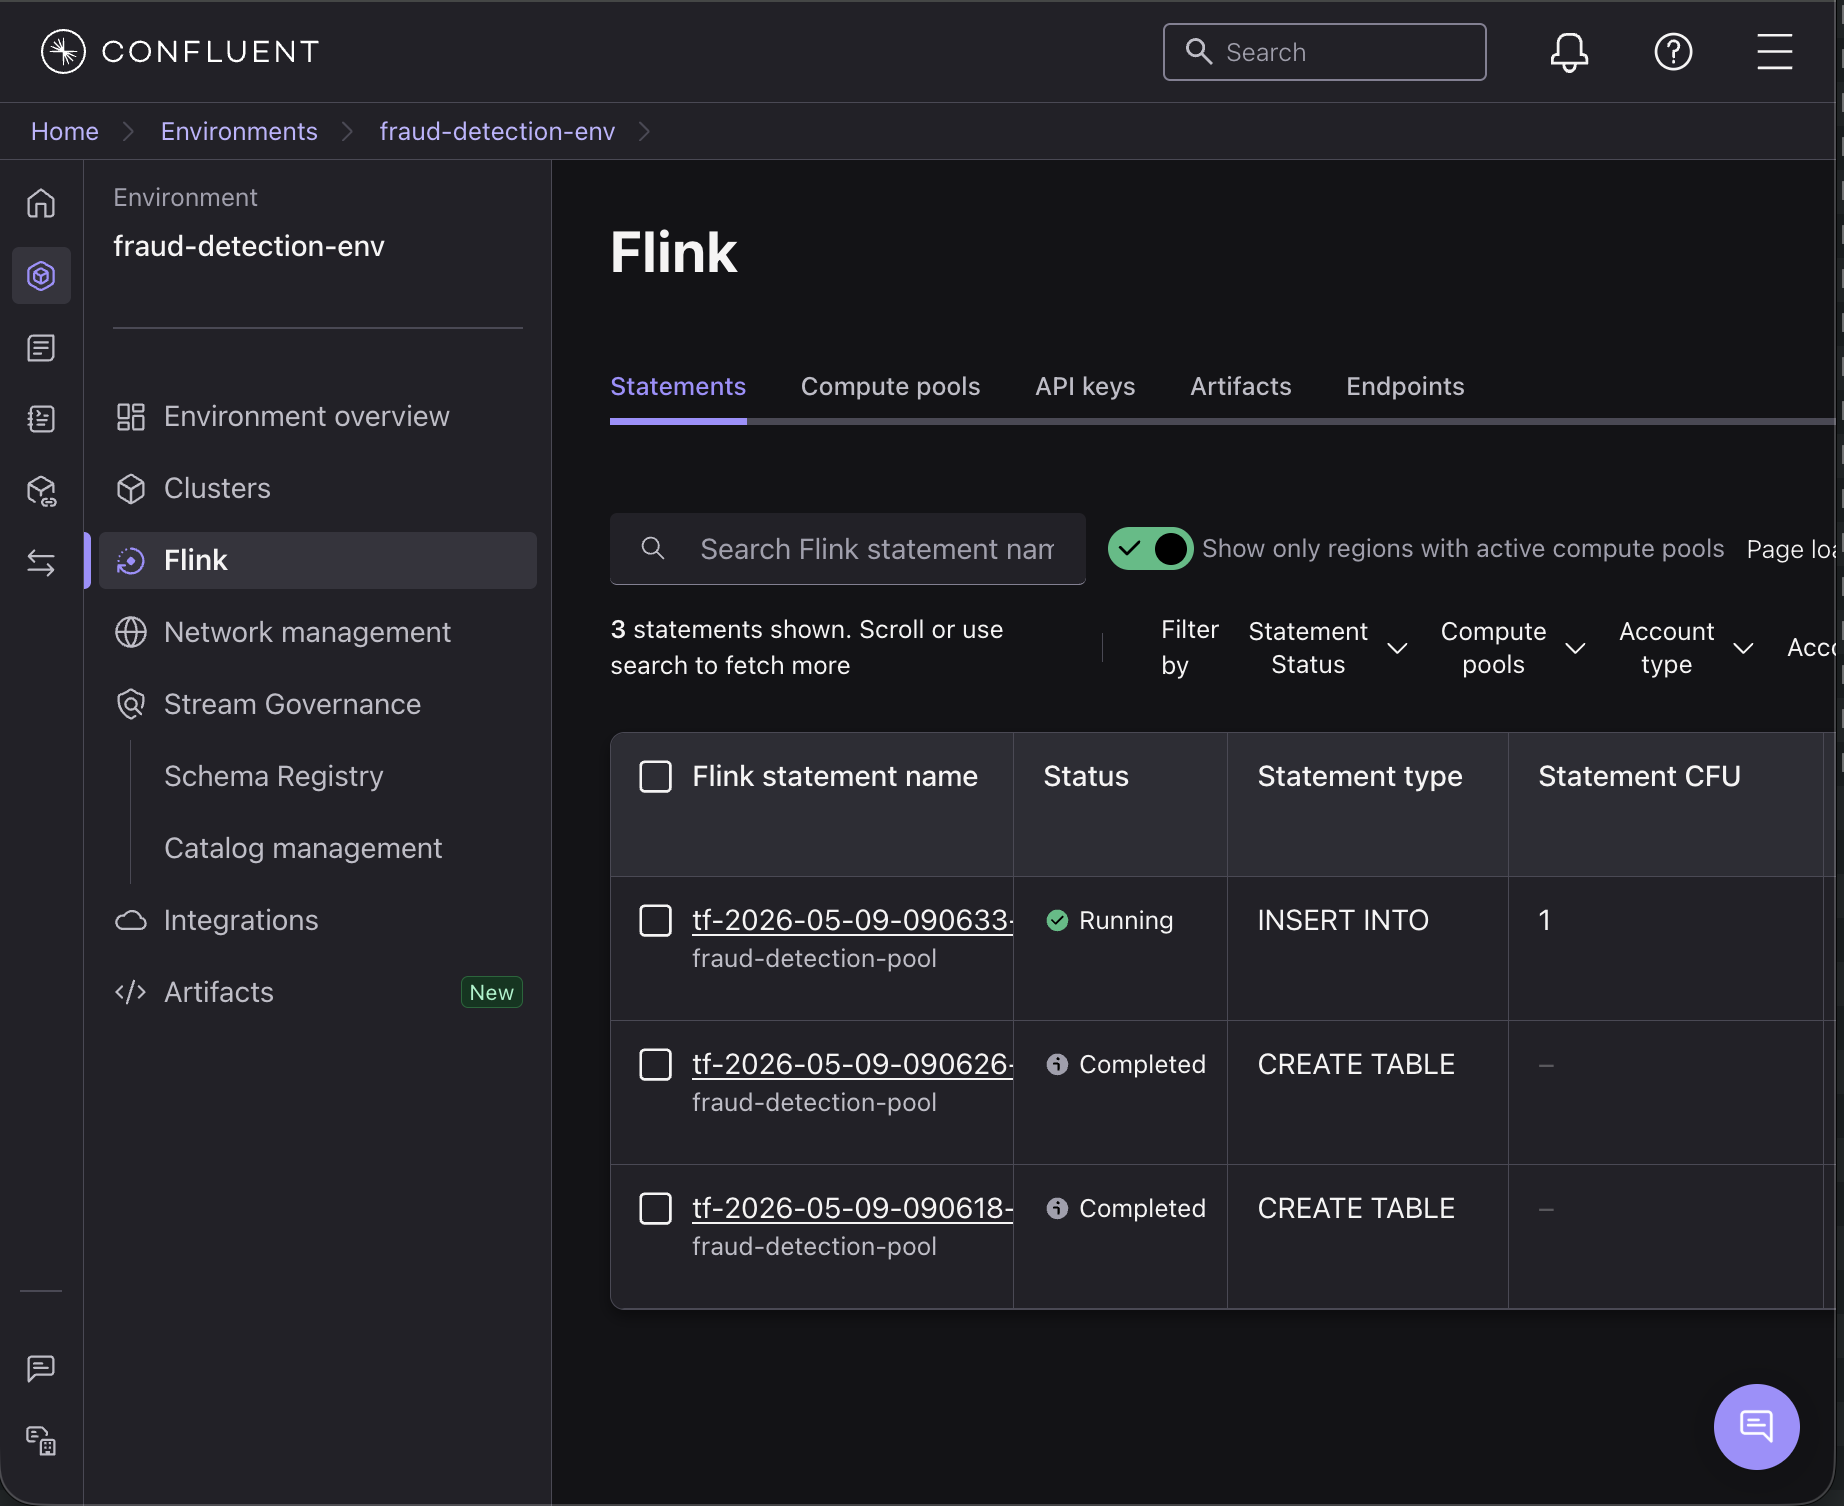
- 2
Click the
INSERT INTOstatement to understand more details. The Confluent SQL statement performs real-time fraud detection by creating 5-minute windows over the banking_transactions source table, grouping transactions by account_id and time window. It calculates the transaction count and total amount per window, then flags accounts as fraudulent (is_fraud = TRUE) when more than 10 transactions occur within a single 5-minute window. This is a common indicator of suspicious activity, doing a lot of transactions at small interval. The results are continuously written to the fraud_alerts sink table.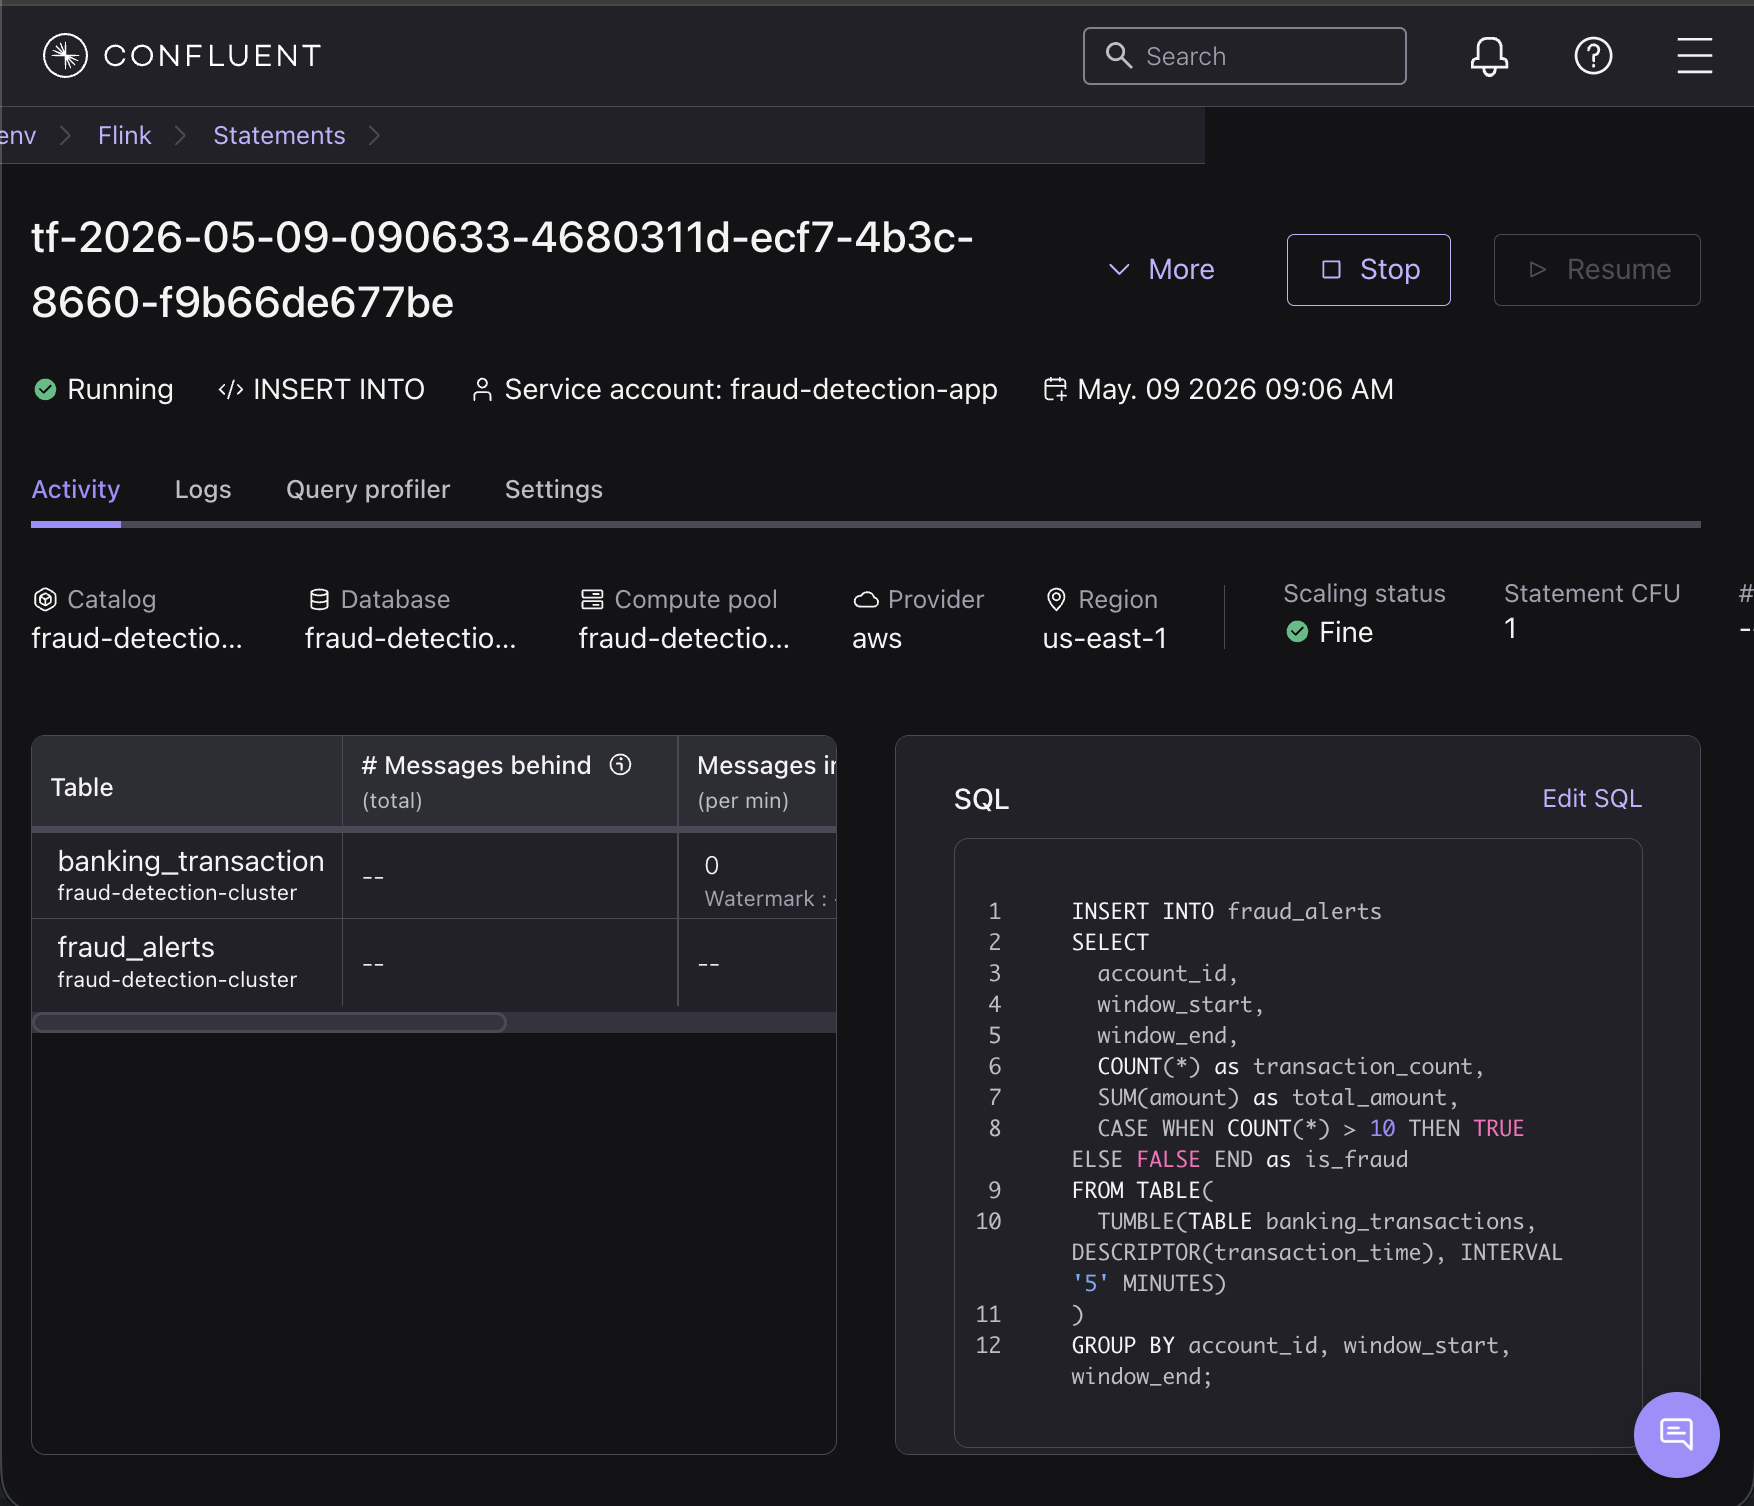
Click Clusters in the left menu to view the Kafka clusters.
Open the created Kafka cluster.
Click Topics in the left menu to view the created topics. These topics have been created by the Flink SQL Create Table statements. The
banking_transactionstopic will receive incoming transaction data from ATMs, internet banking, mobile apps, and point-of-sale systems, while thefraud_alertstopic stores the detected fraudulent transactions flagged by the real-time Flink SQL analysis.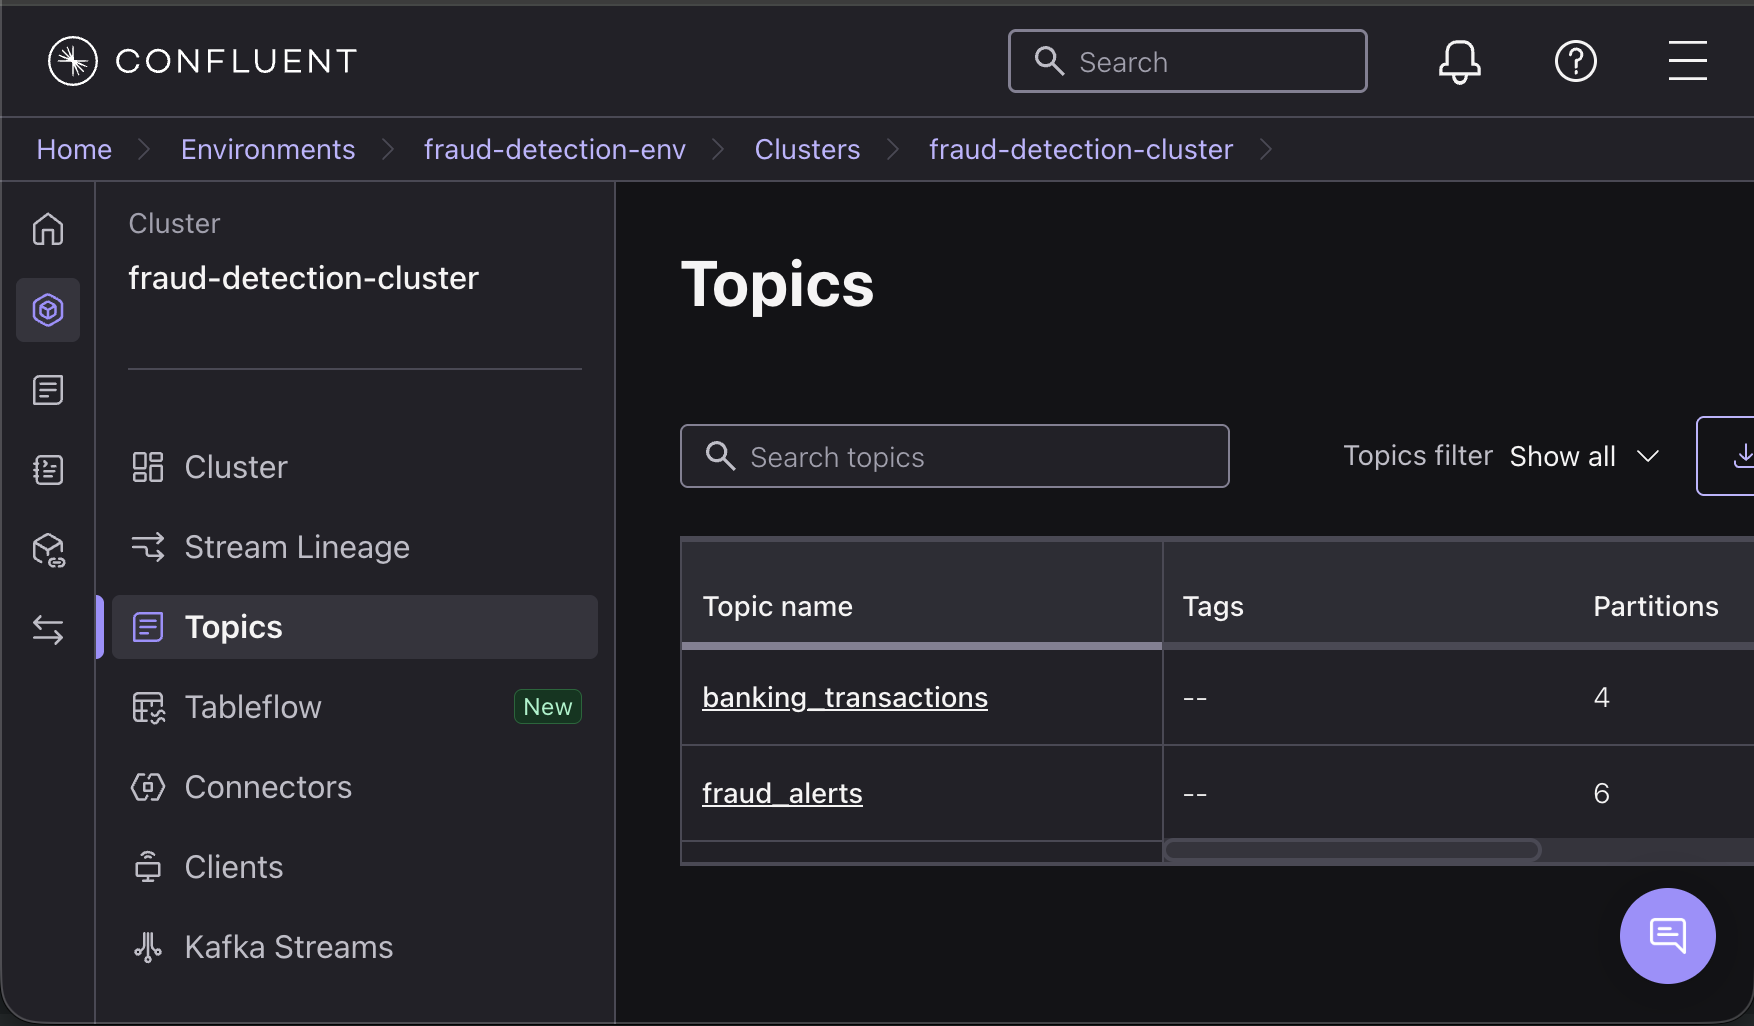
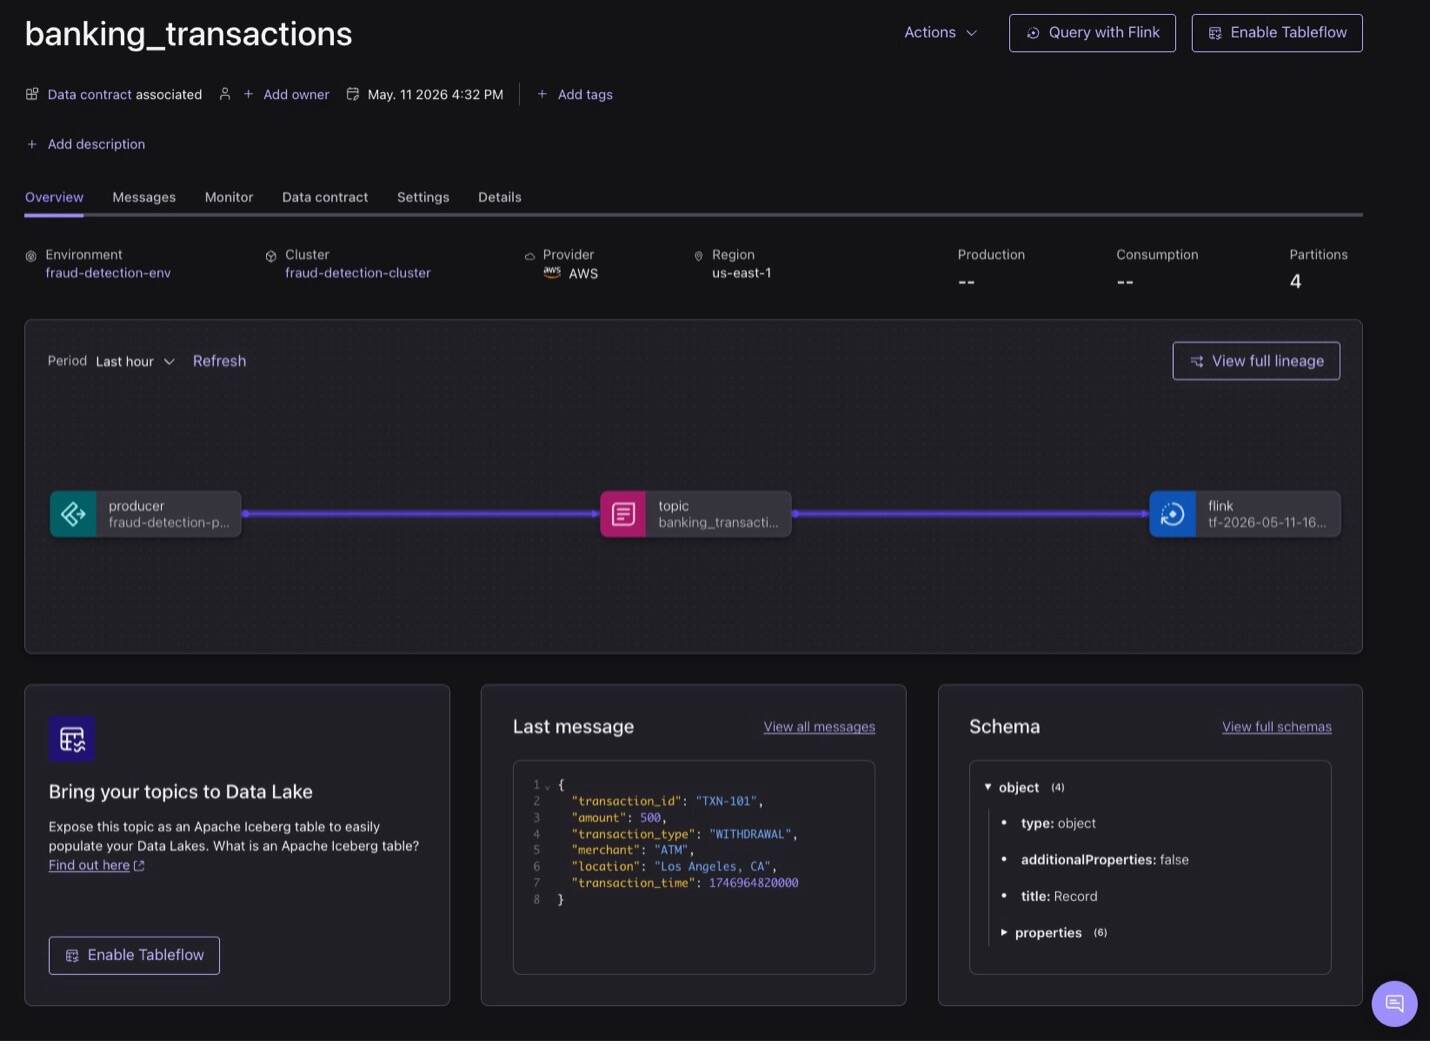
Click one of the topics. The Overview tab provides immediate insights into the topic, including real-time traffic metrics and a narrowed data lineage view specific to that topic. You can also inspect the most recent messages and review the associated data contract.
Step 7. Simulate fraudulent banking transactions
In this step, you simulate fraudulent banking transactions by asking Bob to add sample transactions to the source Kafka topic.
In the Bob IDE chat interface, click New task.
Instruct Bob in natural language to produce the message to the Kafka topic.
Add sample banking transactions to the Kafka topic on Confluent.
Bob first checks that Terraform created the python
.envfile with Kafka connection credentials for the Python producer. If the Python virtual environment does not exist, Bob creates the virtual environment. Click Approve for task.
Bob installs the dependencies and runs the script to produce the sample transactions. Click Approve for task.

Bob confirms that all messages are delivered to the topic, and some of them are very frequent which indicates a fraud case.

Optionally, ask Bob to create a continuous Kafka producer that generates banking transactions every 0.5-1.5 seconds, with 85% going to fraud accounts and 15% to normal accounts. This allows you to observe real-time fraud detection as transactions flow continuously and triggers alert.
Create a Python continuous Kafka producer for banking fraud detection. Generate transactions every 0.5-1.5 seconds with current timestamps. Use 5 fraud accounts (ACCOUNT-FRAUD-01 to 05) receiving 85% of transactions, and 5 normal accounts (ACCOUNT-10001 to 05) receiving 15%. Include varying transaction types and amounts. Use Confluent Kafka with Schema Registry. Display real-time stats. Run until Ctrl+C.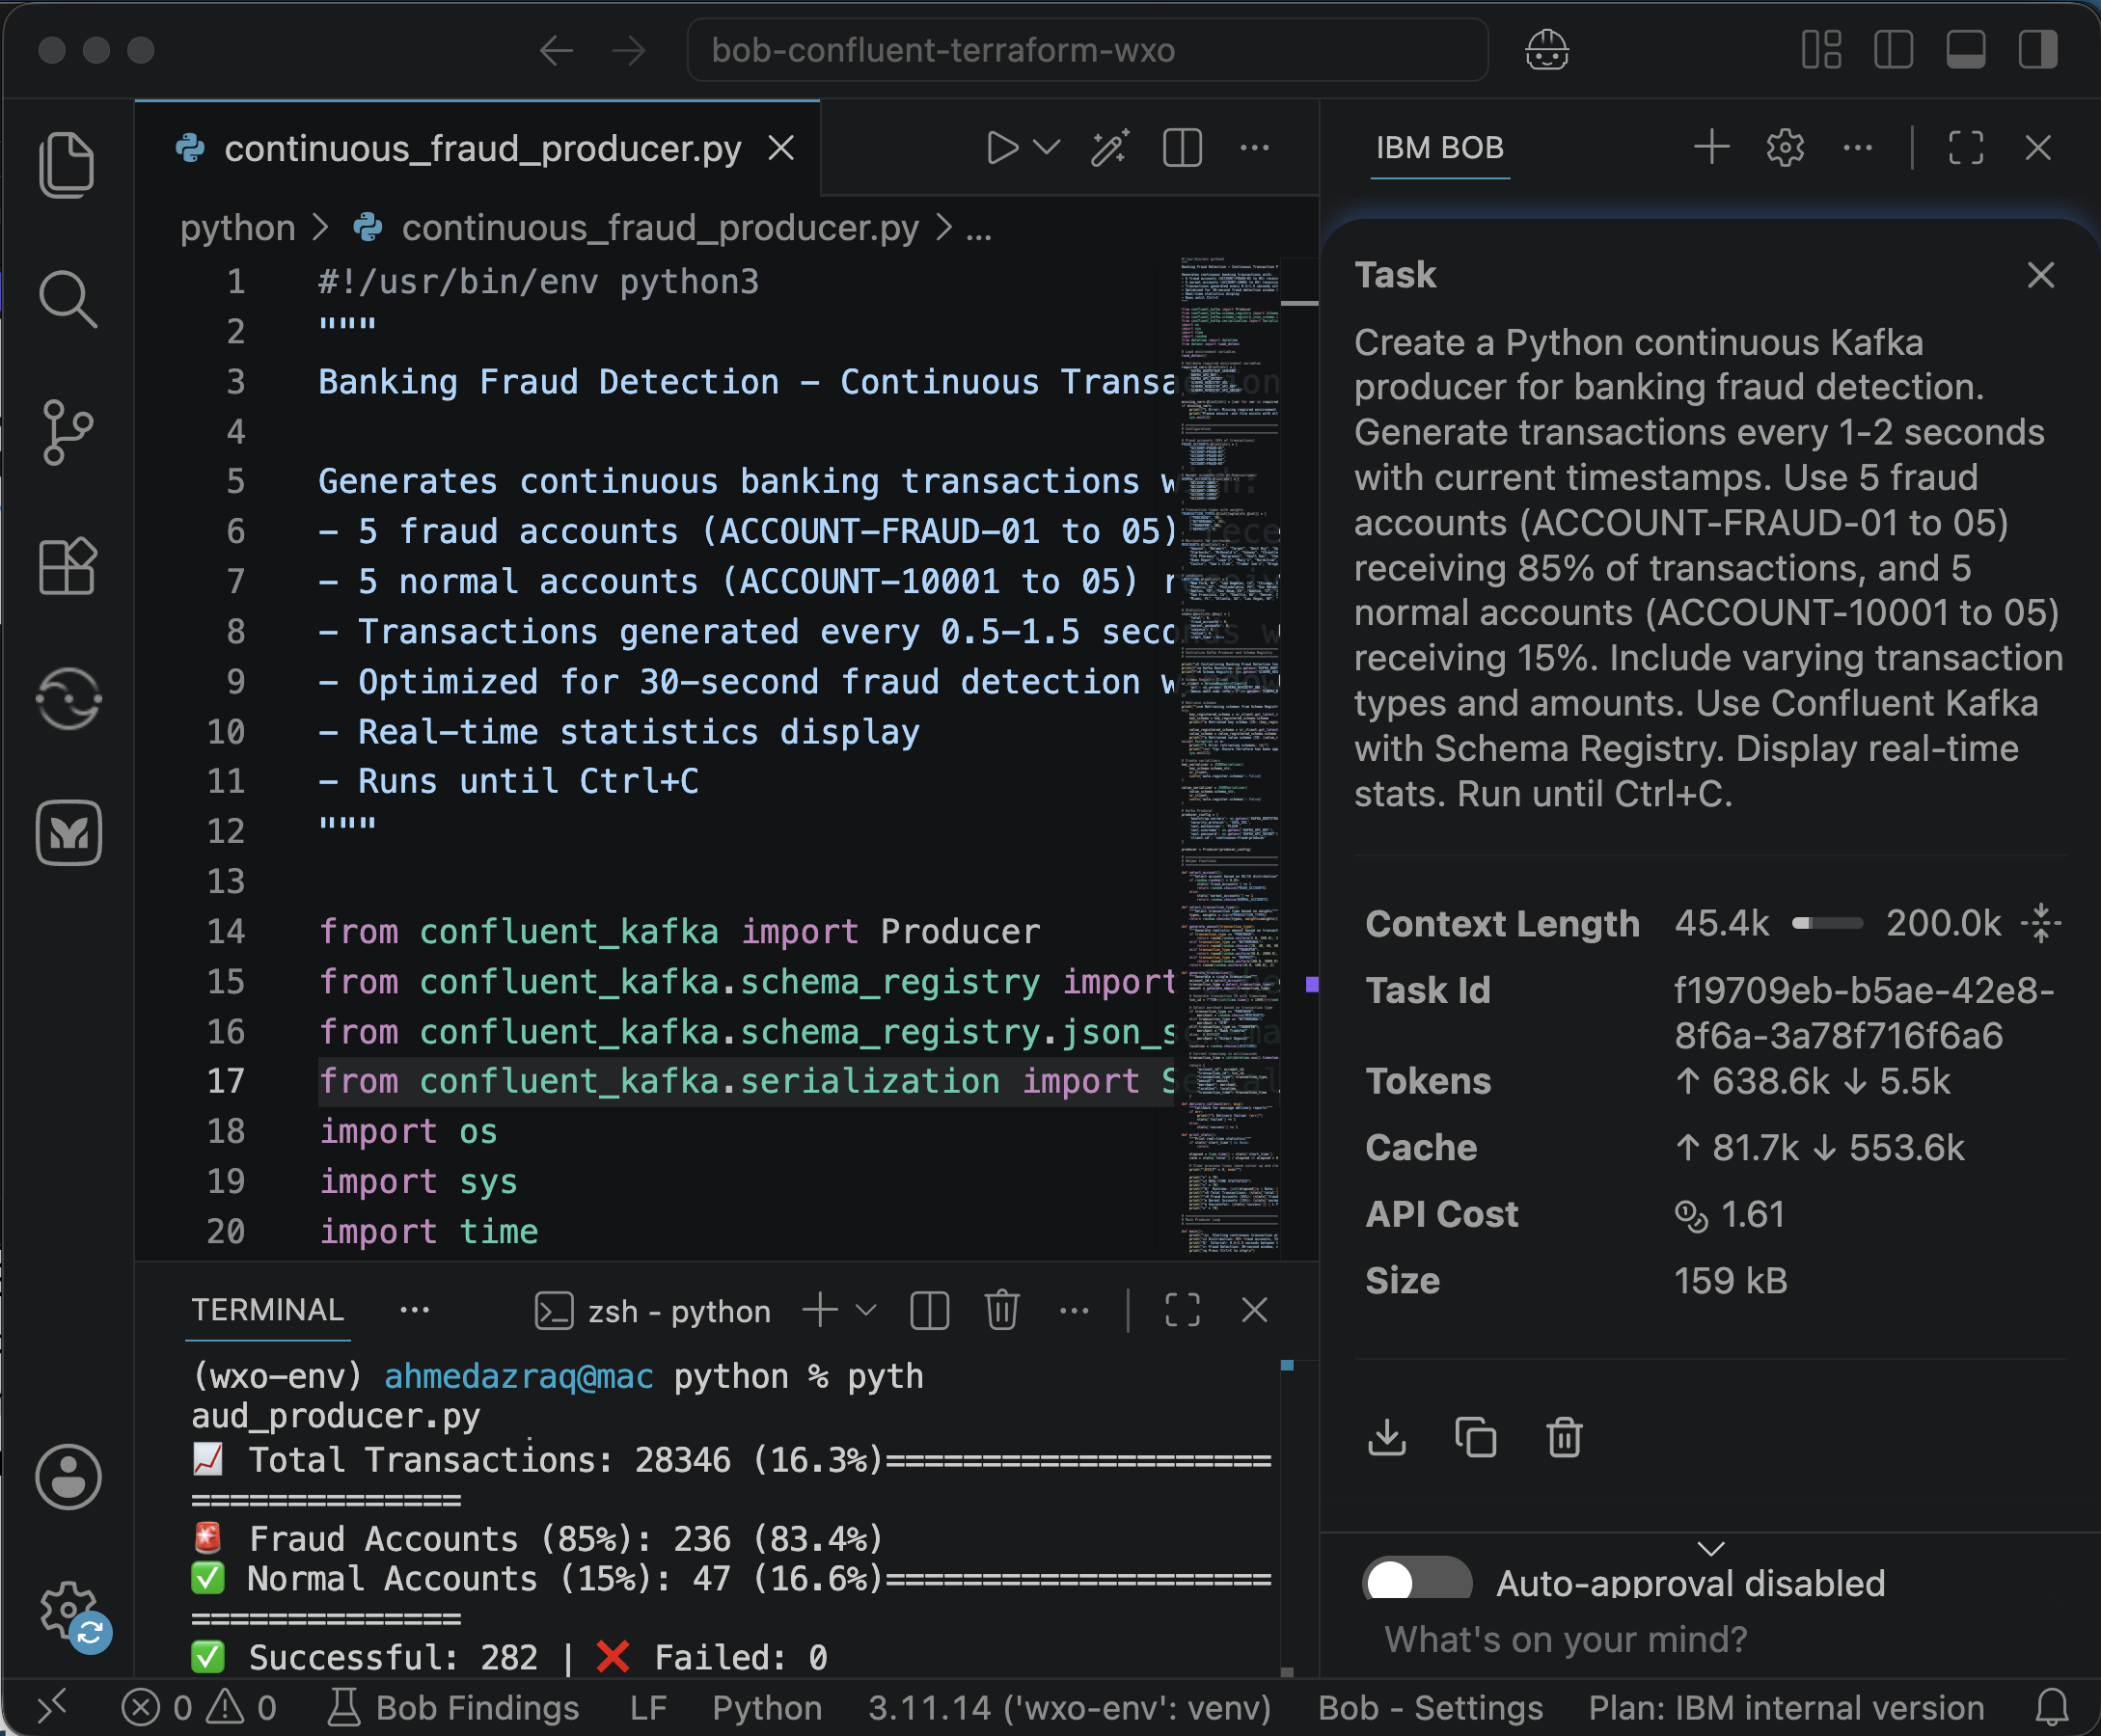
Step 8. Check for fraudulent cases in real time in Confluent Cloud
The Apache Flink integration in Confluent Cloud provides rich visual tools to introspect your data products from discovering data structures to building and running SQL statements in a powerful workspace.
Open Confluent Cloud, click Compute pools, and then open your Flink compute pool.
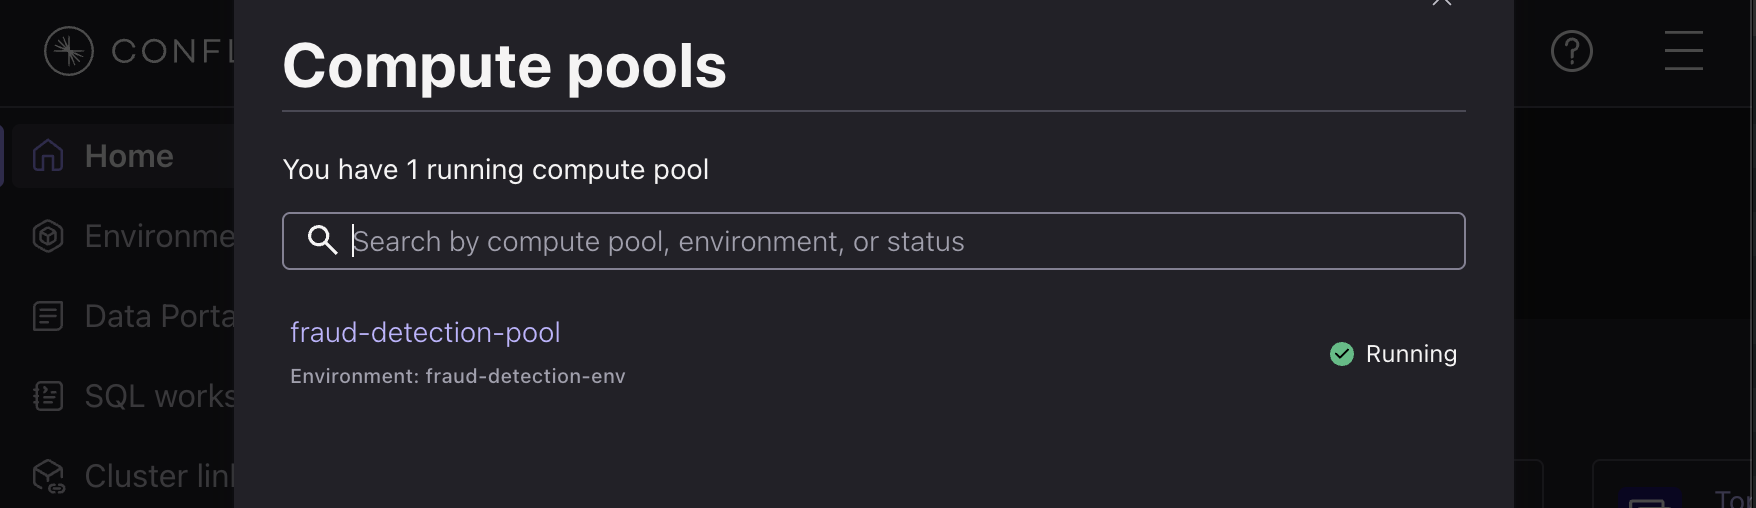
Click Open SQL workspace.
Write the following SQL statement, and then click Run. Make sure to update the table name based on what Terraform has created.
SELECT * from `fraud_alerts`;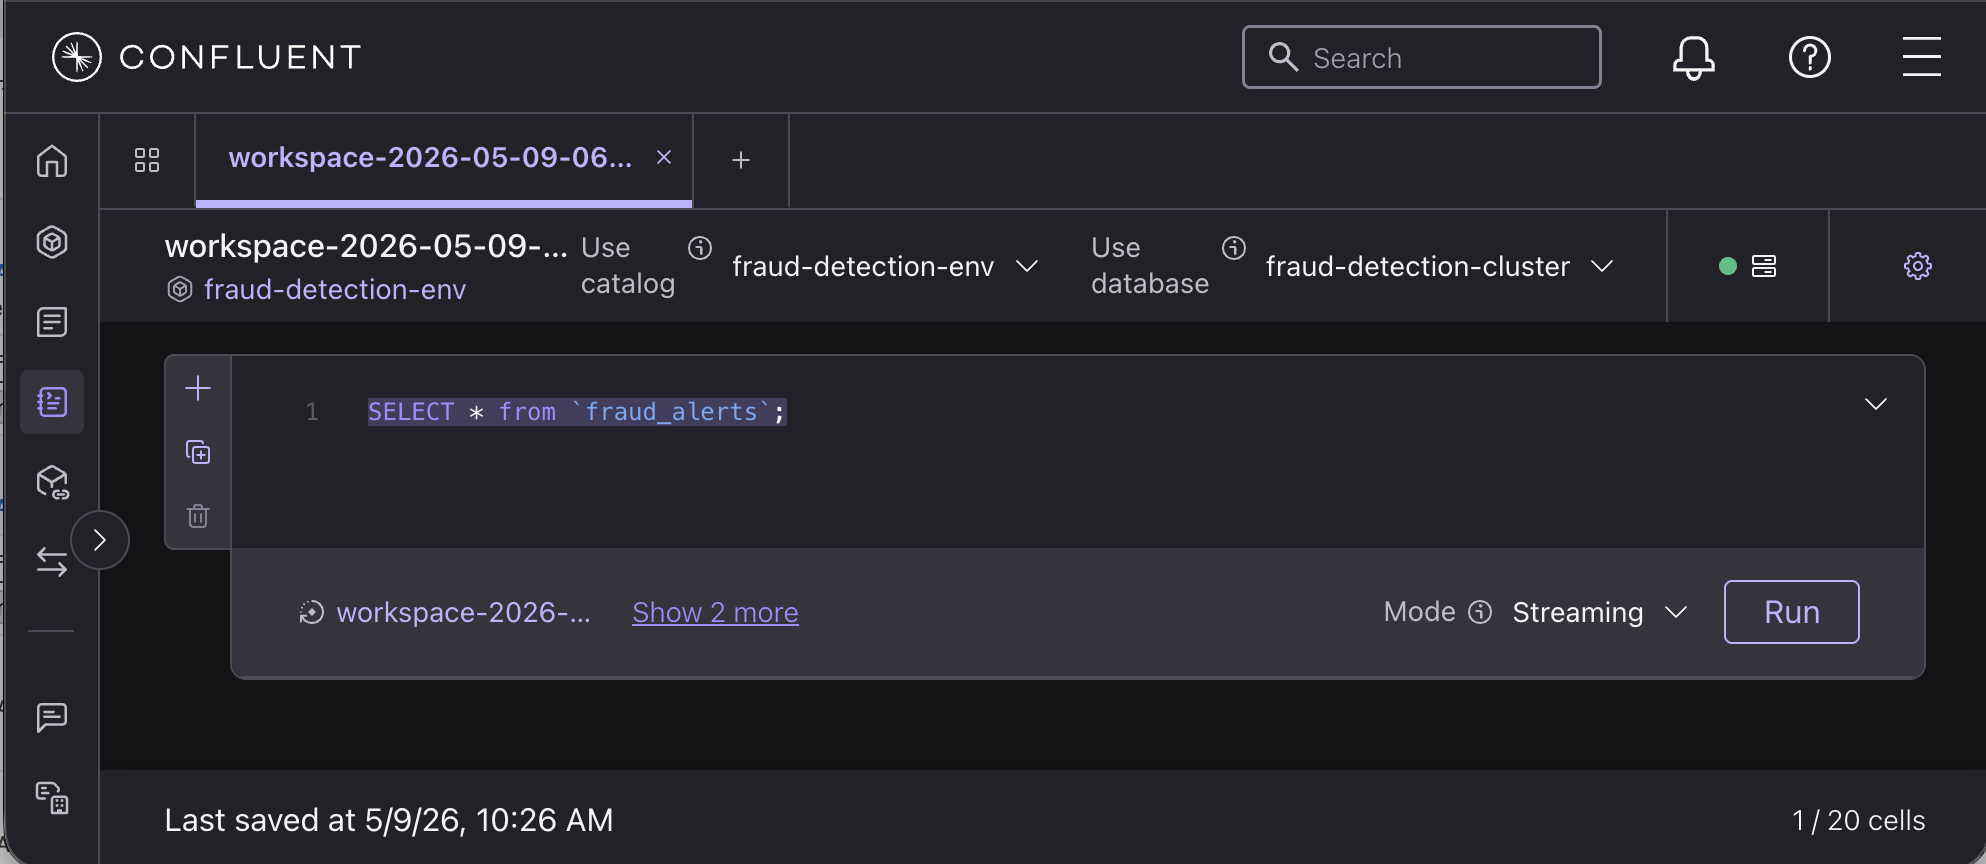
In real-time, Confluent detects the banking fraud. (You can connect to AI agents on watsonx Orchestrate to take actions in real-time, as described in this tutorial).
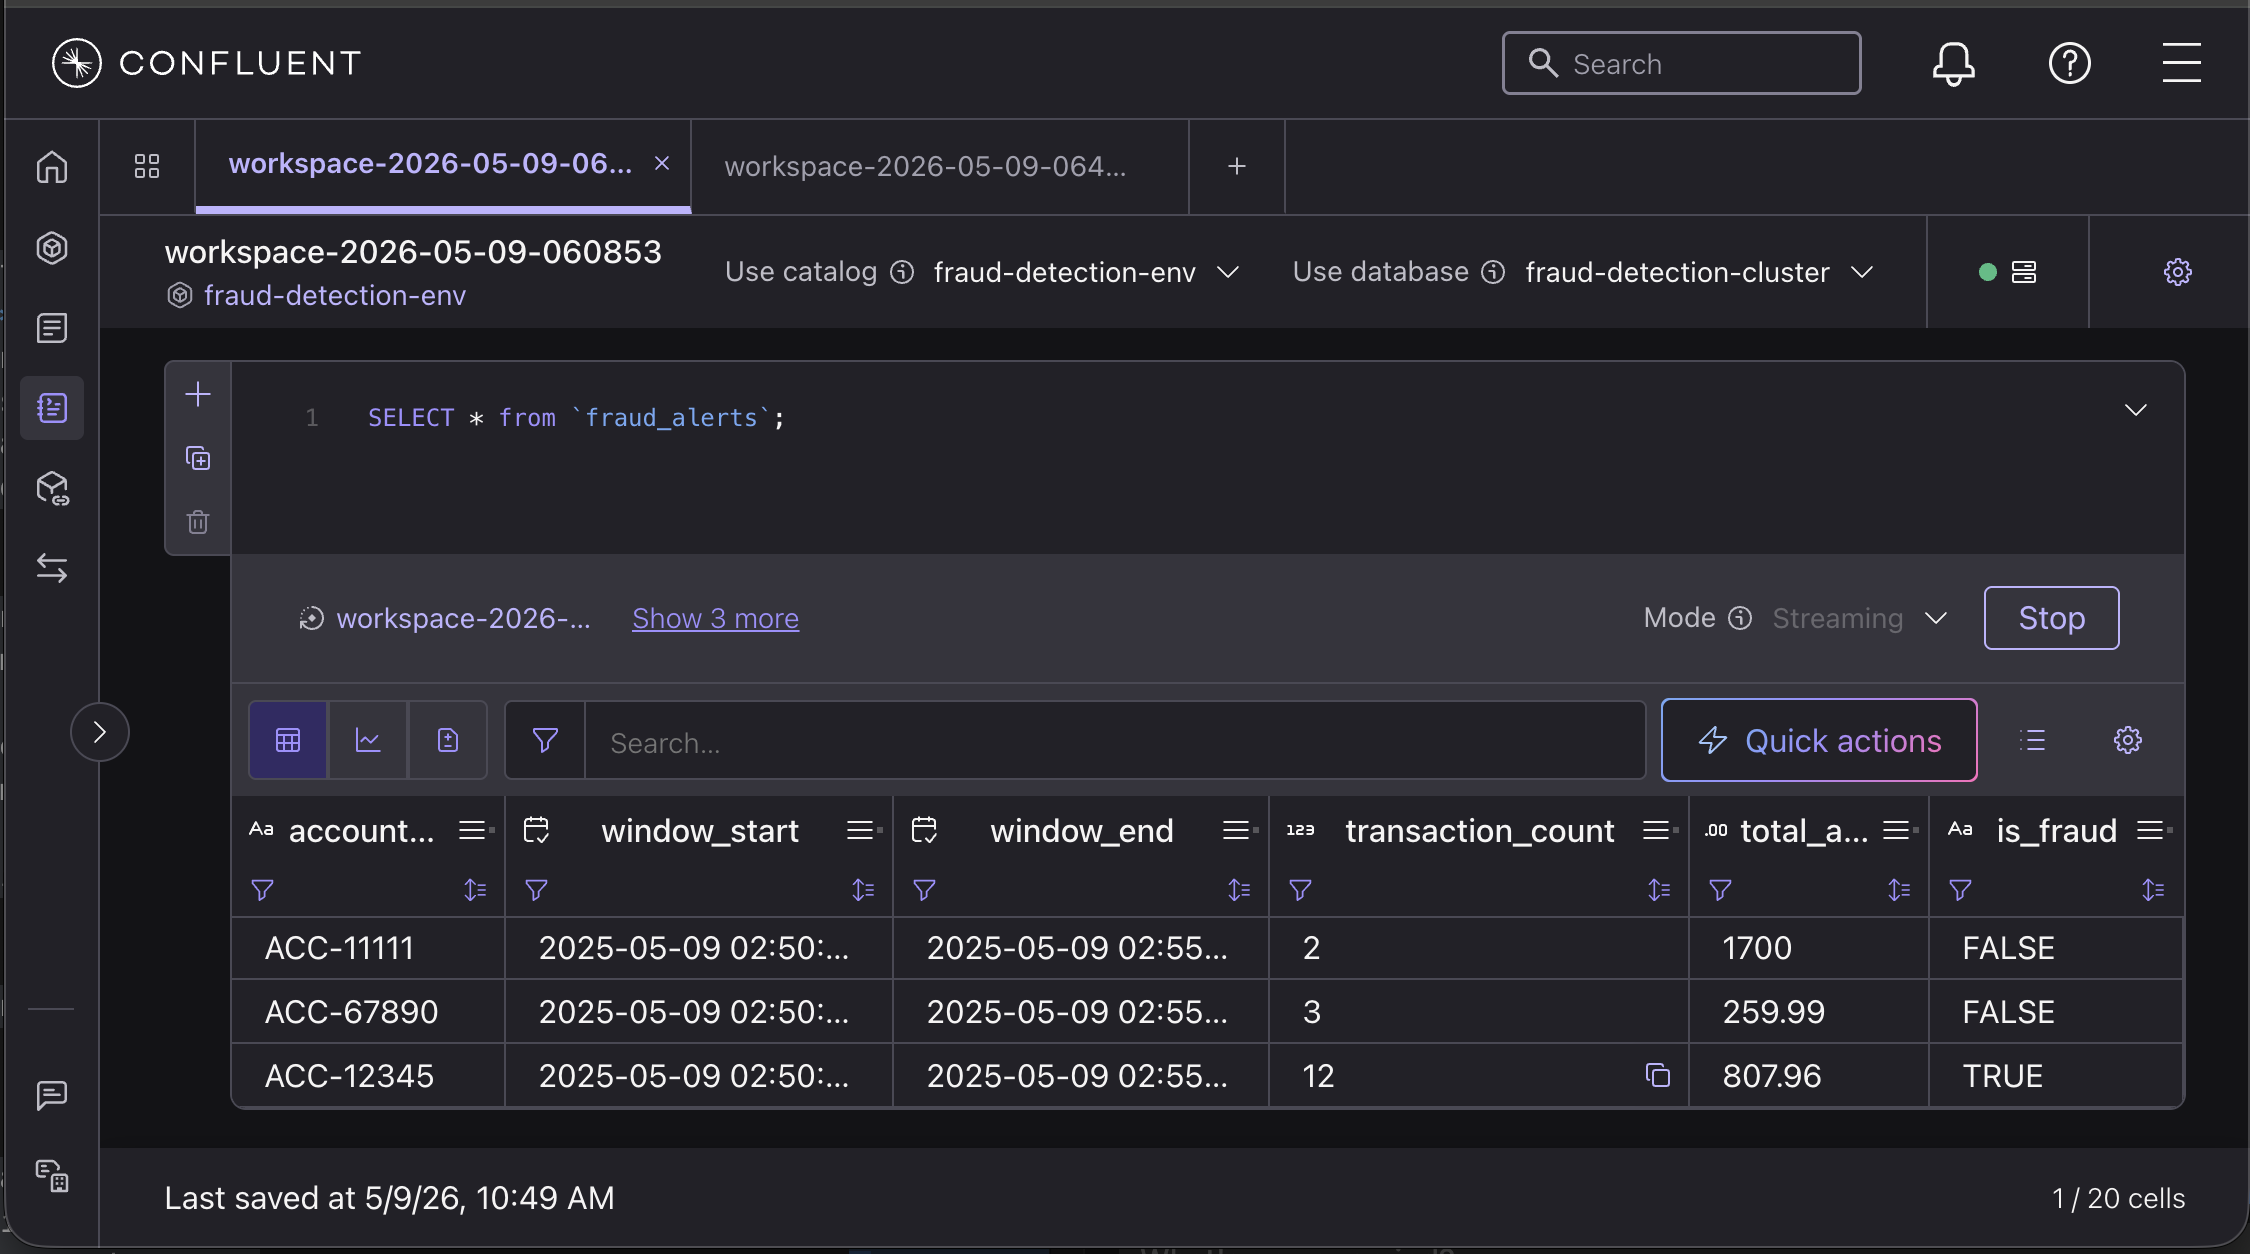
If no results appear, ask Bob to investigate.

Step 9. Clean up with HCP Terraform
HCP Terraform provides a controlled workflow for safely removing an environment. You create a destroy plan, review the proposed changes, and confirm the run before Terraform removes the managed resources.
Once you are done, make sure that you clean up the Confluent resources through HCP Terraform.
- Open HCP Terraform and go to Settings > Destruction and deletion.
Click Queue destroy plan to remove the Confluent Cloud infrastructure.
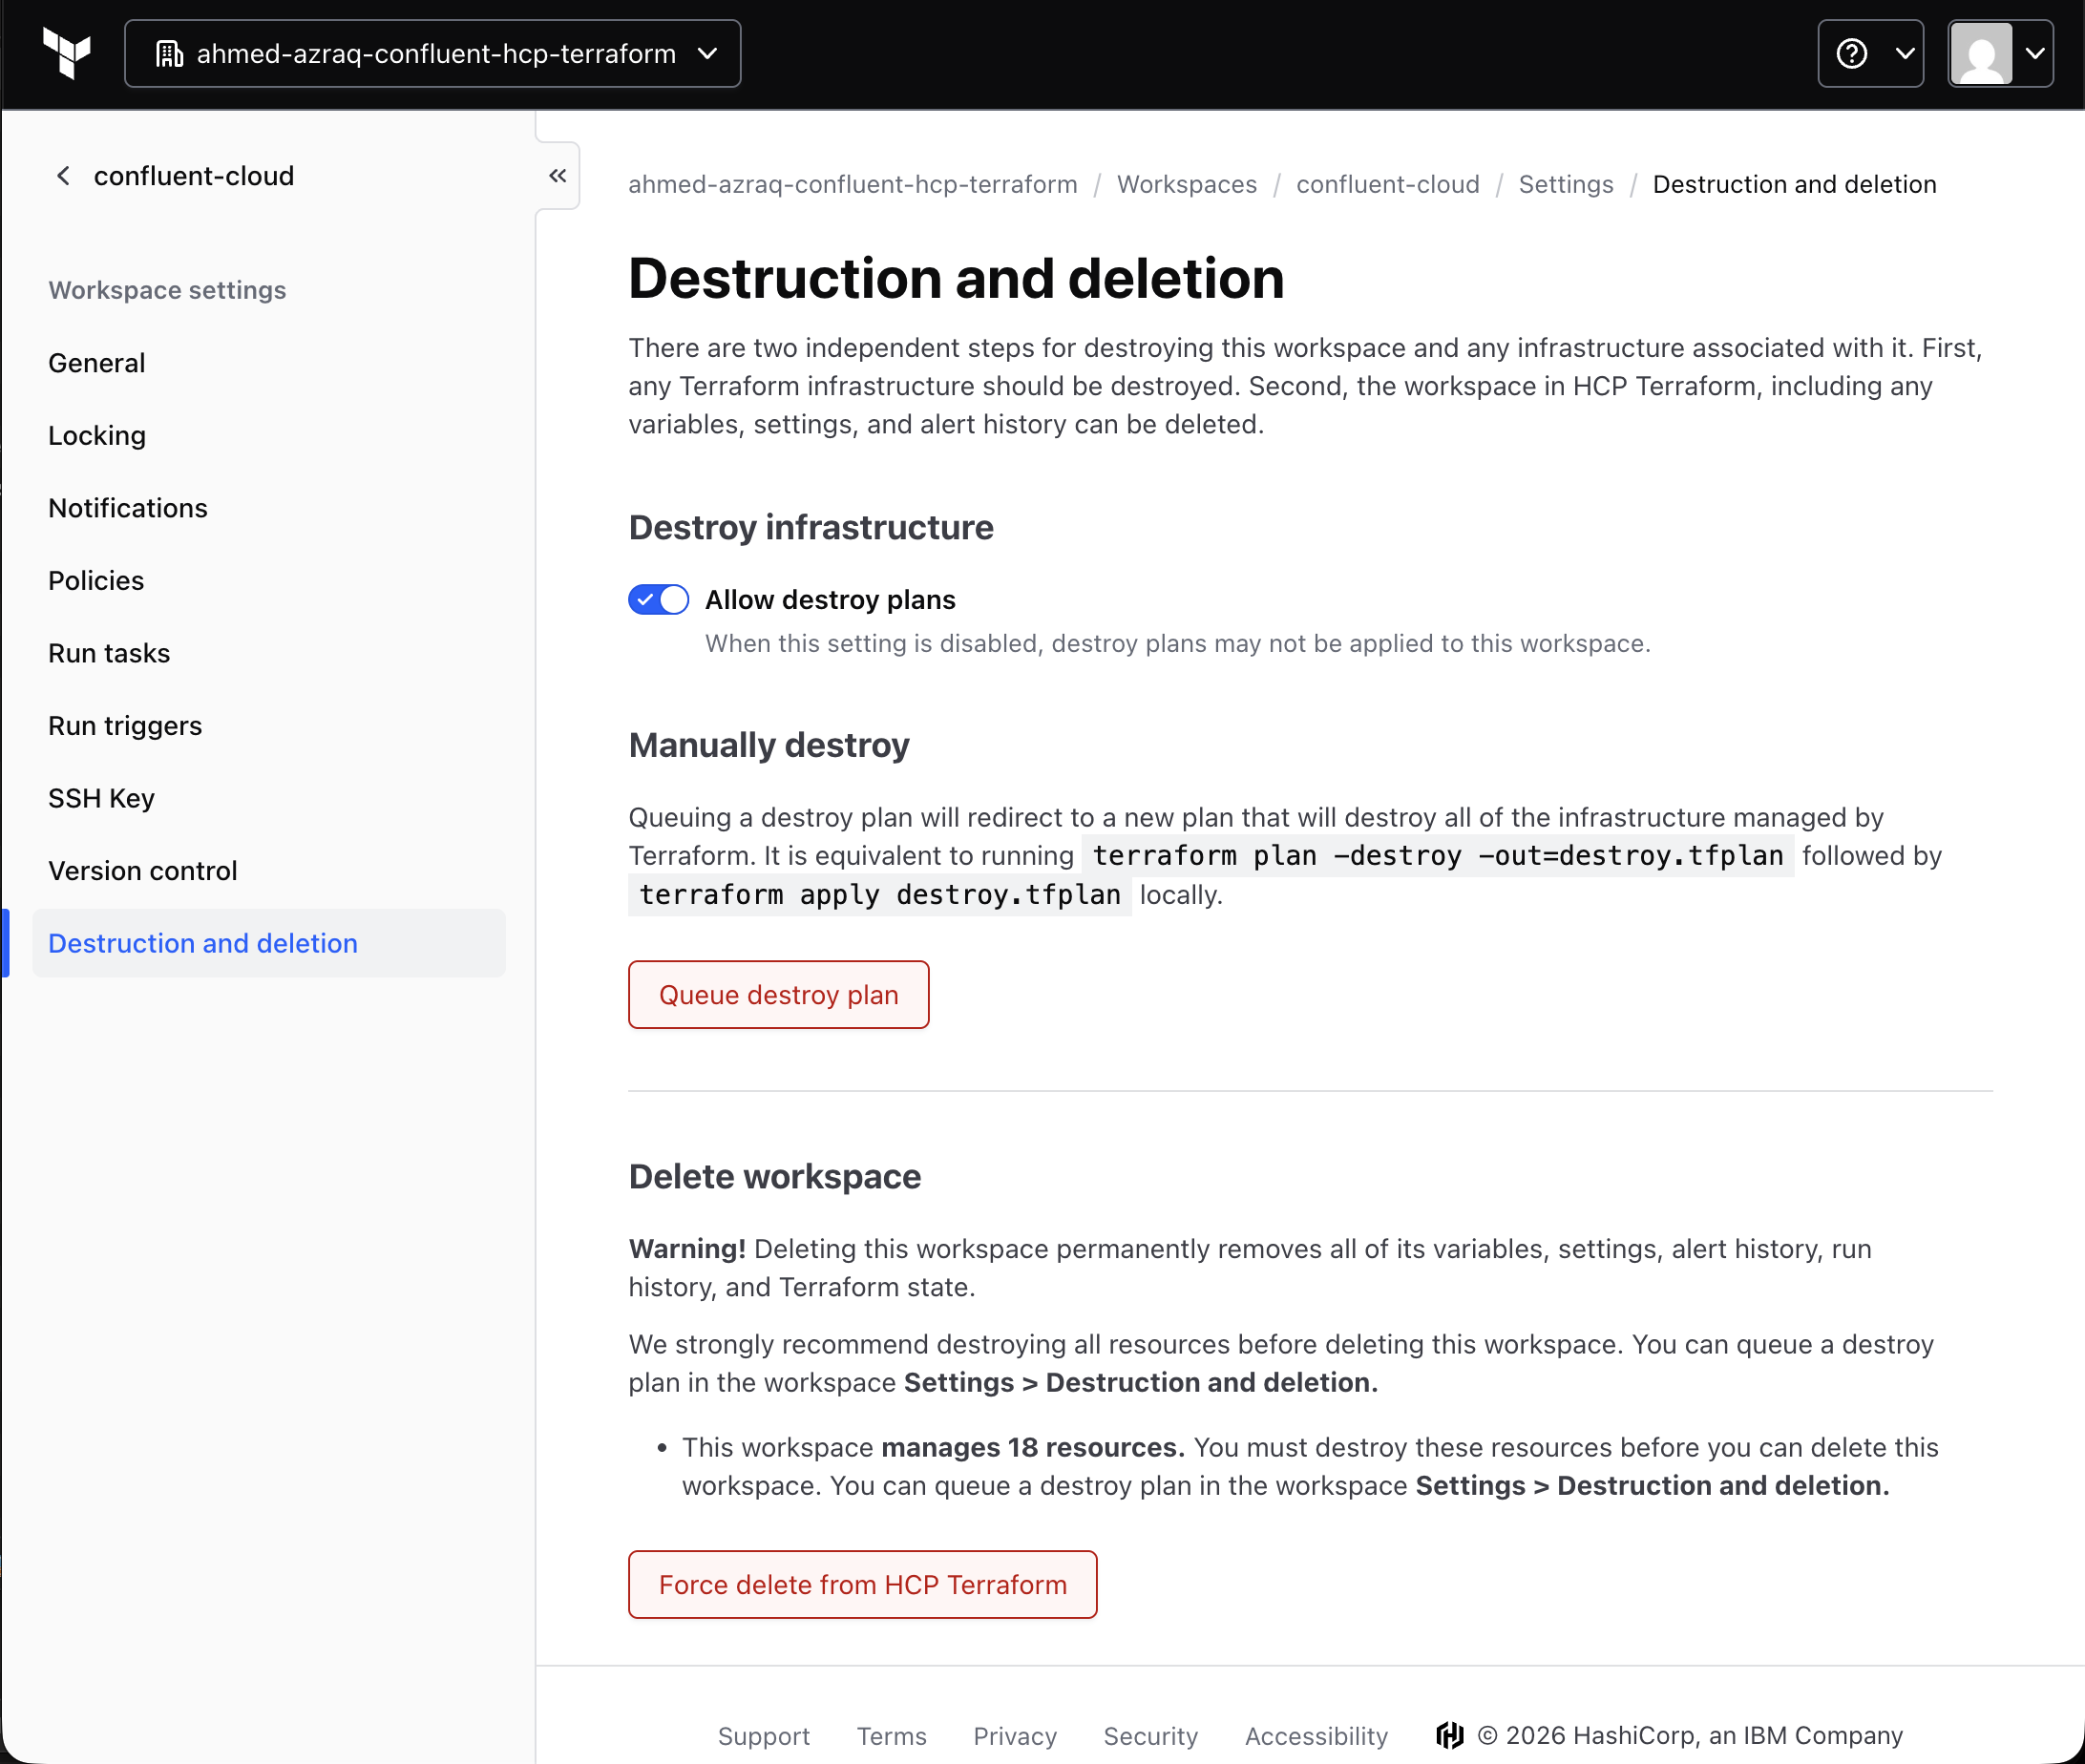
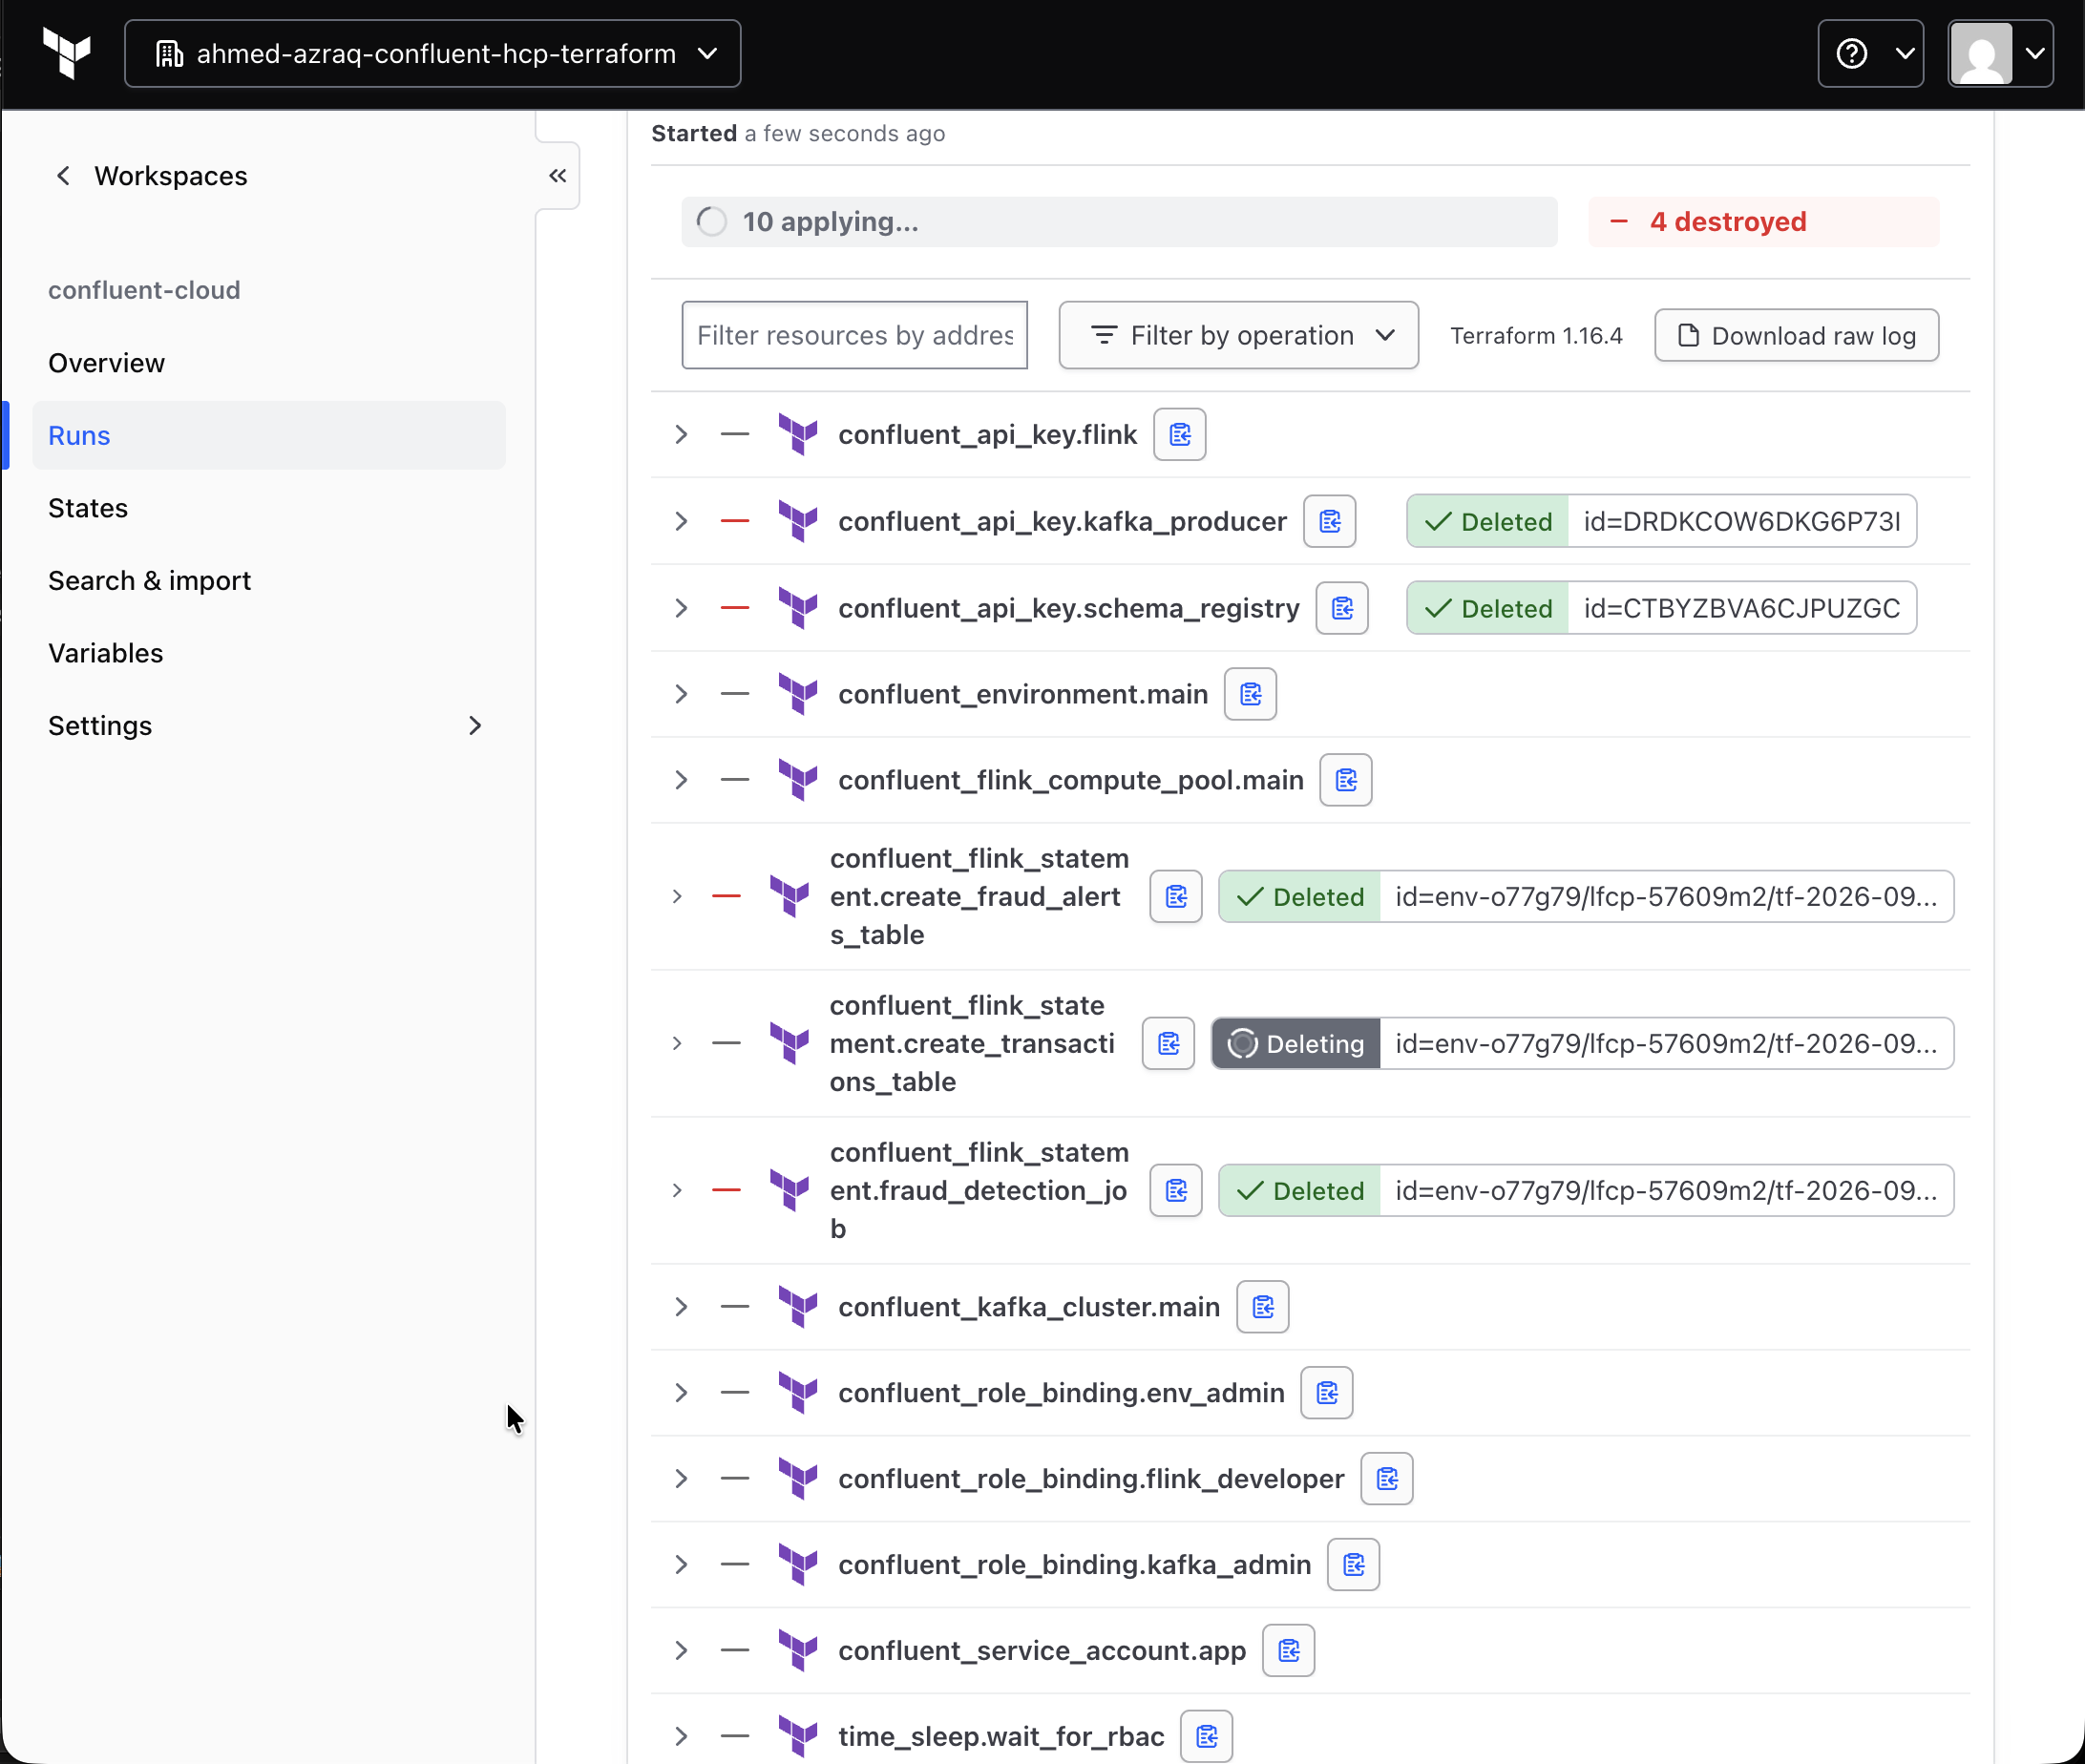
Review the resources that HCP Terraform will remove. Click Confirm & Apply to confirm the destroy plan.

HCP Terraform shows the destruction status in real time. Wait until HCP Terraform deletes all the resources.
Summary and next steps
In this tutorial, you learned how to use Bob to build a real-time banking fraud detection system with Confluent Cloud, Apache Kafka, and Apache Flink. You also used HCP Terraform to automate and manage the provisioning of the Confluent Cloud infrastructure.
You learned how HCP Terraform uses organizations and workspaces to manage infrastructure. HCP Terraform runs the Terraform configurations created by Bob, manages Terraform state, records run history, and provides a controlled workflow for removing infrastructure.
You also learned how Confluent Cloud provides a managed data streaming platform. Apache Flink processes Apache Kafka events in real time. With Flink SQL, you filtered, joined, enriched, and transformed streaming data without managing the underlying stream processing infrastructure.
This is a summary of the tasks accomplished by Bob.
You can also explore how Bob helps connect agents to real-time events processed by Confluent Cloud for Apache Flink in this tutorial: Build an event-driven agentic AI system with Confluent Cloud for Apache Flink and watsonx Orchestrate using IBM Bob.
Acknowledgments
This tutorial was produced as part of an EMEA initiative sponsored by Ralph Demuth, the Building Blocks initiative sponsored by Jason Gartner, and the IBM Open Innovation Community initiative to develop tutorials and learning content for integrating IBM Bob with other products.
The authors (Ahmed Azraq and Brice Leporini) appreciate the support of Frank Ketelaars, Carmen Raileanu, Luigi Vincenzo Molinaro, Carlo Appugliese, and Himangshu Mech for reviewing and contributing to the tutorial.